About Continuous Function
Continuous Function is a course of 56 notebooks on the mathematics and mechanisms of machine learning, a lab of investigations that run in your browser, and research questions written down before any study is run. This page describes each part and why the site exists, then shows selected work, explains how the site is made and lists what is not built yet.
What the site offers
The parts are meant to be taken in order: the curriculum explains the mechanisms, the lab asks what a result about them actually supports, and the research pages set out questions that neither can answer yet. For now the parts mostly stand alone. One investigation takes a single question from a first look to a result someone else can rerun; the curriculum, the other investigations, the research drafts and Verify do not yet feed into one another, and there is no shared space where people work together.
The index of concepts lists the notebooks, foundation pages, standalone notes and sources by name. It arranges the notebooks in 12 topics, from linear algebra to LLM systems.
Why
Continuous Function exists so that people keep the understanding and the judgment to decide which questions matter, what would count as evidence, and whether a result actually supports a claim.
The curriculum presents the mechanisms of machine learning through explanation and calculation, and the lab and Verify make explicit the assumptions behind reading a result. As AI systems take on more of the work of building AI, the people responsible for that work need to understand what changed and why, and to be able to question or stop it. The longer aim of the project is tools and habits that make this possible. It is a direction, not something the site does today; the vision page sets it beside what you can try now.
The principles, the research loop and the exact status of every research question are set out below, in how Continuous Function works.
Status
The site has no accounts, advertising or analytics, and its tools run in your browser. Because it collects no analytics, we make no claim about how many people use it. The learning pages have not been evaluated in a study with learners. The research pages are proposals: no study has been run and no results are reported. The source repository is private.
Selected work
For anyone deciding whether to use, fund or collaborate with Continuous Function: an investigation that refits a real classifier in your browser, worked calculations in attention and transformer systems, a reader for paired evaluation scores, the checks the code must pass and a research proposal that has not been run. Each entry takes a few minutes and closes with what to inspect, what it does not establish and where to look. Updated 2 October 2026.
Workspace: steering a real model failure
Waterbirds is a benchmark of bird photographs placed on land or water backgrounds; in its training set most waterbirds appear on water and most landbirds on land, so a classifier can score well by reading the background. A frozen ImageNet ResNet-50 with a logistic-regression readout is right 97% of the time on Waterbirds photos mixed in the same proportions as its training data, yet gets only 37 of 69 validation photos of waterbirds on land right (on a 64-dimensional projection of its features). The workspace takes that failure through the steps of a careful experiment: predict the outcome, set limits a fix must respect, approve a plan, refit the last layer in your browser, look once at the held-out test images through a separate check, narrow the claim to what the evidence supports, and export a file that anyone can replay run by run or adapt. The test suite checks the in-browser fits against scikit-learn for every run of the reference plan, to within one image per group.
Enforcing the rules of a careful experiment in code rather than in instructions: a plan runs only after it is approved, every candidate is checked against the limits, and the test images can be opened once. The statistics are stated and tested.
Sagawa et al. (2020). Distributionally Robust Neural Networks for Group Shifts: On the Importance of Regularization for Worst-Case Generalization. ICLR. arXiv:1911.08731
Kirichenko, Izmailov and Wilson (2023). Last Layer Re-Training is Sufficient for Robustness to Spurious Correlations. ICLR. arXiv:2204.02937
- What to inspect
The workspace calls approving a plan “inking” it and keeping the test images hidden “sealing” them. Ink the suggested plan without keeping the test images sealed and see what changes; then try to ink a claim that says the refit “removes” the shortcut.
- Limits
One dataset, one frozen encoder projected to 64 dimensions, and an assistant whose lines are written in advance; no AI model is called. Because everything runs in your browser, the sealed test images are hidden by the page, not kept secret from you.
- Where to look
Transformer systems: KV memory and serving trade-offs
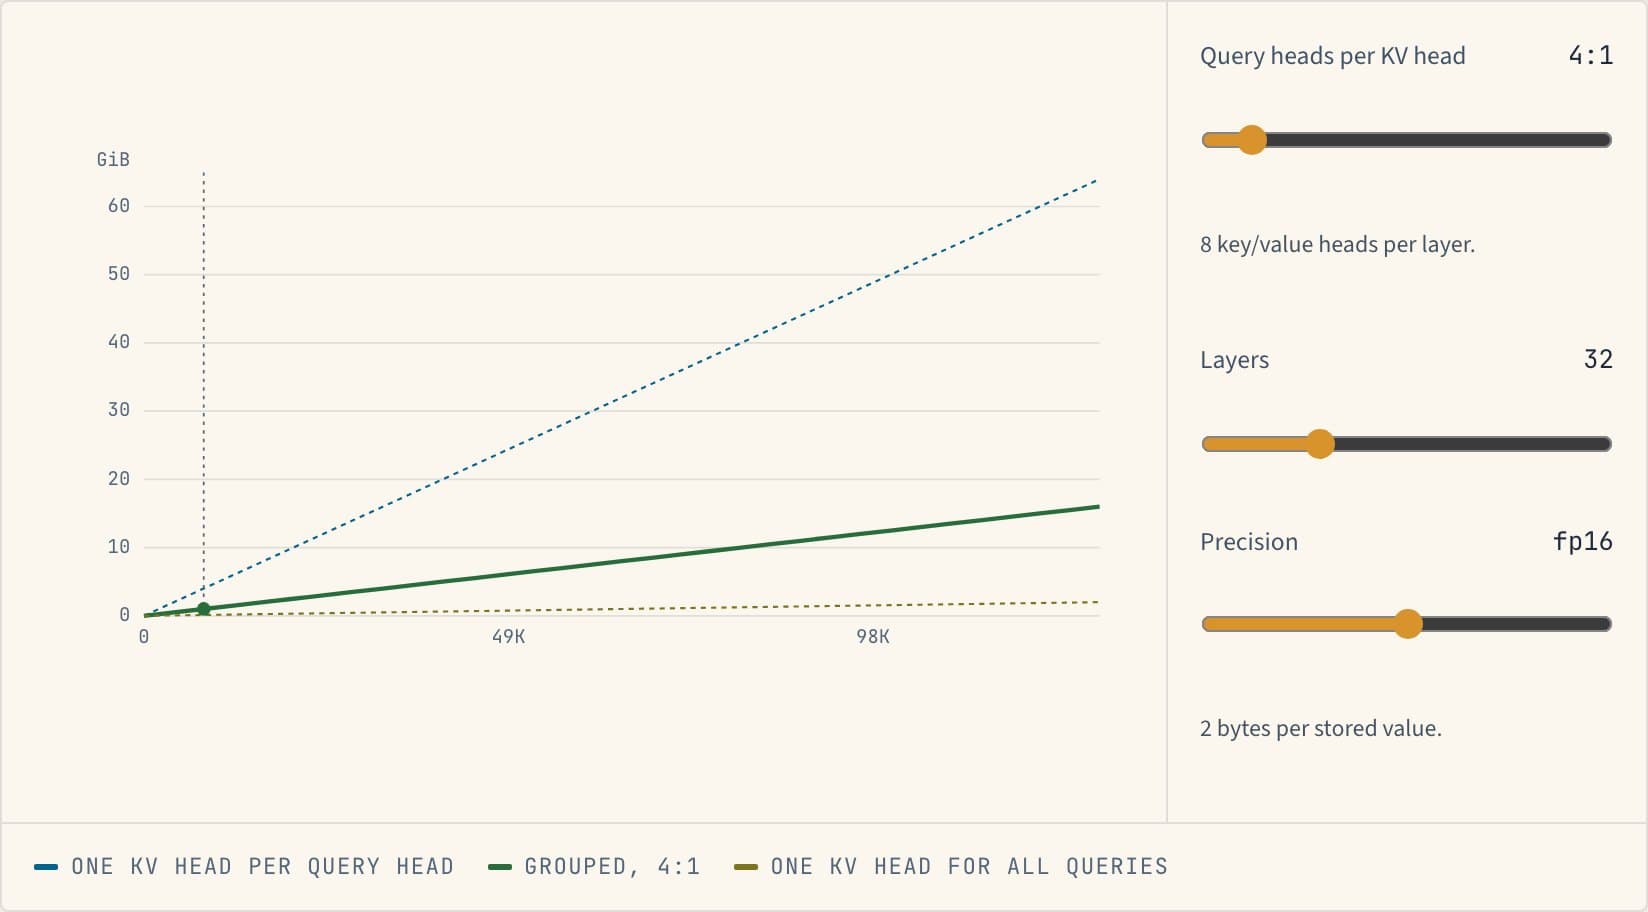
The Lab follows a transformer in eight steps, from one gradient update to a claim about a serving trade-off: rotary position embeddings, grouped-query attention and the KV cache, long context, batching and decoding, speculative decoding, evaluation design, and a final step where you state a systems claim and what it does not cover. Where a step asks for your prediction, it does so before it shows the calculation.
Connecting a systems quantity to its equation, a visual comparison and an interface control.
- What to inspect
Change how many query heads share each key/value head and trace which stored quantity changes, then check the formula printed beside the chart.
- Limits
The figure computes cache size from the formula printed beside it. It is not a measured speedup or a model-quality result.
- Where to look
Attention: one calculation in mathematics, code and controls
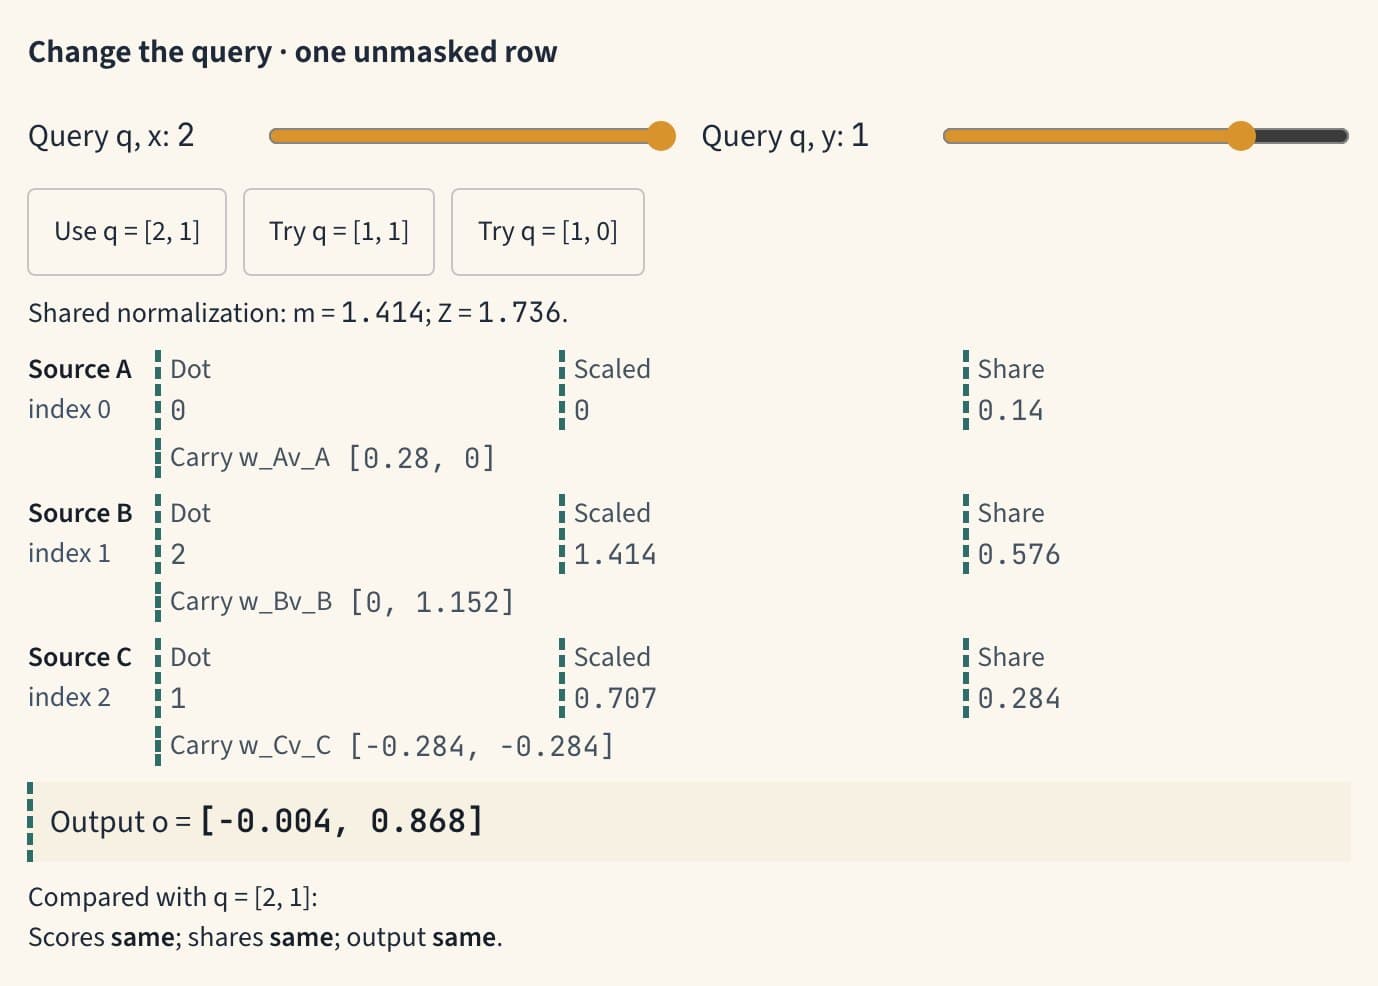
The attention notebook is built around one small example: a query, three sources, and the scores, weights and output they produce. The explanation, the equations, the Python and the interactive figure describe the same calculation, so a statement made in one of them can be checked in the others.
Keeping every symbol, numerical detail and line of code tied to one example.
- What to inspect
Change the query and notice which quantities move. Then choose the step “4 · Mixture”, which shows a slider for the x coordinate of source A’s value, and move it: the scores and weights stay the same, because they depend only on the query and the keys, while the output moves, because it also depends on the values. The notebook can export the current example as a Python notebook, and the site’s tests run that Python and compare it with the in-browser calculation.
- Limits
The export check covers the examples the tests run. The notebook has not been evaluated in a study with learners, so nothing here shows how well it teaches.
- Where to look
Verify: what a paired evaluation supports
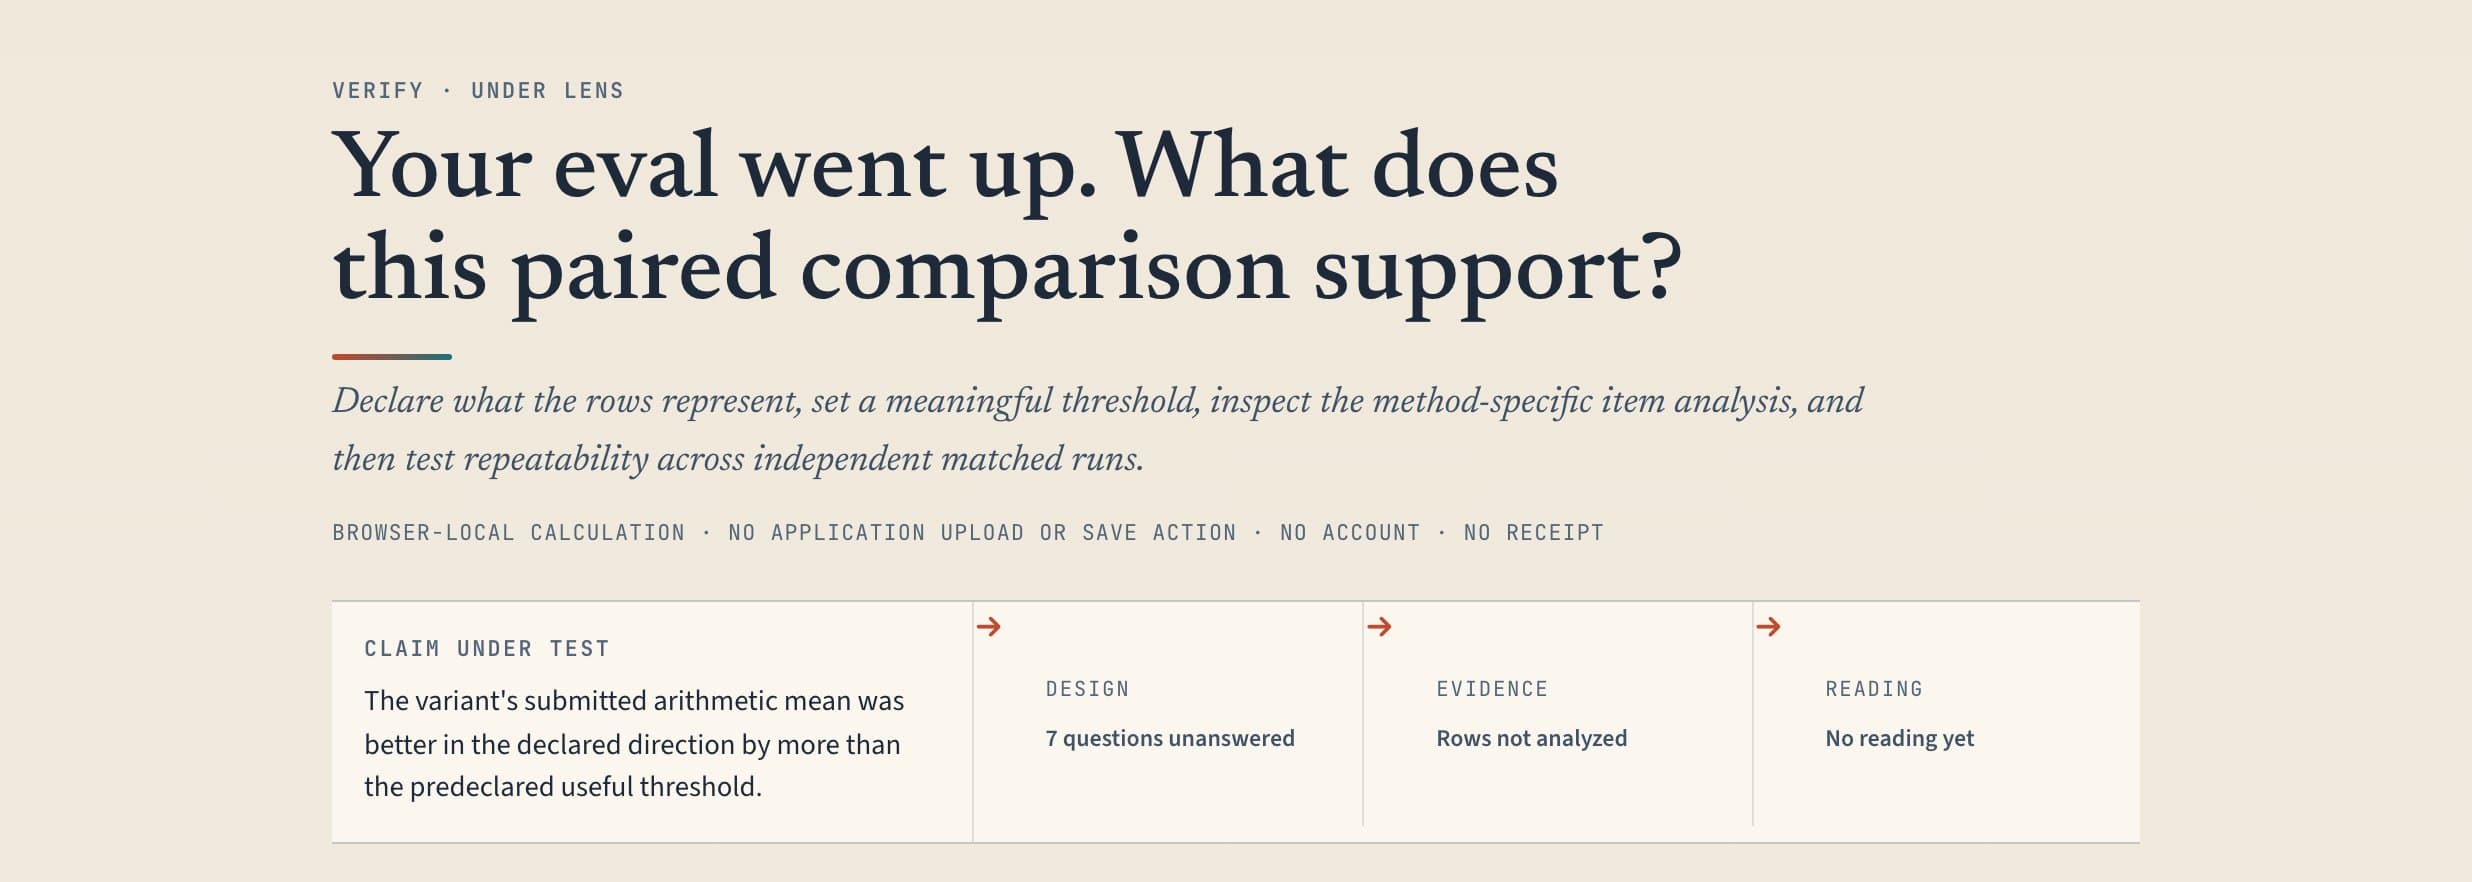
A variant scored higher than a baseline on the same items. Verify examines what that paired comparison supports under the assumptions you declare: which direction counts as better, what the items represent and the smallest difference that would matter.
It applies McNemar’s test with a Newcombe interval to exact 0/1 pairs, and a paired Student-t interval only when the declared assumptions support one. Repeatability is a separate test across at least five independent matched reruns. Based on your declarations, it declines designs outside its supported assumptions, such as clustered, weighted or repeated-generation evaluations, rather than approximating them; it does not verify the declarations.
Separating a calculation on submitted scores from claims about how the experiment was run.
McNemar (1947). Note on the sampling error of the difference between correlated proportions or percentages. Psychometrika 12, 153–157. DOI
Newcombe (1998). Improved confidence intervals for the difference between binomial proportions based on paired data. Statistics in Medicine 17, 2635–2650. DOI
- What to inspect
Describe the rows as a fixed evaluation set and then as an independent sample, and see how the reading changes. Then see what it declines to compute.
- Limits
Runs entirely in your browser. It reads the numbers you enter; it does not run models or check that your declarations are true.
- Where to look
How it is built and checked
The site is a statically generated Next.js and TypeScript application with no accounts, advertising or analytics; interactive state stays in your browser. Two checks show how correctness is handled:
- The attention notebook’s Python export is executed by the test suite and compared with the in-browser calculation and with an independently worked example.
- The gradient-descent lesson once misclassified the critical step size, where the iterates neither shrink nor grow. The fix came with a test that checks all 1,288 slider settings against exact rational arithmetic.
Continuous integration is set up to run the unit tests, browser tests at desktop and phone widths (including keyboard use), content validation and a production build on every pull request. Much of the code is written with AI coding assistants under our direction, and it has to pass the same checks as any other change; How this site is written describes this in full.
Turning a failure into a repeatable check, and saying what the check does not cover.
- Limits
The checks cover the behavior they test, not every possible use. The source repository is private, so these checks are described here rather than linked.
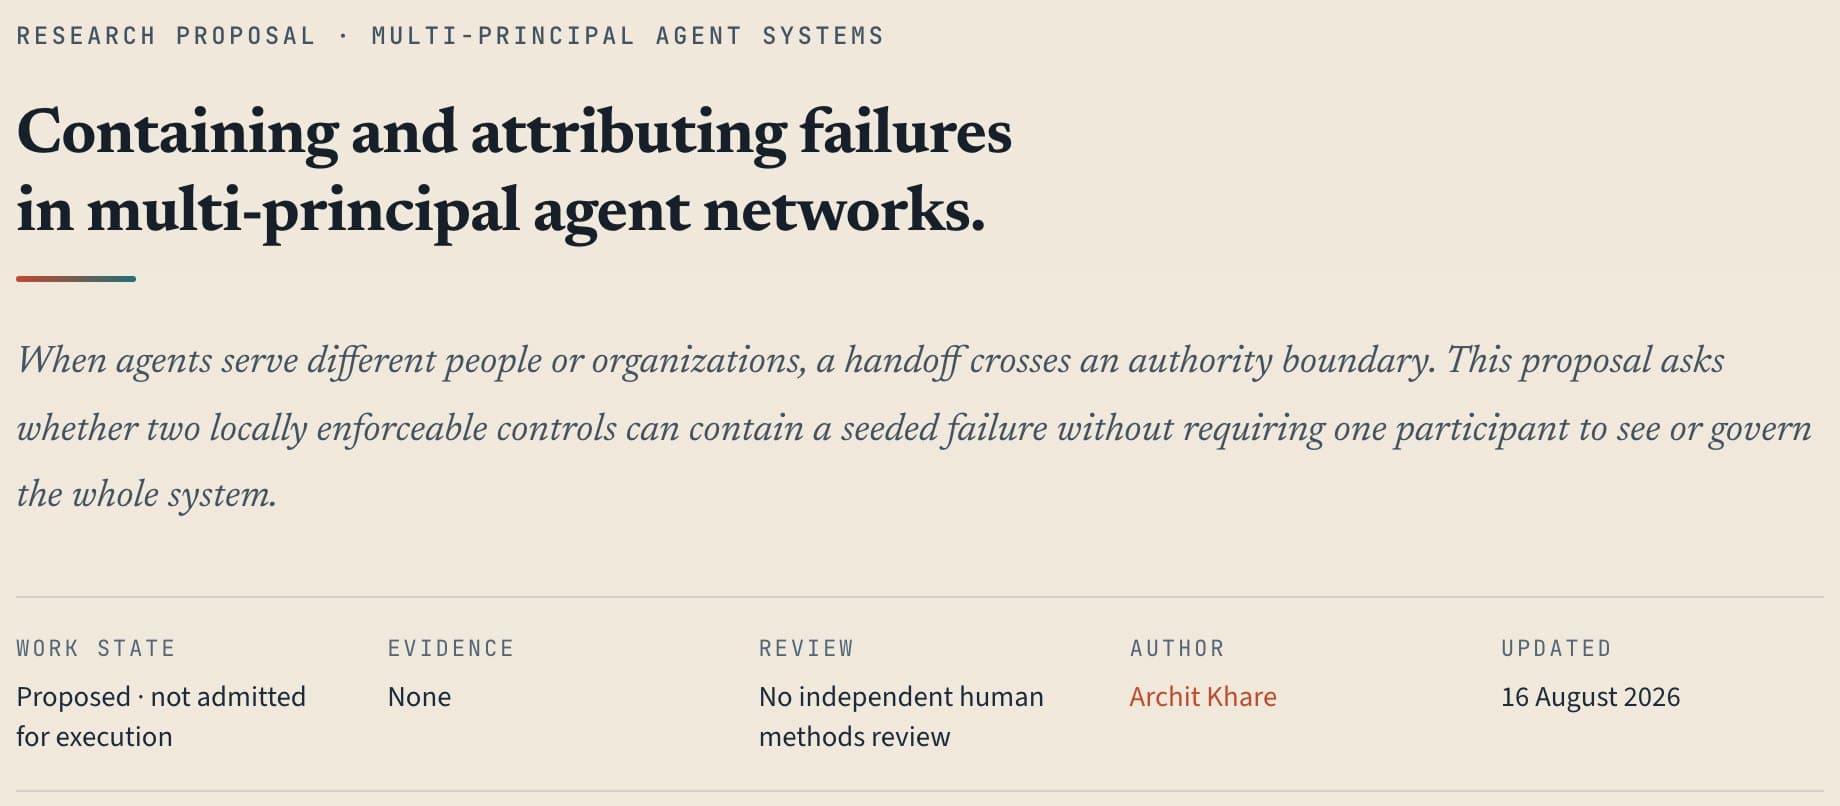
Research proposal: multi-principal agent networks
Status. This proposal has not been run. It is presented here as a design example, separate from the current research question on the Research page.
When AI agents act for different people or organizations, a handoff between them crosses an authority boundary. This proposal asks whether two controls that each participant can enforce locally can contain a seeded failure without anyone having to see or govern the whole system, and whether the failure can then be attributed.
Separating prevention from attribution, and stating in advance what would count against each claim.
- What to inspect
The two controls, each tried alone, together and not at all; the separate check that legitimate work still completes; the negative control, an authorized but false assessment that can pass both controls; and the conditions under which the proposal should not be run at all.
- Limits
No empirical results and no independent human methods review.
- Where to look
What the site does today, how it works, and what is not built.
As AI systems take on more of the work of building AI, the people responsible for that work need to understand what changed and why. Continuous Function is an independent research project that works on one part of this: helping a person understand the mechanisms of modern machine learning and judge what a result actually supports. Today it offers a curriculum, investigations that run in your browser, a reader for paired evaluation scores, and research questions written down before any study. This part sets out the principles behind it, what each part does, what is stored, and what does not exist. The project is free to use.
The longer-term direction, and the small part of it you can try today, are described on the vision page.
Principles
- People decide. A person chooses the question and its assumptions, what would count as evidence, how a result is read, and what is published.
- AI may propose, within limits. In the intended design, an AI system could suggest, search, write code and run work, but only inside limits a person sets, and it could not change the question, the standard of evidence, the conclusion or what is published. None of this is built: no AI agent works on this site, and no service runs experiments for you.
- Predict before you look. Some investigations ask for your prediction before they show a result and record it first, so that the result has something honest to be compared with; others ask you to inspect, change, compare or explain instead. There is no score. In Verify you may calculate first, but its questions about the design stay open until you answer them.
- Say what a result does not show. In the lab, each toy result is calculated in your browser from the settings shown; it is not a measurement from a production model. Where a page cites a paper, the source is linked next to the claim it supports.
- Carry forward only what was reviewed. In the intended design, only work a person has reviewed would feed into later work. No shared record of this kind exists yet.
What exists today
Five parts of the site exist today. One investigation, the workspace, takes a single question from a first look to a result someone else can rerun; the other parts stand alone, and together they are not yet one connected research environment.
Preparation is under way for a first walkthrough with consenting participants. It would test only whether the path is understandable: whether a person can build intuition from a notebook, make a prediction in the lab, turn the open point into a research draft, and see which evidence would settle it and what decision comes next. It has not happened, and our own rehearsals are not evidence that the path works.
After a reading, Verify may point to one related lesson, but it passes nothing to it: not the scores, the declarations or the reading. The lesson does not know which result brought you there.
The research loop
The intended loop has eight steps. People own every one of them; two are not built, and the site has no service that runs experiments for you.
- Learn: a person builds an intuition for the idea.
- Frame: a person states the question and its assumptions.
- Predict: a person commits to an expected result before seeing one.
- Delegate: AI systems would carry out bounded work inside the person’s limits. Not built.
- Experiment: small training runs can happen in your browser; larger runs happen outside this site today.
- Inspect: a person examines the evidence.
- Decide: a person decides what the result supports.
- Carry forward: only reviewed work would feed later work. Not built.
What is stored
Verify stores nothing: it creates no account, no saved record and no export.
Some lab pages and lessons keep your predictions, saved comparisons, place in a reading route or research drafts in this browser; others save nothing. None of it is shared with anyone, and it is kept apart from Verify. Your work lists your questions, projects, research drafts, saved investigations and ideas to review; some exercises keep your answers on their own page. Opening Your work reads those records and changes none of them.
The Research Workbench saves a draft in this browser automatically when storage is available and the draft passes its checks, and restores it when you return. The blank workbench and each starter draft are saved separately. Nothing is uploaded or synced to an account. If saving fails, the latest edits may exist only in the open tab. Resetting a draft asks for confirmation first, and exporting downloads a JSON file that you keep. A draft creates no run, evidence, approval or publication.
The workspace keeps your work in this browser’s storage, so after a successful save it is there when you return; a failed or cleared save, or a workspace replaced in another tab, is not recovered. “Forget this workspace” deletes it. Its package is a download you start. Clearing this site’s storage also resets the workspace’s one look at the test images.
Clearing this site’s browser data removes everything stored here, but not files you downloaded. The privacy notice also covers what the hosting provider processes when you visit.
What does not exist
There is no AI assistant answering on this site, no account system and no community features. No server runs models, evaluations or experiments for you. Some lab pages do compute, on your own device: one trains a small character-level transformer, Fieldwork trains a small network on synthetic data, and the workspace fits small linear readouts on fixed, precomputed features. Nothing they compute is uploaded, and the workspace’s assistant is scripted. Some concept pages have a button that copies a prompt written from the page and your selections, for you to paste into an AI assistant you already use; the page sends nothing itself.
On the research side, no study protocol is fixed, no study with participants is running, no independent review has taken place and no empirical evidence exists. An earlier question on alignment evidence is kept as a record but set aside; its earlier schedule no longer applies. Our full report of an earlier model-fusion case is not published and is not an accepted result. Where a page offers different points of view on an idea, such as a learner’s or a researcher’s, those are fixed texts, not people or contributions. A new capability will be described here as current only after it has been built and checked.
A site about judging evidence should not overstate its own capabilities.
What happens next
Verify. The version on this site is experimental. A revised version will replace it only after it has been reviewed and has passed further checks, including accessibility. The test that matters is whether someone outside the project can bring a real result to Verify, and whether it changes a decision they make.
Research. The feasibility check must stop the proposal, or send it back for revision, if any of these cannot be settled: earlier work on the same question, the exact sources and the rights to use them, keeping the compared conditions identical apart from the links, ethics, a route to qualified reviewers, the outcome measure, statistical power and the resources needed. A named person who did not design or carry out the check must then assess it, and even a favourable assessment would not by itself approve a study. Whatever happens to Verify, the earlier alignment-evidence question stays set aside. The Research page shows the absence of evidence as prominently as the question itself, and keeps proposed, set-aside and future work visibly separate.
The longer-term direction
The longer-term aim is a place where a person can follow a path into a difficult idea, work with AI systems whose work is limited and checked rather than taken on trust, and turn what they understand into research that others can inspect, following the eight steps above.
Learning, sources, predictions, study designs, evidence, decisions and reviewed corrections would stay attached to the same question, so that later teaching and later research build on what survived review rather than on an unexamined answer. AI systems might propose, challenge and carry out bounded work; people would keep authority over the question, the assumptions, the standard of evidence, the interpretation, the decision and publication.
If real use justifies it, the same records could support collaboration between people, between people and AI systems, and between AI systems acting with permission, and in time an open research institution whose shared knowledge consists of reviewed records and explicit disagreements rather than a feed of conversations or unreviewed AI output.
None of that exists today: there are no accounts, identities or permissions, no shared community, no live AI on the site, no agents running, no shared memory, no independent review workflow, no publishing and no automatic changes to the curriculum.
Who is responsible
Continuous Function sets its own direction and is responsible for everything the site says publicly. How the site is written is described below, and how to reach us at the end of this page. Independent review, wherever this site mentions it, means review by a named person who did not design the work.
How this site is written
We decide what the site covers, what it says and what is published. Much of the code, and many first drafts of the text, are written with AI coding assistants (Claude Code and Codex) working under our direction. Every change has to pass the same automated checks: unit tests, browser tests, content validation and a production build, and the numbers in many figures are checked by tests against their equations and code. Some lessons have also been checked by AI models for mathematical and teaching errors; we treat that as advice to verify, not as review. No lesson has yet been reviewed by an independent expert. Corrections are welcome at the address below.
Contact
For corrections, questions about the curriculum, or research collaboration, email founder@continuousfunction.ai. The contact page says what to include. For a short tour of what to inspect first, see selected work above.