Why it is cited
Grounds inner products, vector geometry, and the linear algebra notation reused across attention and optimization.
The dot product measures alignment: it connects angles, lengths, and projections, and underlies cosine similarity in ML.
The idea in plain words, before the symbols.
The dot product answers the question: “How much does one vector point in the direction of another?” Its value depends on both vectors' lengths and their relative direction.
In ML, dot products serve as similarity scores and compare queries with keys in attention. Cosine similarity instead divides the dot product by the product of the vectors' lengths; it is defined only when both vectors are nonzero.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
Let , with coordinates
The dot product is the coordinate-wise multiply-and-sum operation
This definition is algebraic, but it is designed to preserve geometry. The squared length of a vector is
so . If is the angle between two nonzero vectors, the same operation satisfies
You can read this as:
That ratio is cosine similarity. It removes the lengths and keeps only direction, which is why embeddings often use it as a normalized similarity score.
That immediately gives:
The scalar says how many copies of fit inside the part of that points along . The leftover
is perpendicular to , because
In dot-product attention, this same operation appears as : the score depends on both vector lengths and their relative direction. With nonzero lengths held fixed, a smaller angle gives a larger score; when key lengths differ, the most aligned key need not receive the largest score.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
import numpy as np

u = np.array([2.0, 1.0])
v = np.array([-1.0, 2.0])

dot = float(u @ v)
nu = float(np.linalg.norm(u))
nv = float(np.linalg.norm(v))
cos = dot / (nu * nv)

proj_u_on_v = (dot / float(v @ v)) * v

print("u·v =", dot)
print("cos(theta) =", cos)
print("proj_v(u) =", proj_u_on_v)
print("perp component =", u - proj_u_on_v)
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Row 0 (A) · unmasked projection.
One query · three sources · one continuous example
Drag q and watch three steps happen at once: match (how far q reaches along each key), share (softmax splits the attention) and mix (the output blends the values). You can explore before answering anything; go at your own pace.
Given vectors for one unmasked head, not learned word meanings.
q = [2, 1] · Compare the query with each key.
Drag anywhere in the plane, or focus q and use the arrow keys.
Softmax exponentiates each score, then divides by the total. Only differences between scores matter.
Coloured arrows add w·v for each source, tip to tail. The output can never leave the triangle. The view fits the values with equal units on both axes.
q lines up most with B’s key (score 1.414), so B takes 58% of the attention; C gets 28% and A gets 14%. Output o = [-0.004, 0.868].
Give source B more than 90% of the attention.
A 31-second guided explanation of the starting A/B/C example. This is fixed, silent playback with captions; it does not follow or reset your experiment.
Displayed numbers are rounded. This hand-authored, unmasked example explains one attention calculation; it is not a trace from a trained model.
Shared normalization: m = 1.414; Z = 1.736.
Output o = [-0.004, 0.868]
Compared with q = [2, 1]:
Scores same; shares same; output same.
Worked example, not a test or model run. Given vectors, not learned meanings. Match the query with keys; mix values, not keys. All three sources are allowed in this view.
sum(qj * kj for qj, kj in zip(q, k)) / sqrt(2)exps = [exp(s - max(scores)) for s in scores]weights = [e / sum(exps) for e in exps]sum(w * v[j] for w, v in zip(weights, values))m is the shared maximum scaled score; Z = exp(s_A − m) + exp(s_B − m) + exp(s_C − m). Subtracting the same maximum avoids large exponentials without changing the shares. Each carry is a weighted source value; sum the three contributions coordinate by coordinate for output o.
The reference uses the same current keys and values, with q = [2, 1]. Not every query edit changes the mixture. Solid amber borders mark numerical changes; dashed teal borders mark values unchanged within 1e-12. Labels round to three decimals, not the calculation.
Finite JavaScript numbers before display rounding; −0 is kept where supplied. Tiny allowed shares can underflow to zero; that is not a mask.
q = [2, 1]
A: key=[-1, 2]; value=[2, 0]; dot=0; score=0; share=0.14002924504337802; contribution=[0.28005849008675604, 0]
B: key=[1, 0]; value=[0, 2]; dot=2; score=1.414213562373095; share=0.575975345215362; contribution=[0, 1.151950690430724]
C: key=[0, 1]; value=[-1, -1]; dot=1; score=0.7071067811865475; share=0.28399540974126003; contribution=[-0.28399540974126003, -0.28399540974126003]
m=1.414213562373095; stable denominator=1.736185425829454
output=[-0.00393691965450399, 0.8679552806894639]
This runnable Python uses the current controls and the same labels. No NumPy or random inputs are needed.
Float operands and left-to-right sums from 0.0 follow browser accumulation, not exact arithmetic. Cancellation can hide a nonzero exact change; exp/sqrt implementations and display rounding can differ across runtimes.
from math import exp, sqrt

labels = ["A","B","C"]
q = [2.0, 1.0]
keys = [[-1.0, 2.0], [1.0, 0.0], [0.0, 1.0]]
values = [[2.0, 0.0], [0.0, 2.0], [-1.0, -1.0]]

# Float operands and left-to-right sums from 0.0 follow browser accumulation.
# Cancellation can hide a nonzero exact change. This is not exact arithmetic;
# exp/sqrt implementations and display rounding can differ across runtimes.
def ordered_sum(terms):
    total = 0.0
    for term in terms:
        total += term
    return total

d_k = len(q)  # key dimension, NOT number of sources or value width
raw_scores = [ordered_sum(qj * kj for qj, kj in zip(q, k)) for k in keys]
scores = [s / sqrt(d_k) for s in raw_scores]
exps = [exp(s - max(scores)) for s in scores]
total = ordered_sum(exps)
weights = [e / total for e in exps]
output = [ordered_sum(v[j] * w for w, v in zip(weights, values))
          for j in range(len(values[0]))]

for label, raw, score, weight in zip(labels, raw_scores, scores, weights):
    print(label, round(raw, 3), round(score, 3), round(weight, 3))
print("output", [round(x, 3) for x in output])
Browser reference output: [-0.004, 0.868] (rounded to three decimals).
Step 1 of 4 · Vectors
A, B, and C name the same three sources throughout. Compare q with their keys in key space. Their values are payloads in a different space, not arrows to compare with q.
These are optional inspection controls. The connected scores, shares and mixture stay visible in the explorable above.
Shapes: q and each k have d_k = 2 coordinates. Each v and the output have d_v = 2 coordinates. Equal widths here do not make the spaces identical.
q = [q₁, q₂]; k_A = [−1, 2]; k_B = [1, 0]; k_C = [0, 1]
i names a source; j runs over A, B, C. s is a scaled score, w its share, and o the output. Displayed decimals are rounded; calculations are not.
| Source | Key k | q |
|---|---|---|
| A | [-1, 2] | [2, 1] |
| B | [1, 0] | [2, 1] |
| C | [0, 1] | [2, 1] |
Reset example restores the query and first value’s x coordinate only. All other held inputs stay unchanged.
All sources are allowed here; this is not a masked sequence output. Query edits return to row 0; value edits are shared. Other rows and the held mask stay unchanged.
A study detour counts as consultation for the attempt you leave. Clearing a response or resetting values keeps its help history.
Held example · 3 queries · 3 sources. Started from the A/B/C sequence.
These record which help you used, not completion or learning scores. Each attempt keeps its own feedback and help. Reloading the page clears this history.
The figure opens on the place this operation is used next: attention. One query vector is compared with three key vectors, and each score is the dot product divided by , because the vectors have two coordinates. Drag and watch the first panel: the scores follow the lengths and angles described above. The other two panels, softmax and the weighted mix of values, are explained on the attention page.
For an exercise on this page's own mathematics, open Practice, help and export below the figure and choose Advanced demonstrations. Drag and , predict whether the signed projection of onto points with , nearly vanishes, or points against , then reveal it and compare the result with the signs of and .
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
What is the smallest example of Dot Product you can work through by hand, and what does it show?
concept:linear-algebra/dot-productAfter the first pass
Section by section
The dot product measures alignment: it connects angles, lengths, and projections, and underlies cosine similarity in ML.
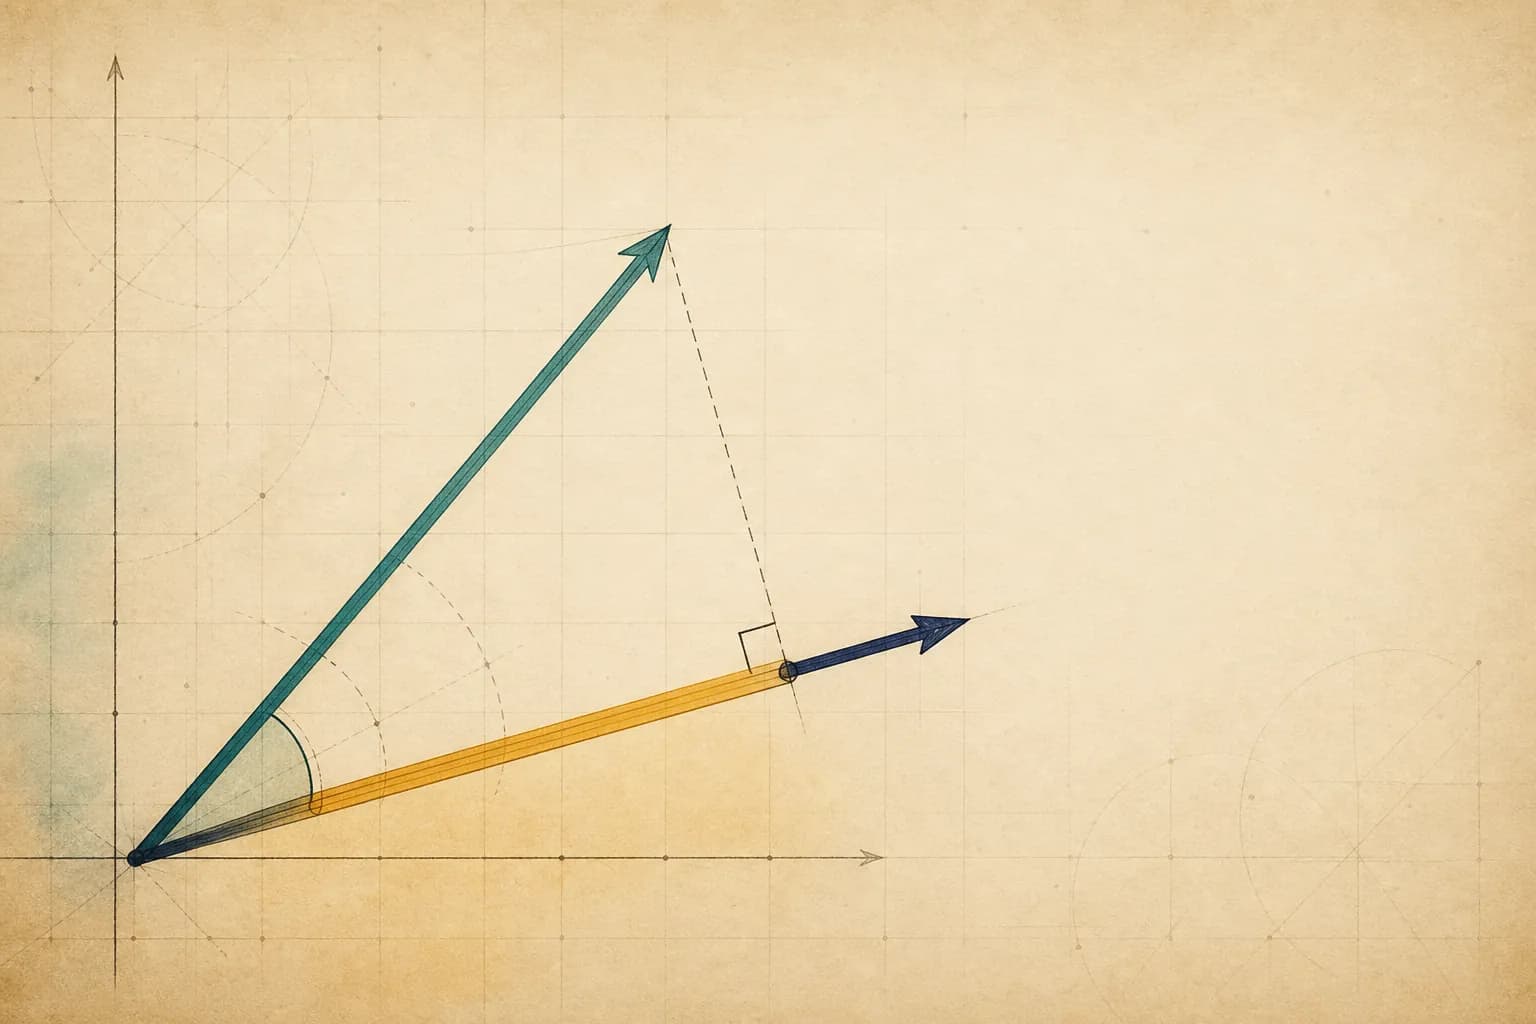
Choose what you expect to see in this section of Dot Product.
Looking at the picture
The dot product measures alignment: it connects angles, lengths, and projections, and underlies cosine similarity in ML.
Pick the part of the picture you expect to explain Dot Product.
Sources
Grounds inner products, vector geometry, and the linear algebra notation reused across attention and optimization.
Wellesley-Cambridge Press. Chapter 1 introduces the dot product, vector length and the angle formula cos θ = u·v / (‖u‖ ‖v‖).
Claims and sources
The checks were made by this site, not by an independent reviewer.
MML introduces inner products as algebraic operations with induced norms, angles, orthogonality, and projections; the page's formulas and demo show those relationships in 2D and connect normalized dot produc...
Applies to finite-dimensional real vectors with v != 0, and to angle/cosine only when both vectors are nonzero. Dot-product magnitude still includes vector lengths; cosine normalizes direction only. Excludes...
MML supports the claim: it defines the R^n dot product as x^T y=sum_i x_i y_i, uses inner products to define norms, angles and orthogonality, defines cos omega=<x,y>/(||x|| ||y||), and derives projection onto span(b) as (<x,b>/<b,b>)b. With the dot product this is proj_v(u)=(u dot v)/(v dot v)v, which the page's equations, code and demo compute.
Practice · Dot Product
The dot product measures alignment: it connects angles, lengths, and projections, and underlies cosine similarity in ML.
Concept · Selected for practice
What it rests on: Sources: Mathematics for Machine Learning; Introduction to Linear Algebra (6th ed.)
Linear Algebra
For Dot Product: What is the smallest example of Dot Product you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
u = np.array([2.0, 1.0])Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Dot Product you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 2 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/linear-algebra/dot-product
concept:linear-algebra/dot-product