Why it is cited
Trains continuous normalizing flows by regressing a velocity field on targets conditioned on a data point, and proves this has the same gradients as regressing on the marginal field (Theorem 2; ICLR 2023).
Flow matching trains a velocity field by regression: on the straight path x_t = (1-t)x0 + t x1 the label is x1 - x0, and the learned field is the average label E[x1 - x0 | x_t].
The idea in plain words, before the symbols.
Flow matching trains a time-dependent velocity field that moves points from a noise distribution toward a data distribution. We begin with a straight path between one noise point and one data point, separating its velocity label from the remaining displacement. The derivation shows that where many paths pass through the same point at the same time, least squares learns the average of their labels; a separate one-dimensional calculation checks which error more sampling steps reduce. This notebook uses least squares and ordinary differential equations.
Imagine starting with a cloud of noise points and wanting to morph it into a cloud shaped like your data. If you knew a time-dependent velocity field that pushes particles, you could integrate the ODE from to and watch noise turn into samples.
The first idea to get right is the supervised label. For one chosen noise/data pair, a straight conditional path uses the current point but trains on the constant velocity . The arrow from to is only the remaining displacement, not the training target.
The second idea is what the network learns from many pairs. Paths from different pairs pass through the same point at the same time, and the network sees only the point and the time, not the pair. Least squares therefore learns the average of their labels there.
The third idea is sampling. A trained field is only half of generation: a sample comes from following that field from a fresh noise point with a numerical solver, and the solver never sees a pair. The investigation after the demo, which error do more sampling steps reduce?, uses a different coupling in one dimension, where every quantity has a closed form. It keeps apart four things that are easy to merge: one pair's training label, the field that averages many such labels, a deliberate error in the field being followed, and the numerical error of the solver's steps. More steps act only on the last.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
We model a trajectory with a neural velocity field , then train that field to match a target velocity :
Here is drawn uniformly from , from the noise distribution and from the data. Regressing on these per-pair (conditional) targets has the same gradients as regressing on the marginal field described below, which cannot be computed directly. Lipman et al. (2023) prove this for paths conditioned on the data point , and Tong et al. (2024) for paths conditioned on a pair , as here.
Choose a straight interpolation between noise and data . Differentiating the path gives the supervised velocity label:
The remaining displacement is shorter than the training label except at .
So the useful identity is:
For a single straight conditional pair, the velocity label stays fixed as changes; the remaining integration time shrinks.
At each point and time, the squared loss is minimized by the conditional mean of the label:
Liu et al. (2023) call the ODE driven by the rectified flow. It carries the noise distribution onto the data distribution, but its paths are generally not straight: where straight pair-paths cross, averages their directions, and the ODE paths bend instead of crossing. Their reflow step retrains on (noise, sample) pairs produced by the previous flow, which straightens the paths and allows fewer integration steps.
Which pairs are used also matters. With independent pairs, each drawn without regard to , the learned flow moves noise to data but is not in general the optimal-transport map between the two distributions. The "optimal transport" path in Lipman et al. (2023) refers to each conditional straight path, not to an optimal pairing of the distributions. Tong et al. (2024) pair noise and data within each minibatch by solving a small optimal-transport problem (OT-CFM); this gives straighter flows that are cheaper to integrate, and it approximates dynamic optimal transport when the true optimal pairing is available.
The equations above hold for any pairing of with . The first Python example below fixes one: the one-dimensional affine pairing , for which . For each that map is invertible in , since , so a state and time determine the pair and its label, . The demo instead pairs synthetic two-dimensional Gaussian noise points with two-moons data points. Now take a one-dimensional coupling that is neither: draw the endpoints independently, and , where 4 is the target variance and 2 its standard deviation. Keep the straight interpolation for and the paired label . Many pairs now pass through the same point at the same time, each with its own label. Neither earlier example is wrong; each uses a different coupling.
Here is a variance, with minimum at ; the standard deviation is , with minimum . Because is jointly Gaussian with mean zero, conditioning on gives the marginal field and the spread of the labels compatible with that point:
using . Take the pair . At its state is 2, its label 2, its remaining displacement 1, and . At its state is 1.4 and its label is still 2, but , with label variance 5. The field is the mean over pairs through that point, not over all pairs. The mean is exact; the spread is variation among compatible labels, not uncertainty about the mean.
Following the field, , has the exact solution , because . So and have the same law at every time: the one-dimensional case of the marginal-preserving flow of Liu, Gong and Liu (2023, §3.1, Theorem 3.3). They are different paths with different couplings. The flow pairs , whereas training drew independently of , so the flow's destination is not the training partner of its start: a drawn pair has with probability zero. For the flow moves toward zero until and away from it afterwards; it is not affine in time, although every training path is.
At two conditionings differ. Given , the state has variance , and the pair-conditional field is undefined at ; it is not evaluated or clamped there. The label is still defined, and conditioning on gives with label variance 1. The marginal field is regular on all of , and one endpoint has no weight in the uniform-time integrals below. Lipman et al.'s Gaussian conditional paths keep a positive endpoint width (their Eqs. 20–23), so this zero-width endpoint rests on the calculation here, not on their construction.
A trained model supplies some field. Here the field is chosen instead: for a fixed , a stipulated error rather than the result of training. Its exact trajectory from is , which ends at . Explicit Euler with uniform steps, and , evaluates the field at its own numerical state:
The reference endpoint is , the exact flow of the true field . The endpoint discrepancy splits into signed parts:
With and the field is exact and only numerical error remains: ends at 1.659138 and at 1.822732, against 2. With the supplied field's exact endpoint is 2.442806, a field-induced error of +0.442806. The numerical errors are −0.443552 at and −0.234936 at , so the totals are −0.000746 and +0.207870. Refinement reduced the numerical error, as it should, and in doing so removed error that had been cancelling the field's. Signed errors add; absolute distances do not, since . None of this makes eight steps better in general. With both errors are negative and nothing cancels.
A separate counterexample: with and , the single step is for every seed. Every training path is straight, yet one Euler step of the marginal field collapses every sample to zero. Straight conditional paths do not by themselves make one-step sampling accurate.
The field is linear in , so for a number and the sampler's output law is . Its exact 2-Wasserstein distance to the target is , including when reflects every seed. That is a population distance for this Gaussian family. It is not the error of one seed, and it is not an image-quality measure.
Use the unhalved squared loss with uniform on . Conditioned on one state and time, the expected loss of the supplied field against the paired labels is
Only after averaging over does become . With and :
These are exact population values for this family; they match the equal-gradient statement of Lipman et al.'s Theorem 2. Their printed proof assumes bounded fields, which a linear field is not, so the equality here rests on the explicit calculation, in which every second moment is finite. The floor is the spread of labels compatible with a state, not measurement noise, numerical error or an unavoidable endpoint error. Individual sample gradients need not agree: for the pair (1, 3) at , the CFM sample derivative at is , while the FM sample derivative and both population derivatives are zero. Neither loss depends on . Neither is an average along a generated trajectory or over one seed.
The floor belongs to the coupling. The dependent coupling has the same endpoint marginals but , field and zero label variance, so its CFM floor is 0 and its intermediate law differs. It is also distinct from this page's first Python example, . Endpoint data alone do not determine one field, and raw CFM losses under different couplings do not rank model quality.
Source statements. Lipman et al. (2023; arXiv:2210.02747v2): Eq. 8 aggregates conditional fields into a marginal field, Eq. 9 defines the CFM objective, and Theorem 2 states that the FM and CFM losses differ by a parameter-independent constant and have equal gradients. In §6.2 and Figure 7 they measure the per-pixel mean squared error of ImageNet-32 solutions at up to 100 function evaluations against 1,000-evaluation solutions over 256 seeds, using the midpoint method for that numerical error, and they report FID separately. Liu, Gong and Liu (2023; arXiv:2209.03003v1): §2.1, Eq. 1 regresses along interpolated pairs and allows an independent coupling. §3.1, Definitions 3.1–3.2 and Theorem 3.3 define the expected-velocity field and its marginal-preserving flow. §5 uses Euler and adaptive RK45, Table 1 counts function evaluations as network calls, and Figure 8 varies the number of Euler steps against image metrics.
Derivations here. The Gaussian field, label variance, exact flows, Euler values, loss identities and Wasserstein distance above are this page's own calculations for one chosen family; neither paper reports these numbers. Nothing here reproduces either paper's sampler, image quality, speed or memory measurements, and nothing here trains a model or performs reflow.
Judgment. For a trained model the true field and flow are unknown. Freezing the field, seeds and numerical precision, then comparing a refinement or an independently implemented solver, measures the numerical sensitivity of integrating that field. Lipman et al.'s 1,000-evaluation comparison is of this kind, and a high-evaluation reference is itself numerical, not ground truth. A separately specified criterion on target data, such as FID for images or the exact distance above, evaluates the output distribution, where field and solver errors combine. Neither comparison alone identifies every error. Held-out CFM risk differences between two fields cancel the unknown floor in expectation only under the same coupling, path and time law; finite-sample uncertainty remains, and a smaller field risk need not give better samples.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
import numpy as np

rng = np.random.default_rng(0)
x0 = rng.standard_normal(5)

# A simple deterministic "data" mapping for the toy example
x1 = 2.0 * x0 + 1.0

for t in [0.0, 0.25, 0.5, 0.75, 1.0]:
    xt = (1 - t) * x0 + t * x1
    u = x1 - x0
    remaining = x1 - xt

    # For this toy mapping, the exact velocity field can be written as v(xt,t):
    # xt = (1+t)x0 + t  =>  x0 = (xt - t)/(1+t)  =>  u = x0 + 1 = (xt + 1)/(1+t)
    v = (xt + 1.0) / (1.0 + t)
    print(
        "t=", t,
        "max|u-v|=", float(np.max(np.abs(u - v))),
        "remaining/full=", round(float(np.linalg.norm(remaining) / np.linalg.norm(u)), 2),
    )
In this toy, each is a function of its , so the point identifies its pair and the field equals the per-pair label exactly: max|u-v| is zero up to rounding. With independent pairs it would be an average instead, and remaining/full would still fall as .
A second code block implements the independent-coupling example from the Math section: the field , the label variance, the perturbed field , its exact flow, explicit Euler and the signed endpoint decomposition. The helper that draws the investigation below computes the same values in TypeScript. Each function checks its inputs (a time in , a finite state, , a seed in and an integer ) and raises an error rather than return a number outside them or after an overflow. Numbers are converted to binary64 Python floats before any arithmetic, as JavaScript numbers are, so NumPy's fixed-width integers cannot wrap; q, u, label_var and v also accept a NumPy array of real numbers, copied to float64, so that the quadrature can run on an array of times. The loss identity is checked by deterministic quadrature against to a stated tolerance, never by sampling. The block needs NumPy 2.0 or later, for np.trapezoid.
import numbers
import numpy as np

# A second coupling: independent endpoints X0 ~ N(0, 1) and X1 ~ N(0, 4).
# 4 is the target variance; its standard deviation is 2. X_t = (1 - t) X0 + t X1, label U = X1 - X0.

INF = float("inf")            # a state only needs to be finite

def check(value, lo, hi, name, integer=False, vector=False):
    # Returns the value the arithmetic will use. A real number (Python int or float, NumPy integer or
    # floating scalar) becomes a binary64 Python float before its bounds are checked, so fixed-width
    # integers never enter the arithmetic; an integer above 2**53 rounds as a JavaScript number would.
    # A step count (integer=True) becomes a Python int. With vector=True a NumPy integer or floating
    # array is also accepted: it is copied to float64 (the caller's array is untouched) and every
    # element is checked, so the quadrature below can pass an array of times.
    if vector and isinstance(value, np.ndarray):
        if value.dtype.kind not in "iuf":
            raise TypeError(f"{name} must be an array of real numbers")
        if value.size == 0:
            raise ValueError(f"{name} is an empty array")
        value = value.astype(np.float64)
        if not (np.isfinite(value).all() and ((lo <= value) & (value <= hi)).all()):
            raise ValueError(f"{name} has an element that is not finite or is outside [{lo}, {hi}]")
        return value
    kind = numbers.Integral if integer else numbers.Real
    if isinstance(value, (bool, np.bool_)) or not isinstance(value, kind):
        raise TypeError(f"{name} must be {'an integer' if integer else 'a real number'}")
    if integer:
        if not lo <= value <= hi:
            raise ValueError(f"{name} = {value} is outside the supported interval [{lo}, {hi}]")
        return int(value)
    try:
        number = float(value)
    except OverflowError:     # a Python int beyond the binary64 range
        number = INF
    if not (np.isfinite(number) and lo <= number <= hi):
        raise ValueError(f"{name} = {value} is not finite or is outside the supported interval [{lo}, {hi}]")
    return number

def finite(value, name):      # a result that overflowed is refused, never returned
    if not np.isfinite(value).all():
        raise FloatingPointError(f"non-finite {name}")
    return value

def q(t):                     # Var(X_t): a variance, not a standard deviation
    t = check(t, 0, 1, "t", vector=True)
    return (1 - t) * (1 - t) + 4 * t * t

def u(x, t):                  # E[U | X_t = x]: the marginal field, by Gaussian conditioning
    x = check(x, -INF, INF, "x", vector=True)
    t = check(t, 0, 1, "t", vector=True)
    return finite((5 * t - 1) * x / q(t), "u(x, t)")

def label_var(t):             # Var(U | X_t = x) = 5 - (5t - 1)^2 / q(t) = 4 / q(t)
    return 4 / q(t)

def pair_velocity(x, x1, t):  # given X1 = x1: (x1 - x) / (1 - t), defined only for t < 1
    x = check(x, -INF, INF, "x")
    x1 = check(x1, -INF, INF, "x1")
    t = check(t, 0, 1, "t")
    if t == 1:
        raise ValueError("undefined at t = 1, where X_t given X1 is a point mass")
    return finite((x1 - x) / (1 - t), "pair velocity")

def v(x, t, eps):             # a chosen perturbation of u, not a trained field
    x = check(x, -INF, INF, "x", vector=True)
    eps = check(eps, -0.25, 0.25, "eps")
    return finite(u(x, t) + eps * x, "v(x, t)")

def exact(x0, t, eps=0.0):    # the exact trajectory of v from x0; eps = 0 is the reference s(t) x0
    x0 = check(x0, -3, 3, "x0")
    t = check(t, 0, 1, "t")
    eps = check(eps, -0.25, 0.25, "eps")
    return np.exp(eps * t) * np.sqrt(q(t)) * x0

def euler(x0, eps, n):        # n uniform explicit left-endpoint steps: h = 1/n, t_k = k/n
    x0 = check(x0, -3, 3, "x0")
    eps = check(eps, -0.25, 0.25, "eps")
    n = check(n, 1, 128, "n", integer=True)
    h, z = 1 / n, x0
    for k in range(n):
        z = z + h * v(z, k / n, eps)          # the field is evaluated at the numerical state z_k
        if not np.isfinite(z):
            raise FloatingPointError(f"non-finite Euler state after step {k}")
    return z

print("pair (1, 3): t, x_t, label U, remaining, u(x_t, t), Var(U | X_t = x_t)")
for t in (0.2, 0.5):
    xt = (1 - t) * 1 + t * 3
    print(t, f"{xt:.6f}", 3 - 1, f"{3 - xt:.6f}", f"{u(xt, t):.6f}", f"{label_var(t):.6f}")
assert u(3.0, 1.0) == 3.0 and label_var(1.0) == 1.0   # at t = 1: u(x, 1) = x with label variance 1

print("seed 1: eps, N, Euler, exact supplied, numerical, field-induced, total")
for eps in (0.0, 0.2, -0.2):
    for n in (8, 16):
        z, supplied, reference = euler(1.0, eps, n), exact(1.0, 1.0, eps), exact(1.0, 1.0)
        numerical, field, total = z - supplied, supplied - reference, z - reference
        assert abs(numerical + field - total) < 1e-12   # signed errors add; absolute distances need not
        print(eps, n, f"{z:.6f} {supplied:.6f} {numerical:+.6f} {field:+.6f} {total:+.6f}")

seeds = np.array([-3.0, -1.0, 0.5, 2.0, 3.0])     # the sampler is linear: z_N = m_N x0 for every seed
assert all(euler(s, 0.0, 1) == 0.0 for s in seeds)  # one step of the true field collapses every seed to 0
m8 = euler(1.0, 0.0, 8)
assert np.allclose([euler(s, 0.0, 8) for s in seeds], m8 * seeds, rtol=1e-14, atol=0)
print("W2 from N(0, m_N^2) to N(0, 4) at eps = 0:", "N=1", abs(abs(euler(1.0, 0.0, 1)) - 2), "N=8", f"{abs(abs(m8) - 2):.6f}")

t = np.linspace(0.0, 1.0, 100_001)                # deterministic quadrature, an approximation; no sampling
for eps in (0.0, 0.2, -0.2):
    k = (5 * t - 1) / q(t) + eps                  # v is the linear field k x
    raw = (k * (1 - t) + 1) ** 2 + 4 * (k * t - 1) ** 2   # E[(k X_t - U)^2] by independence of X0, X1
    assert np.allclose(raw, eps**2 * q(t) + label_var(t), rtol=0, atol=1e-12)
    cfm, fm = np.trapezoid(raw, t), np.trapezoid(eps**2 * q(t), t)
    assert abs(cfm - (np.pi + 5 * eps**2 / 3)) < 1e-8 and abs(fm - 5 * eps**2 / 3) < 1e-8
    print(f"eps={eps:+.1f}: CFM ~ {cfm:.8f} vs pi + 5eps^2/3 = {np.pi + 5 * eps**2 / 3:.8f}; FM ~ {fm:.8f}")
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Flow Matching & Rectified Flows, then open its guide.
Use the demo to predict the conditional velocity label for one paired example, or reveal it directly; a prediction is optional. The pairings are synthetic and chosen to show the label; they are not an optimal-transport assignment. The aggregate field sketch shows how labels from many pairs combine into one field.
After the demo, a separate investigation follows the independent-coupling field from the Math section. Its first view sets one pair's label beside the field value at the same point and the flow from a seed; its second follows a deliberately perturbed field with explicit Euler and splits the endpoint error into signed numerical and field-induced parts. Every result is shown at once, in tables as well as figures. Its controls change only the investigation: the observation guide below still records the demo's state only.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
For noise N(0, 1) and data N(2, 1), compare one pair's label with the field the network learns at the same point, then move to a later time and predict again.
What is the smallest example of Flow Matching & Rectified Flows you can work through by hand, and what does it show?
concept:generative-models/flow-matchingAfter the first pass
Section by section
Flow matching trains a velocity field by regression: on the straight path x_t = (1-t)x0 + t x1 the label is x1 - x0, and the learned field is the average label E[x1 - x0 | x_t].
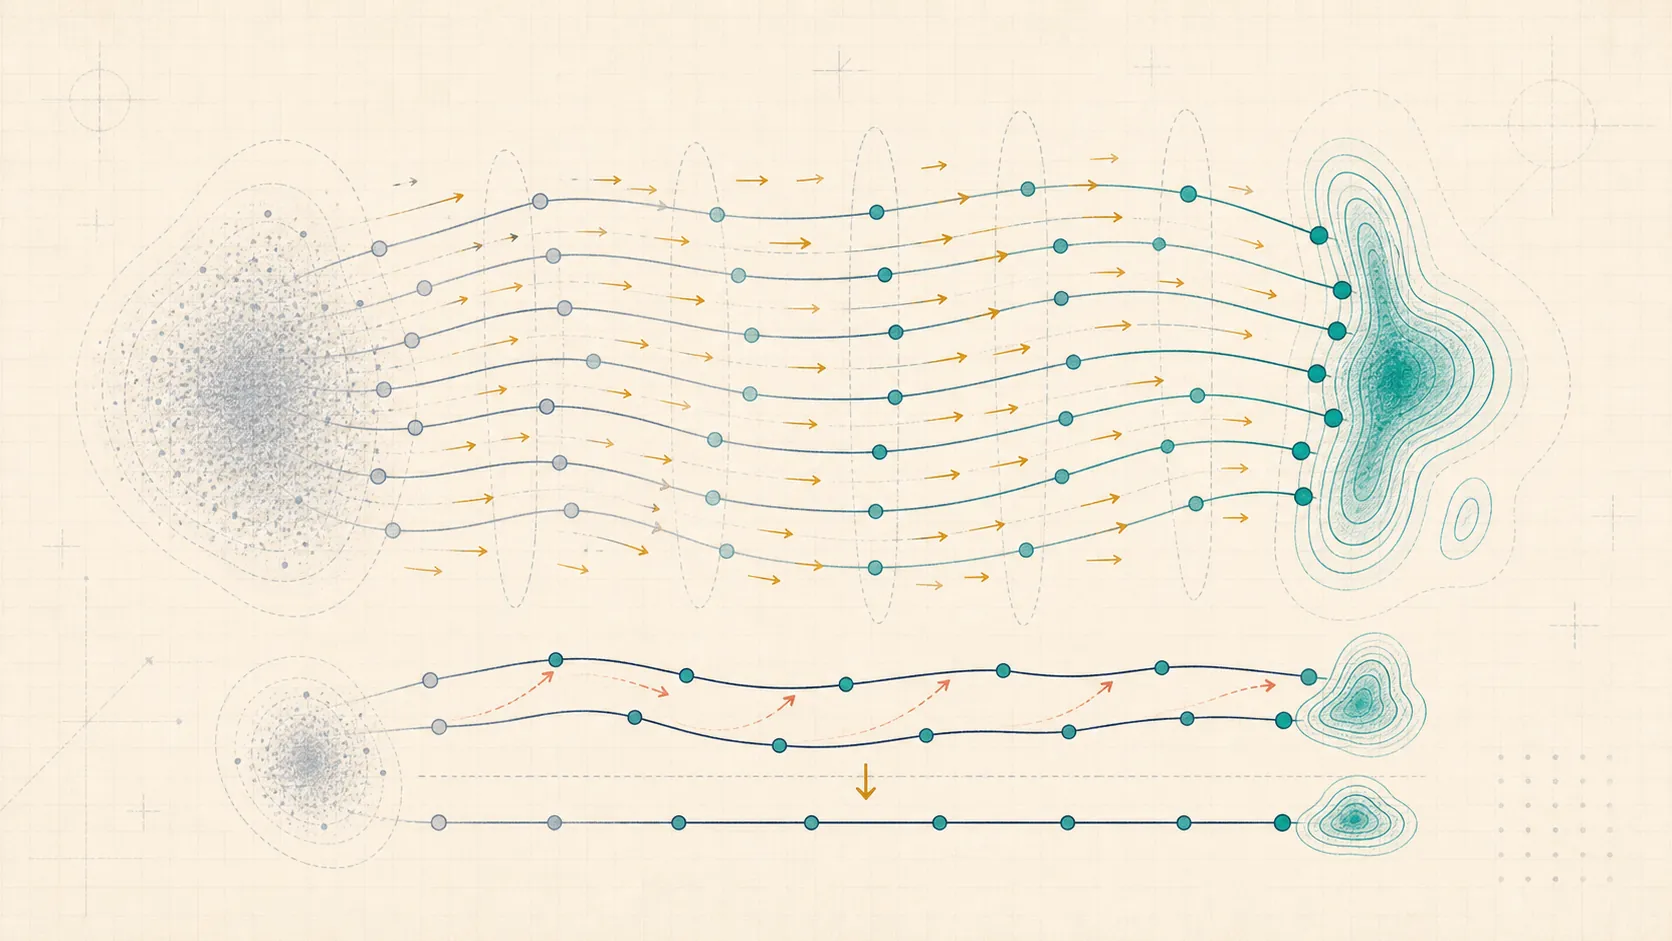
Choose what you expect to see in this section of Flow Matching & Rectified Flows.
Looking at the picture
Flow matching trains a velocity field by regression: on the straight path x_t = (1-t)x0 + t x1 the label is x1 - x0, and the learned field is the average label E[x1 - x0 | x_t].
Pick the part of the picture you expect to explain Flow Matching & Rectified Flows.
Sources
Trains continuous normalizing flows by regressing a velocity field on targets conditioned on a data point, and proves this has the same gradients as regressing on the marginal field (Theorem 2; ICLR 2023).
Defines rectified flow with the straight interpolation X_t = tX_1 + (1-t)X_0 and least-squares target X_1 - X_0, and straightens the learned paths by repeated rectification (ICLR 2023).
Extends the gradient equivalence to targets conditioned on a noise-data pair, and pairs noise and data by minibatch optimal transport (OT-CFM) for simpler flows that are faster to integrate (TMLR 2024).
A tutorial-length review of flow matching: probability paths, conditional and marginal velocity fields, couplings, and a reference implementation (arXiv).
Claims and sources
The checks were made by this site, not by an independent reviewer.
Lipman et al. define flow matching as squared-error regression of a neural ODE velocity field on a target field, with a conditional version that regresses on per-pair targets. Liu et al. define rectified flo...
The code and demo show only the per-pair straight-path label. A trained v_theta(x,t) averages labels over all pairs through x at time t. Nothing here tests optimal-transport optimality, solver error, one-ste...
Lipman et al. support continuous normalizing flows given by ODE vector fields, and flow matching and conditional flow matching as squared-error regression onto a target or conditional vector field. Liu et al. support the rectified-flow straight path X_t=tX_1+(1-t)X_0 and the least-squares target X_1-X_0. The page's equations, code and demo compare that constant label with the remaining displacement X_1-X_t=(1-t)(X_1-X_0); no claim about optimal transport or performance was checked.
Lipman et al. (arXiv:2210.02747v2): Eqs. 8–9, Theorem 2, Eqs. 20–23 (positive endpoint width), §6.2 and Figure 7 (mean squared error against 1,000-evaluation midpoint solutions over 256 seeds; FID reported s...
A worked one-dimensional calculation with a chosen field: no trained model, reflow, solver recommendation, image-quality or speed result, or paper reproduction. Lipman et al. prove the loss equality for boun...
Checked against the two cited papers, in the versions the sources list: Lipman et al. Eqs. 8–9, Theorem 2 (its proof assumes bounded fields), Eqs. 20–23, §6.2 and Figure 7; Liu, Gong and Liu Eq. 1, Definitions 3.1–3.2 and Theorem 3.3, whose conditions this field meets, §5, Table 1 and Figure 8. The field, the label variance (5q − (5t − 1)² = 4), the exact flow and the Euler and loss values were recomputed separately; for ε in [−0.25, 0.25], more steps shrank the numerical part at every N from 1 to 128.
Practice · Flow Matching & Rectified Flows
Flow matching trains a velocity field by regression: on the straight path x_t = (1-t)x0 + t x1 the label is x1 - x0, and the learned field is the average label E[x1 - x0 | x_t].
Concept · Selected for practice
What it rests on: Sources: Flow Matching for Generative Modeling; Flow Straight and Fast: Learning to Generate and Transfer Data with Rectified Flow; Improving and g...
Generative Models
For Flow Matching & Rectified Flows: What is the smallest example of Flow Matching & Rectified Flows you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
assert u(3.0, 1.0) == 3.0 and label_var(1.0) == 1.0 # at t = 1: u(x, 1) = x with label variance 1Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Flow Matching & Rectified Flows you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 4 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/generative-models/flow-matching
concept:generative-models/flow-matching