Why it is cited
Introduces diffusion probabilistic models: a fixed process that gradually adds noise, paired with a learned reverse process (ICML 2015).
How diffusion models generate: a fixed forward process adds Gaussian noise, a network learns to predict that noise, and a sampler runs the process in reverse.
The idea in plain words, before the symbols.
Diffusion models generate by starting from noise and removing it a little at a time.
The forward process is fixed and involves no learning: take a data vector, such as an image, and add a little Gaussian noise, again and again, until it is almost pure Gaussian noise.
The reverse process is what the network learns. Given a noisy sample and its noise level, the network predicts the noise that was added; equivalently, it predicts the clean sample or the score, since the three are related by the formulas below. Sampling starts from pure noise and applies many small denoising steps.
Sohl-Dickstein et al. (2015) introduced this framing. Ho et al. (2020) made it competitive for image generation with the simple noise-prediction loss below.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
A common discrete-time forward process (DDPM-style) is:
where and for a noise schedule .
Equivalently, you can sample:
Ho et al. (2020) train with the noise-prediction loss, with drawn uniformly from :
This is a reweighted form of the variational bound on the log-likelihood; in their experiments, dropping the weights gave better samples.
The score view connects denoising to the gradient of the log-density, (Song and Ermon, 2019; Song et al., 2021). Under the Gaussian corruption above, the score of is , so a trained noise predictor gives a score estimate:
The score matching page derives why regressing on the noise recovers this score.
The network sees only and , never the clean point or the noise that produced them, and many pairs lead to the same . At a given the squared loss is therefore minimized by the average of their noise labels, weighted by how likely each clean point is given , and that average gives the score of the noisy data distribution :
The second equation is Tweedie's formula written for noise prediction; the score matching page gives it in terms of the clean point, with its source. It concerns the marginal , not the Gaussian of one clean point, whose score, , is set by a single label. The best prediction is usually none of the labels it averages; the practice after the demo works this out for a distribution with two clean values.
Ho et al. (2020, Algorithm 2) start from and, for , step
with (one of two variances they found to work about equally well) and at the last step. This needs one network evaluation per step, and in their experiments.
Flow matching trains a velocity field instead of a noise predictor. Lipman et al. (2023) show that the diffusion noising paths are one family among the probability paths it can use.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
import numpy as np

T = 1000
beta = np.linspace(1e-4, 0.02, T)
alpha = 1.0 - beta
alpha_bar = np.concatenate([[1.0], np.cumprod(alpha)])  # alpha_bar[0]=1 (no noise)

x0 = np.array([1.0, -1.0])
for t in [0, 10, 100, 500, 1000]:
    eps = np.random.randn(*x0.shape)
    xt = np.sqrt(alpha_bar[t]) * x0 + np.sqrt(1.0 - alpha_bar[t]) * eps
    print(f"t={t:>3}  xt={np.round(xt, 3)}  noise_std={np.sqrt(1.0 - alpha_bar[t]):.3f}")
The schedule is DDPM's linear one, from to over steps. By the noise standard deviation is already about , so most of the original signal is gone well before the last step.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Diffusion, Score-Based Models & Flow Matching, then open its guide.
The demo shows only the forward process. Scrub to watch
push a two-blob toy distribution toward a near-Gaussian noise cloud. Before checking, predict whether a fixed structure-match measure crosses its threshold early, in the middle, or late. It does not train a network or run a sampler; score matching and flow matching have their own pages.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
One noisy value could have come from either of two clean values. Find the two noise labels, the output that minimizes squared error, and the score; then change the noise level.
What is the smallest example of Diffusion, Score-Based Models & Flow Matching you can work through by hand, and what does it show?
concept:generative-models/diffusionAfter the first pass
Section by section
How diffusion models generate: a fixed forward process adds Gaussian noise, a network learns to predict that noise, and a sampler runs the process in reverse.
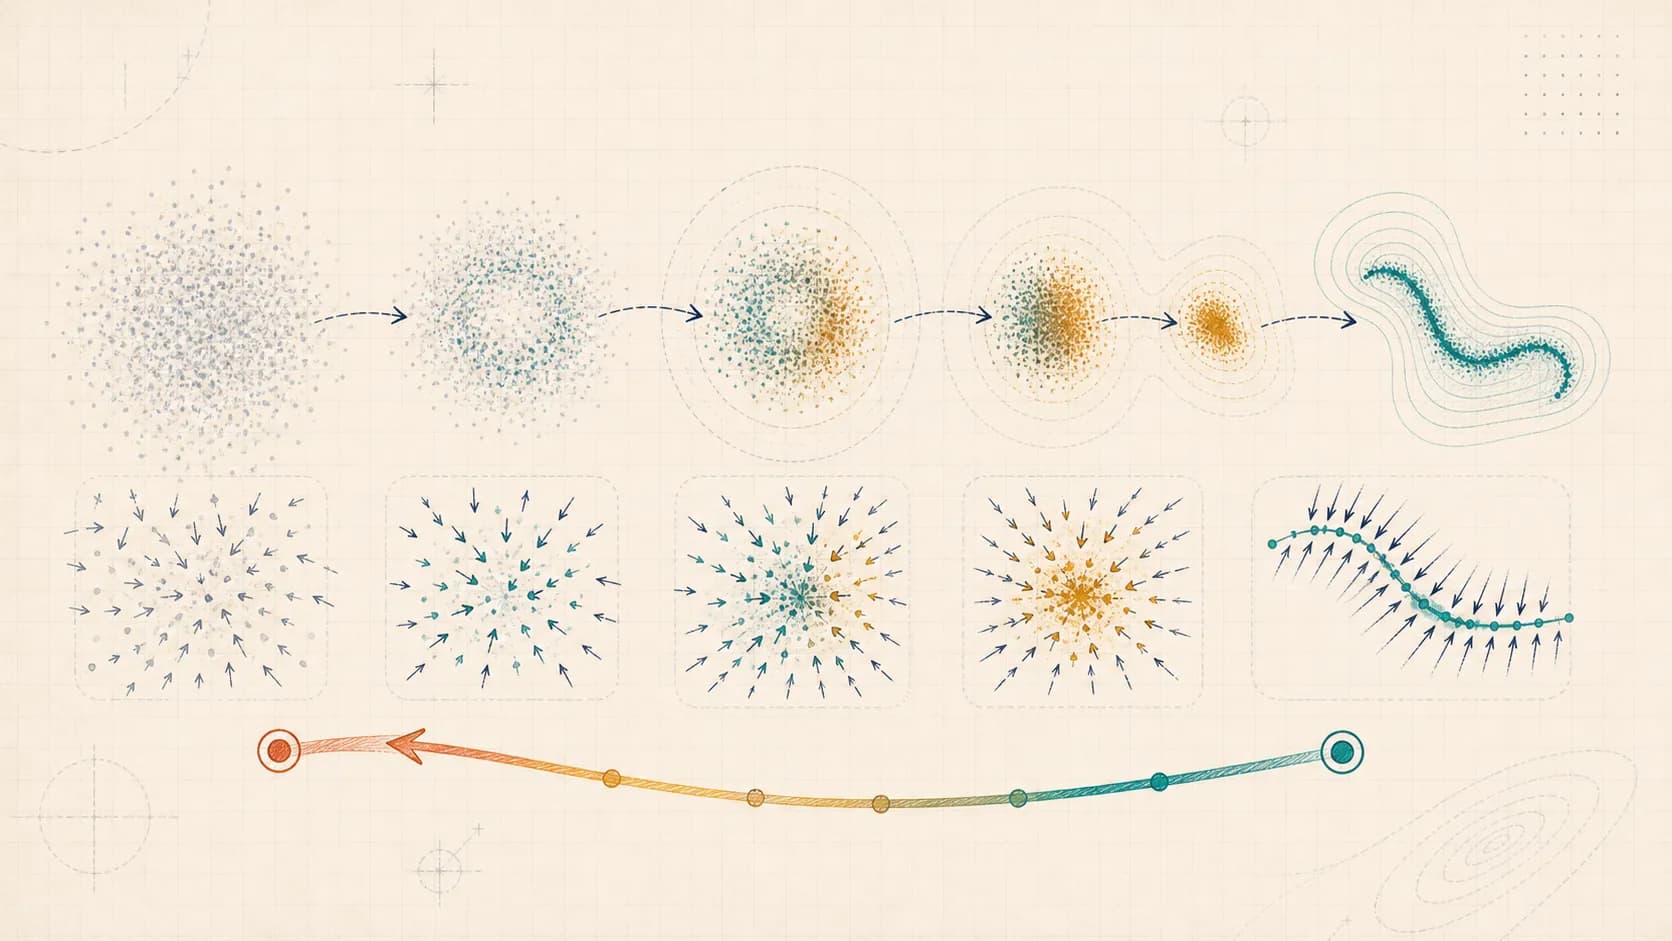
Choose what you expect to see in this section of Diffusion, Score-Based Models & Flow Matching.
Looking at the picture
How diffusion models generate: a fixed forward process adds Gaussian noise, a network learns to predict that noise, and a sampler runs the process in reverse.
Pick the part of the picture you expect to explain Diffusion, Score-Based Models & Flow Matching.
Sources
Introduces diffusion probabilistic models: a fixed process that gradually adds noise, paired with a learned reverse process (ICML 2015).
Gives the closed-form forward process q(x_t|x_0), the simplified noise-prediction loss and the ancestral sampler (Algorithm 2) used on this page (NeurIPS 2020).
Learns the score of the data distribution at many noise levels with denoising score matching and samples with annealed Langevin dynamics (NeurIPS 2019).
Treats noising as a stochastic differential equation and samples with its time reversal or with the probability-flow ODE, both driven by a learned score (ICLR 2021).
Keeps the DDPM training objective but samples with a deterministic, non-Markovian update that can skip steps, reported 10 to 50 times faster (ICLR 2021).
Trains one network with and without the conditioning and mixes the two predictions at sampling time to trade diversity for fidelity (NeurIPS 2021 Workshop on Deep Generative Models and Downstream Applications).
Runs diffusion in the latent space of a pretrained autoencoder to reduce the cost of high-resolution synthesis (CVPR 2022).
Springer. Chapter 20 is a textbook treatment of diffusion models, from the forward noising process to the learned reverse process and guided generation.
Claims and sources
The checks were made by this site, not by an independent reviewer.
Sohl-Dickstein et al. introduce iterative forward corruption with a learned reverse process. Ho et al. give the closed-form q(x_t|x_0), the reparameterized sample x_t and the simplified noise-prediction loss...
The code and demo compute forward noising only; no network is trained and no sampler is run. Sampling, guidance and latent diffusion are summarized from their sources, and nothing here measures image quality.
Sohl-Dickstein supports iterative forward corruption plus learned reversal; Ho supports DDPM q(x_t|x_0), reparameterized x_t, and L_simple epsilon-MSE; Song et al. support reverse-time SDE sampling from time-dependent scores. The equations, code and demo on this page show only forward noising; the epsilon-MSE loss and score-SDE sampling rest on the sources and are not simulated here.
Practice · Diffusion, Score-Based Models & Flow Matching
How diffusion models generate: a fixed forward process adds Gaussian noise, a network learns to predict that noise, and a sampler runs the process in reverse.
Concept · Selected for practice
What it rests on: Sources: Deep Unsupervised Learning using Nonequilibrium Thermodynamics; Denoising Diffusion Probabilistic Models; Generative Modeling by Estimatin...
Generative Models
For Diffusion, Score-Based Models & Flow Matching: What is the smallest example of Diffusion, Score-Based Models & Flow Matching you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
T = 1000Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Diffusion, Score-Based Models & Flow Matching you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 8 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/generative-models/diffusion
concept:generative-models/diffusion