Why it is cited
Introduces score matching for models whose normalizing constant is intractable, with an objective that needs only the model's score and its derivatives (Journal of Machine Learning Research, 2005).
Learn the score, the gradient of log p(x), without the normalizing constant. Denoising score matching turns this into regression on the added noise, which is how diffusion models are trained.
The idea in plain words, before the symbols.
If a probability distribution is a landscape, then is a height map, and the score
is the vector field that points "uphill" toward higher density.
Score-based generative modeling is the idea: instead of learning directly (which requires a normalizing constant), learn the gradient of the log-density. Song and Ermon (2019) learned the score at many noise levels and sampled with Langevin dynamics, moving from coarse to fine noise; Song et al. (2021) cast the same idea as reversing a stochastic differential equation. Either way, estimated scores move points from noise toward data-like samples.
In Gaussian-noising diffusion parameterizations, predicting noise at each noise level is often equivalent, up to a known scale, to estimating a score.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
For a non-normalized model , the data-gradient score ignores the constant :
Hyvärinen (2005) showed that this objective, which needs only the model's score and its derivatives, has the same minimizer as matching the unknown data score. It avoids the normalizing constant, but the trace term needs every diagonal entry of the Jacobian of , which costs about one backward pass per input dimension for a neural network.
Add Gaussian noise. The conditional target, noise-prediction scale, and reverse-time dynamics share the same learned score field:
Denoising score matching trains:
So predicting noise is equivalent (up to scaling) to predicting the score:
In the reverse-time equations, the forward noising process is , is a Brownian motion run backwards in time, and is negative when integrating from down to (Song et al., 2021). The first is a stochastic sampler; the second, the probability-flow ODE, is deterministic and has the same marginal distributions at every .
The conditional DSM target is the label for one known clean source; the marginal score field averages over possible clean sources. Regression closes that gap. At each the DSM loss is minimized by the average label, and that average is exactly the marginal score:
This is Tweedie's formula (Efron, 2011). It is why training on noisy copies of known clean points (Vincent, 2011) recovers the score of the noisy data distribution, and why an optimal denoiser, which outputs , determines the score.
Take data , where is the variance, and the unnormalized model with . Its normalizing constant drops out of the score, , while the data score is . Index both objectives by the variance:
is half the Fisher divergence and needs the unknown data score; is the objective above, which needs only the model. Expanding the square in leaves one term with , and integration by parts removes it: , provided as , as it does here (Hyvärinen, 2005). What is left over is a constant that depends on the data but not on :
Both objectives are minimized at , where the model matches the data. There but : the implicit objective can be negative, and its value is not a distance. The two share a minimizer, not their values.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
import numpy as np

rng = np.random.default_rng(0)
x = rng.normal(loc=1.5, scale=1.0, size=(5,))
sigma = 0.7
eps = rng.standard_normal(x.shape)
xt = x + sigma * eps

score_from_eps = -eps / sigma
score_from_xt = -(xt - x) / (sigma**2)  # same quantity

print("x:  ", np.round(x, 3))
print("xt: ", np.round(xt, 3))
print("max|diff|:", float(np.max(np.abs(score_from_eps - score_from_xt))))
The second block checks the one-dimensional identity by quadrature, for two data variances and three models: is every time, and is negative at the minimizer .
import numpy as np

def objectives(v, theta, n=200_001):
    # Expectations over X ~ N(0, v) by quadrature on a wide grid
    x = np.linspace(-12 * np.sqrt(v), 12 * np.sqrt(v), n)
    p = np.exp(-x**2 / (2 * v)) / np.sqrt(2 * np.pi * v)
    s_model, s_data = -theta * x, -x / v
    J = np.trapezoid(0.5 * (s_model - s_data) ** 2 * p, x)   # needs the data score
    L = np.trapezoid((0.5 * s_model**2 - theta) * p, x)      # the model alone: d/dx s_model = -theta
    return J, L

for v in (0.5, 3.0):
    for theta in (0.2, 1 / v, 1.5):
        J, L = objectives(v, theta)
        print(f"v={v}, theta={theta:.3f}: J={J:.6f}  L={L:+.6f}  J-L={J - L:.6f}  1/(2v)={1 / (2 * v):.6f}")
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Score Matching & Score-Based Generative Models, then open its guide.
Use the demo to see the score field and how diffusion's noise prediction corresponds to a scaled score estimate.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
For Gaussian data and a one-parameter model, compute the explicit and implicit score-matching objectives and see that they share a minimizer but not their values. Then change the data variance.
What is the smallest example of Score Matching & Score-Based Generative Models you can work through by hand, and what does it show?
concept:generative-models/score-matchingAfter the first pass
Section by section
Learn the score, the gradient of log p(x), without the normalizing constant. Denoising score matching turns this into regression on the added noise, which is how diffusion models are trained.
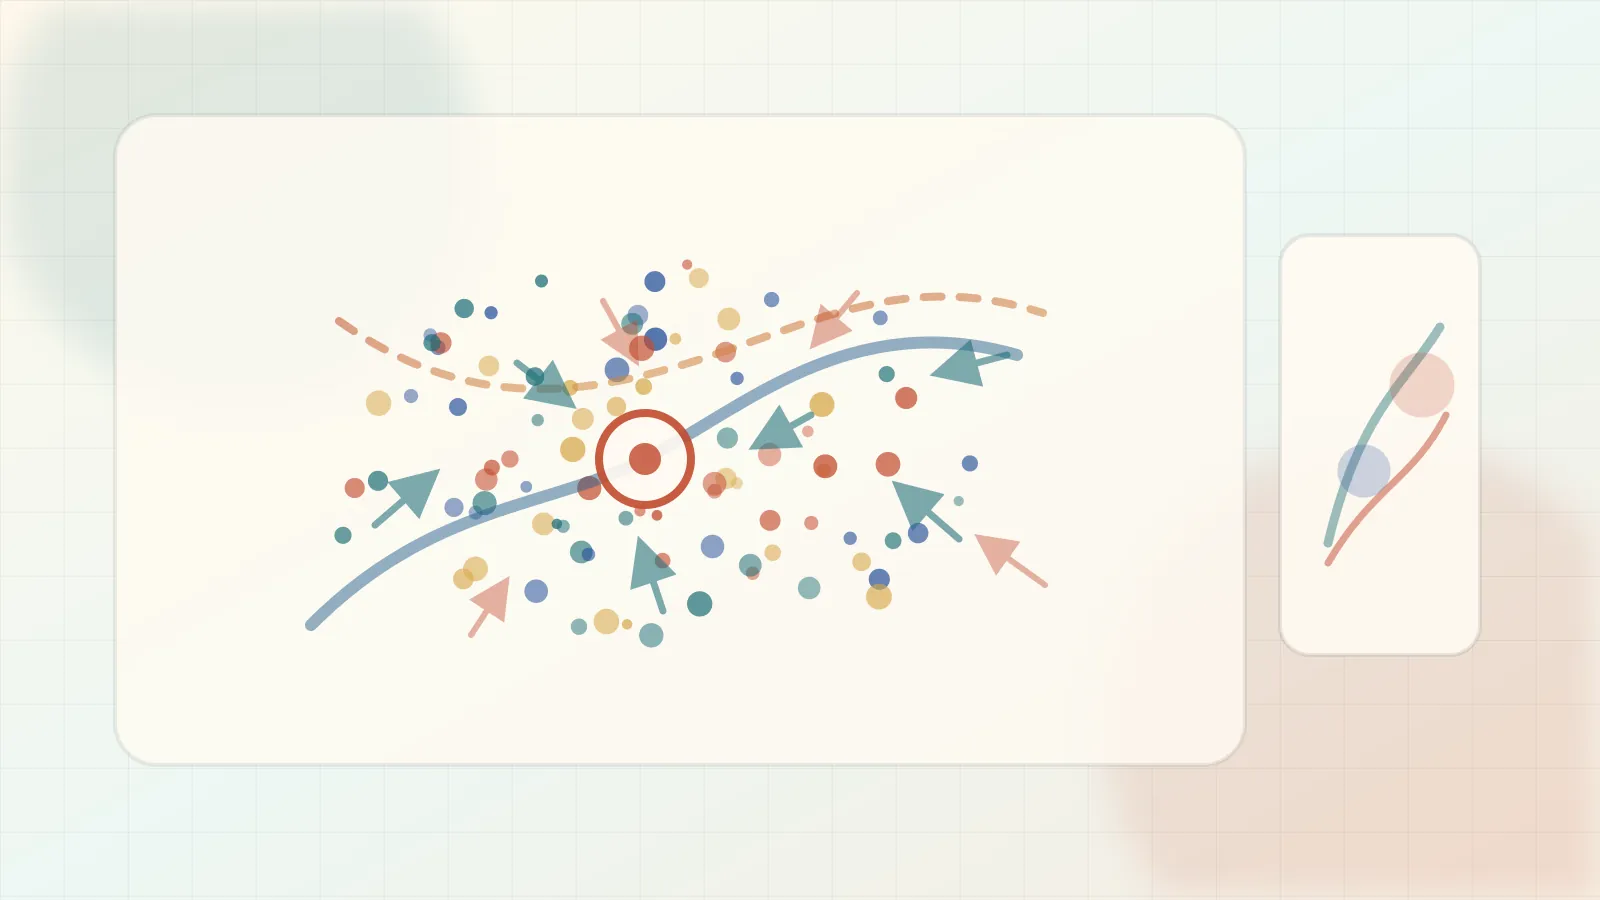
Choose what you expect to see in this section of Score Matching & Score-Based Generative Models.
Looking at the picture
Learn the score, the gradient of log p(x), without the normalizing constant. Denoising score matching turns this into regression on the added noise, which is how diffusion models are trained.
Pick the part of the picture you expect to explain Score Matching & Score-Based Generative Models.
Sources
Introduces score matching for models whose normalizing constant is intractable, with an objective that needs only the model's score and its derivatives (Journal of Machine Learning Research, 2005).
Shows that regressing on the score of a Gaussian corruption of known clean points (denoising score matching) is equivalent to score matching on the noisy data distribution (Neural Computation, 2011; DOI 10.1162/NECO_a_00142).
Learns the data score at many noise levels with denoising score matching and samples with annealed Langevin dynamics (NeurIPS 2019).
Connects learned time-dependent scores to the reverse-time SDE and the probability-flow ODE used for sampling (ICLR 2021).
States Tweedie's formula: for Gaussian noise, the posterior mean of the clean value equals the observation plus the noise variance times the score of the observed density (Journal of the American Statistical Association, 2011).
Claims and sources
The checks were made by this site, not by an independent reviewer.
Hyvärinen supports score matching for continuous non-normalized models because the data score removes Z(theta). Vincent supports the Gaussian DSM target (x-x_tilde)/sigma^2 and its equivalence to score match...
A conditional DSM label is not the marginal score; only its average over clean sources is. The page does not run a solver, train a high-dimensional model or measure sample quality, and it does not cover full...
Hyvärinen supports score matching for non-normalized models: the score, a data gradient, does not involve Z(theta), and the implicit objective uses squared-score and divergence terms. Vincent supports the Gaussian conditional denoising target (x-x_tilde)/sigma^2 = -epsilon/sigma and its equivalence to score matching. Song et al. support estimated time-dependent scores in reverse-SDE sampling and probability-flow ODEs. The page's equations, code and demo follow these steps; the target appears only after you predict.
Practice · Score Matching & Score-Based Generative Models
Learn the score, the gradient of log p(x), without the normalizing constant. Denoising score matching turns this into regression on the added noise, which is how diffusion models are trained.
Concept · Selected for practice
What it rests on: Sources: Estimation of Non-Normalized Statistical Models by Score Matching; A Connection Between Score Matching and Denoising Autoencoders; Generat...
Generative Models
For Score Matching & Score-Based Generative Models: What is the smallest example of Score Matching & Score-Based Generative Models you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
rng = np.random.default_rng(0)Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Score Matching & Score-Based Generative Models you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 5 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/generative-models/score-matching
concept:generative-models/score-matching