Why it is cited
Proposes the double-descent risk curve, which extends the classical U-shape past the interpolation threshold, and shows it for random-feature models, decision trees and neural networks (PNAS 116(32), 2019).
Test error can peak at the interpolation threshold, where a model first fits its training data exactly, and fall again as the model grows past it.
The idea in plain words, before the symbols.
The classical picture says that test error is U-shaped in model capacity: too little capacity underfits, too much overfits. Yet very large networks, which can fit their training data exactly, often generalize well. Belkin et al. (2019) proposed the double-descent curve to reconcile the two, and Nakkiran et al. (2020) observed it in deep networks as model size, training time or the amount of data changes:
The key idea is that in the overparameterized regime there are many solutions that fit the training data perfectly. Optimization and model choice can impose an implicit bias toward particular interpolating solutions. In some settings, especially linear or random-feature models, this bias is connected to low-norm or smoother solutions that can generalize well (Hastie et al., 2022).
Grokking is often discussed as a related training-time generalization pattern, but it is a separate phenomenon and is not needed to define double descent.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
In a linear regression view, let be features and targets.
Gradient descent on the squared loss, started from , never leaves the row space of , so with a sufficiently small positive step size and full row rank it converges to the minimum-norm interpolant:
For the random Gaussian designs considered below, near the smallest singular value of is typically close to zero, so the fitted weights need a very large norm and amplify the noise in ; that is the peak. For much larger than there are many interpolants, and the minimum-norm one can have a small norm again. Hastie et al. (2022) derive the limiting test-error curve, as and grow in proportion, for linear and random-feature models.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
import numpy as np

n_train, n_test, max_d = 80, 2000, 300
noise = 0.2
dims = [10, 30, 60, 80, 100, 150, 300]

def fit_linear(X, y):
    n, d = X.shape
    if d < n:
        return np.linalg.lstsq(X, y, rcond=None)[0]
    return X.T @ np.linalg.solve(X @ X.T + 1e-8 * np.eye(n), y)

def trial(seed, d):
    rs = np.random.RandomState(seed)
    w_true = rs.randn(max_d) / np.sqrt(max_d)
    Xtr_full = rs.randn(n_train, max_d)
    Xte_full = rs.randn(n_test, max_d)
    ytr = Xtr_full @ w_true + noise * rs.randn(n_train)
    yte = Xte_full @ w_true + noise * rs.randn(n_test)

    Xtr, Xte = Xtr_full[:, :d], Xte_full[:, :d]
    w_hat = fit_linear(Xtr, ytr)
    train_mse = float(np.mean((Xtr @ w_hat - ytr) ** 2))
    test_mse = float(np.mean((Xte @ w_hat - yte) ** 2))
    return train_mse, test_mse

curve = []
for d in dims:
    runs = np.array([trial(seed, d) for seed in range(20)])
    train_mse, test_mse = runs.mean(axis=0)
    curve.append((d, train_mse, test_mse))
    print("d =", f"{d:>3}", "train_mse =", round(train_mse, 3), "test_mse =", round(test_mse, 3))

by_d = {d: (train, test) for d, train, test in curve}
assert by_d[80][0] < 1e-6
assert by_d[80][1] > by_d[60][1] and by_d[80][1] > by_d[100][1]
assert by_d[300][1] < by_d[80][1]
This is a fixed synthetic linear task, not a theorem about every large model. It makes the interpolation threshold visible: training error reaches zero near , test error spikes there, and a larger minimum-norm interpolant can recover lower test error.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Overparameterization & Generalization (Double Descent), then open its guide.
Use the demo to see error curves against capacity, and compare double descent with grokking, a separate pattern in which validation accuracy rises long after training accuracy has reached 100% (Power et al., 2022).
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
What is the smallest example of Overparameterization & Generalization you can work through by hand, and what does it show?
concept:scaling/double-descentAfter the first pass
Section by section
Test error can peak at the interpolation threshold, where a model first fits its training data exactly, and fall again as the model grows past it.
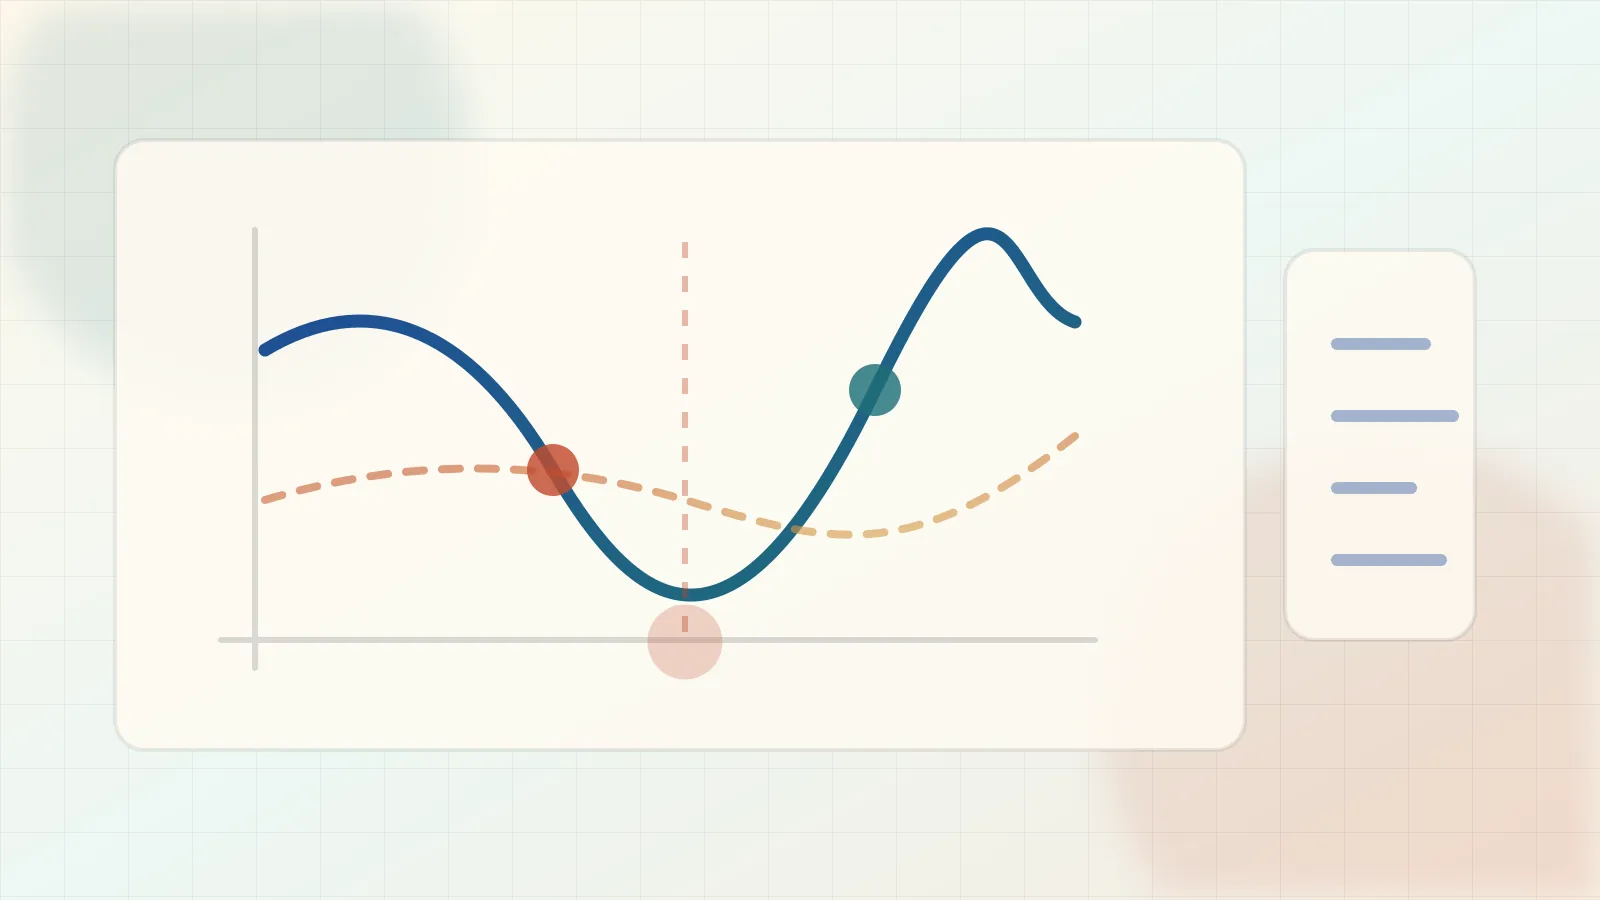
Choose what you expect to see in this section of Overparameterization & Generalization (Double Descent).
Looking at the picture
Test error can peak at the interpolation threshold, where a model first fits its training data exactly, and fall again as the model grows past it.
Pick the part of the picture you expect to explain Overparameterization & Generalization (Double Descent).
Sources
Proposes the double-descent risk curve, which extends the classical U-shape past the interpolation threshold, and shows it for random-feature models, decision trees and neural networks (PNAS 116(32), 2019).
Reports model-wise, epoch-wise and sample-wise double descent in deep networks, including regimes where more training data hurts (ICLR 2020).
Derives the test error of minimum-norm least-squares interpolation as the number of features and samples grow together, reproducing double descent for linear and random-feature models (Annals of Statistics 50(2), 2022).
Reports networks on small algorithmic datasets that generalize perfectly long after they have overfit the training set (arXiv preprint).
Claims and sources
The checks were made by this site, not by an independent reviewer.
Belkin et al. frame double descent as an empirical risk curve extending the classical U-shape beyond interpolation: near-threshold predictors can have high risk while more capacity beyond interpolation can l...
Double descent is empirical and conditional: it is not guaranteed for every model, dataset, optimizer, training length, regularization or noise level. The synthetic code example shows the shape, not evidence...
Belkin supports the interpolation-threshold pattern: risk can peak near interpolation and fall again past it. Nakkiran supports model-wise, epoch-wise, and sample-count/non-monotonic deep double descent. The synthetic demo and the minimum-norm equations and code are illustrations, not part of the checked claim.
Practice · Overparameterization & Generalization (Double Descent)
Test error can peak at the interpolation threshold, where a model first fits its training data exactly, and fall again as the model grows past it.
Concept · Selected for practice
What it rests on: Sources: Reconciling modern machine-learning practice and the classical bias–variance trade-off; Deep Double Descent: Where Bigger Models and More...
Scaling
For Overparameterization & Generalization (Double Descent): What is the smallest example of Overparameterization & Generalization you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
assert by_d[80][0] < 1e-6Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Overparameterization & Generalization you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 4 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/scaling/double-descent
concept:scaling/double-descent