Why it is cited
Fits language-model test loss as power laws in parameters, data and compute; §2.1 derives the C ≈ 6ND training-compute estimate, and §6.1 the allocation N ∝ C^0.73 (arXiv preprint).
Empirical power laws for how pretraining loss falls with parameters, data and compute, how to split a fixed budget between model size and tokens, and why some abilities seem to appear suddenly.
The idea in plain words, before the symbols.
If you train a family of models the same way (same architecture class, data pipeline and optimizer recipe), a bigger model and more data usually give a predictably lower test loss. Kaplan et al. (2020) found that the loss of language models falls as a power law in parameters, data and compute over several orders of magnitude.
Scaling laws turn that regularity into a planning tool. You fit a curve to small runs, forecast how far a larger run will go, and decide how to spend a fixed compute budget:
A scaling law is an empirical fit, not a theorem. It describes one training recipe on one data distribution, and its fitted exponents can change when either changes. Its main use is deciding how to spend compute.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
A common empirical form for test loss is:
where:
On a log–log plot each term, such as , is a straight line with slope . That is why power laws are convenient to fit and to extrapolate, although nothing guarantees that the fit holds far beyond the range of the runs it came from.
Training a dense transformer costs about six floating-point operations per parameter per token, two for the forward pass and four for the backward pass (Kaplan et al., 2020, §2.1):
Substitute into the loss and set . The minimum is at
The two exponents add to 1, so a larger budget is split between a larger model and more tokens. When both are about : parameters and tokens grow at the same rate. That is Hoffmann et al.'s (2022) central finding. Their three estimation methods gave , and , against from Kaplan et al. (2020). With the published, rounded coefficients of their third method (, ), (their Table 2 reports for this method) and , so and the number of tokens per parameter rises slowly with the budget.
What goes wrong otherwise. At a fixed budget, a model that is too large for its number of tokens is undertrained: the same compute spent on a smaller model trained on more tokens reaches a lower loss. Hoffmann et al. trained Chinchilla (70 billion parameters, 1.4 trillion tokens) with the same compute as Gopher (280 billion parameters, 300 billion tokens), about FLOPs, and Chinchilla outperformed Gopher on a large range of downstream evaluation tasks.
The fit assumes fresh data. counts tokens seen once. When unique data runs out, repeating it helps less: Muennighoff et al. (2023) found that up to about four epochs of repeated data were nearly as useful as new data, and that the value of further repetition fell towards zero.
Fitted coefficients are fragile. Besiroglu et al. (2024) refitted the third method to data they extracted from Hoffmann et al.'s Figure 4 and obtained , , , , ; they also report that the published coefficients fit the extracted data poorly. Their fit implies about 20 tokens per parameter, in line with Hoffmann et al.'s first two methods. The published coefficients used in the figure below imply about 50 tokens per parameter at FLOPs, and more at larger budgets.
Wei et al. (2022) call an ability emergent if it is absent in smaller models and present in larger ones, and they document many few-shot tasks where accuracy stays near chance and then rises sharply with scale. Schaeffer et al. (2023) argue that many of these jumps come from the metric rather than the model. Exact-match accuracy on a ten-token answer requires all ten tokens to be right, so if token correctness is independent and each token is right with probability , the expected score is . As rises steadily from to and then , exact match goes from to and then . Scored on the same model outputs with a continuous metric, such as token edit distance, many of the reported jumps become smooth. Whether some abilities are emergent in a stronger sense is still debated.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
import numpy as np

# Hoffmann et al. (2022), Approach 3: L(N, D) = E + A / N**alpha + B / D**beta
# (E, A, B are L_inf, a, b in the equation above)
E, A, B = 1.69, 406.4, 410.7
alpha, beta = 0.34, 0.28

def loss(N, D):
    return E + A / N**alpha + B / D**beta

C = 1e21                        # training FLOPs, with C ≈ 6 N D
Ns = np.logspace(7, 12, 2001)   # 10 million to 1 trillion parameters
Ds = C / (6 * Ns)               # tokens left for each model size
i = np.argmin(loss(Ns, Ds))
print(f"grid search: N* = {Ns[i]:.3g}, D* = {Ds[i]:.3g}, D*/N* = {Ds[i] / Ns[i]:.1f}")

# Closed form from dL/dN = 0 along D = C / (6N)
G = (alpha * A / (beta * B)) ** (1 / (alpha + beta))
N_opt = G * (C / 6) ** (beta / (alpha + beta))
D_opt = C / (6 * N_opt)
print(f"closed form: N* = {N_opt:.3g}, D* = {D_opt:.3g}, D*/N* = {D_opt / N_opt:.1f}")
print(f"N* ∝ C^{beta / (alpha + beta):.2f}, D* ∝ C^{alpha / (alpha + beta):.2f}, D* ∝ N*^{alpha / beta:.2f}")
The grid search and the closed form agree: about parameters and tokens at FLOPs, the same numbers the figure below shows at its default budget.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Scaling Laws & Emergent Abilities, then open its guide.
The first demo asks which mechanism explains each view before showing it: the loss-scaling view or the emergence view. The figure below it evaluates Hoffmann et al.'s fitted loss along a fixed compute budget. Move the budget and watch the minimum, the optimal model size and the number of tokens per parameter change.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
What is the smallest example of Scaling Laws & Emergent Abilities you can work through by hand, and what does it show?
concept:scaling/scaling-lawsAfter the first pass
Section by section
Empirical power laws for how pretraining loss falls with parameters, data and compute, how to split a fixed budget between model size and tokens, and why some abilities seem to appear suddenly.
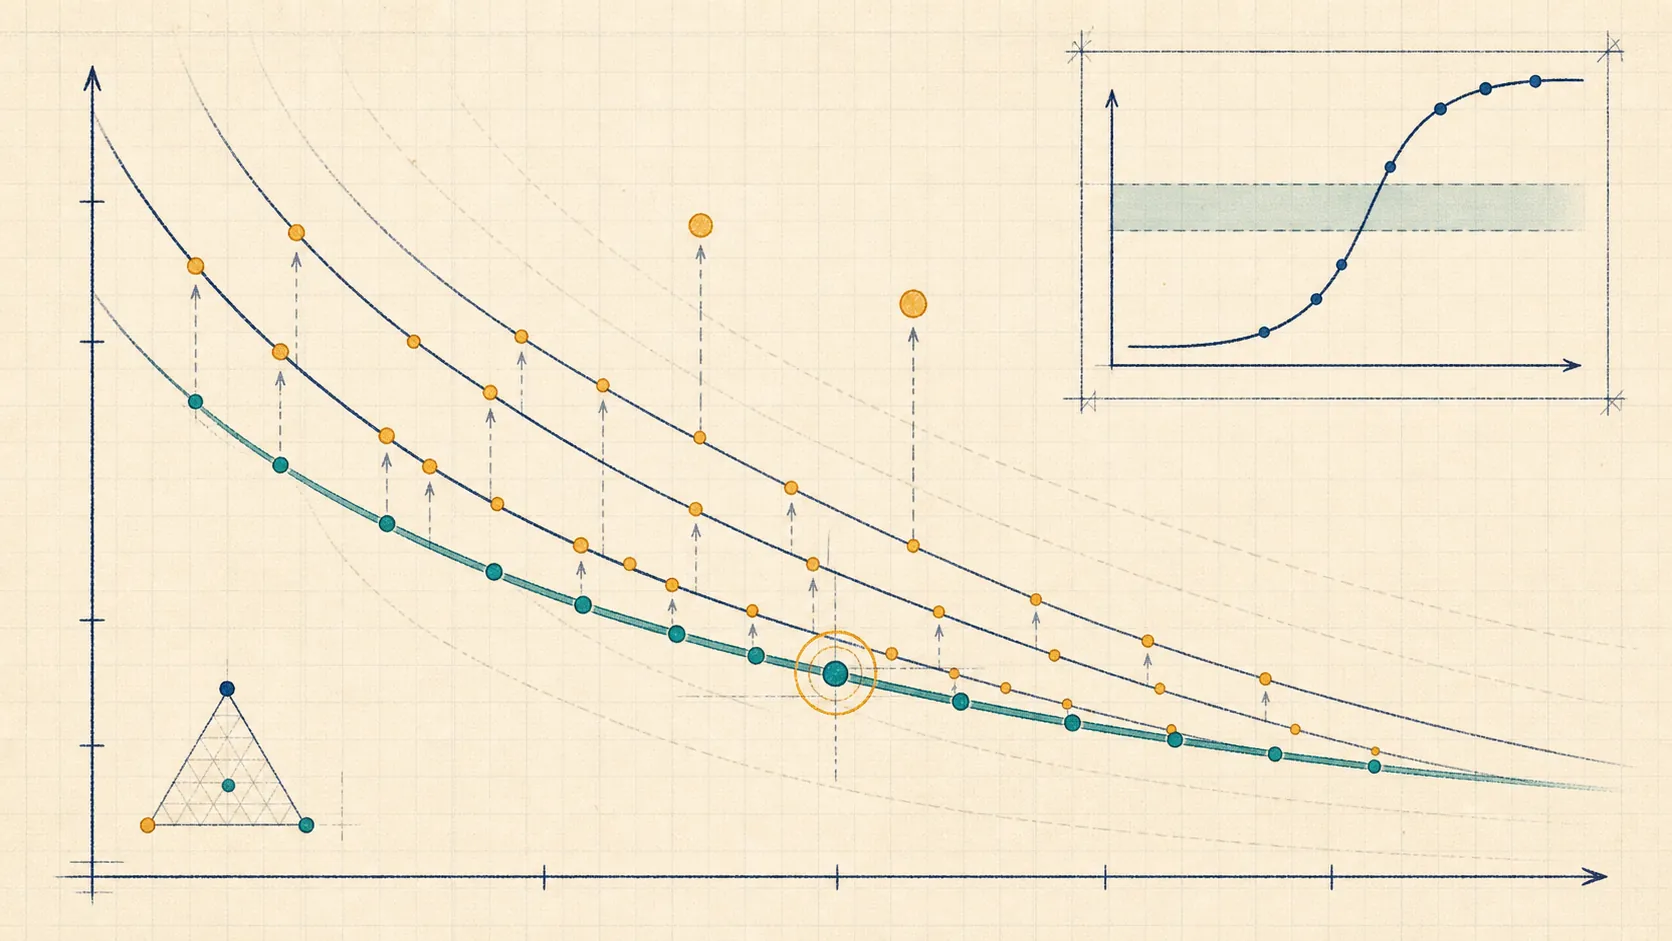
Choose what you expect to see in this section of Scaling Laws & Emergent Abilities.
Looking at the picture
Empirical power laws for how pretraining loss falls with parameters, data and compute, how to split a fixed budget between model size and tokens, and why some abilities seem to appear suddenly.
Pick the part of the picture you expect to explain Scaling Laws & Emergent Abilities.
Sources
Fits language-model test loss as power laws in parameters, data and compute; §2.1 derives the C ≈ 6ND training-compute estimate, and §6.1 the allocation N ∝ C^0.73 (arXiv preprint).
Trains over 400 models and finds that, for a fixed compute budget, parameters and training tokens should grow at about the same rate (Table 2); Appendix D.2 gives the Approach 3 fit used on this page (NeurIPS 2022).
Refits Hoffmann et al.'s Approach 3 to data extracted from their Figure 4; the refit implies about 20 tokens per parameter, consistent with Approaches 1 and 2, whereas the published Approach 3 coefficients imply more (arXiv preprint).
Finds that up to about four epochs of repeated data are nearly as useful as unique data, after which the value of more compute decays towards zero (NeurIPS 2023).
Defines an emergent ability as one absent in smaller models and present in larger ones, and surveys few-shot tasks whose accuracy rises sharply with scale (Transactions on Machine Learning Research, 2022).
Argues that many reported emergent abilities follow from nonlinear or discontinuous metrics, and that continuous metrics on the same outputs show smooth improvement (NeurIPS 2023).
Claims and sources
The checks were made by this site, not by an independent reviewer.
Kaplan et al. study language-model cross-entropy loss and report power-law scaling with model size, dataset size, and training compute. Hoffmann et al. train over 400 models and find that compute-optimal tra...
These are empirical fits to pretraining loss. They do not show that the exponents are universal across architectures or datasets, and they say nothing directly about inference-time compute, data quality or b...
Checked the arXiv abstracts: Kaplan et al. support power laws for cross-entropy loss in model size, dataset size and training compute; Hoffmann et al. support scaling model size and training tokens equally for compute-optimal training at a fixed budget. The page's equations, code and figure apply only this pretraining-loss view and the split of a fixed budget between parameters N and tokens D.
Practice · Scaling Laws & Emergent Abilities
Empirical power laws for how pretraining loss falls with parameters, data and compute, how to split a fixed budget between model size and tokens, and why some abilities seem to appear suddenly.
Concept · Selected for practice
What it rests on: Sources: Scaling Laws for Neural Language Models; Training Compute-Optimal Large Language Models; Chinchilla Scaling: A replication attempt
Scaling
For Scaling Laws & Emergent Abilities: What is the smallest example of Scaling Laws & Emergent Abilities you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
E, A, B = 1.69, 406.4, 410.7Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Scaling Laws & Emergent Abilities you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 6 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/scaling/scaling-laws
concept:scaling/scaling-laws