Why it is cited
NeurIPS 2017. Fits a reward model to human comparisons of pairs of short behavior clips and trains a policy against the learned reward.
RLHF trains a reward model from pairwise preferences, then reweights a reference policy toward high learned reward while a KL penalty limits distribution shift.
The idea in plain words, before the symbols.
A pretrained or supervised-finetuned language model gives a distribution over completions. In InstructGPT-style RLHF, the reference policy is often the supervised-finetuned model trained from demonstrations. RLHF asks:
When humans prefer one completion over another, how should that preference move probability mass?
The mechanism has two stages.
First, train a reward model from comparisons. It does not learn an absolute moral score; it learns differences that make preferred completions more likely under a pairwise preference model.
Second, optimize a policy against that learned reward while penalizing movement away from a reference model. In the finite-action picture:
RLHF multiplies the reference probability of each completion by an exponential reward bonus, then renormalizes.
High reward pulls probability upward. The KL penalty controls how far the new policy may drift. If the reward model is a proxy with exploitable errors, optimizing too aggressively can move probability mass toward outputs that score well under the proxy but are worse under the real target.
Sources. Christiano et al. (2017), "Deep Reinforcement Learning from Human Preferences", fit a reward model to human comparisons and trained agents against it. Ziegler et al. (2019), "Fine-Tuning Language Models from Human Preferences", and Stiennon et al. (2020), "Learning to summarize from human feedback", applied the method to language models with a KL penalty to the starting model. Ouyang et al. (2022), "Training language models to follow instructions with human feedback", describe the InstructGPT pipeline that much later work follows. Lambert's Reinforcement Learning from Human Feedback (2026) is a book-length treatment.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
The two moving pieces are the preference-trained reward gap and the KL-shaped policy update:
The rest of this section derives both equations.
Let a preference datum be , where is preferred to for prompt . Define the reward gap
A reward model predicts
This is the Bradley-Terry model of paired comparisons (Bradley and Terry, 1952), with as each completion's strength.
The negative log-likelihood is
where
Only reward differences inside the same prompt are observed. Therefore gives the same pairwise probabilities as .
Reward scale also needs a convention. With a fixed logistic noise model, reward gaps are measured in that model's log-odds units. With perfectly separable hard preferences, an unregularized reward model can drive gaps toward infinity. Practical systems therefore normalize, regularize, or otherwise choose a usable reward scale before policy optimization.
For a fixed prompt , reference policy , and candidate policy , define expected reward
and the KL term
The RLHF objective is
Equivalently, if
then
Assume on the candidate support. Optimize over the finite distribution subject to . The Lagrange stationarity condition is
Solving for and normalizing gives
Here
Larger keeps the policy closer to the reference. Smaller lets learned reward dominate.
Rearranging gives the bridge to DPO:
The final term depends only on the prompt, so it cancels in preference differences.
In language-model RLHF, the candidate space is enormous. InstructGPT-style RLHF uses PPO (Schulman et al., 2017), a clipped policy-gradient method, to optimize the learned reward with a KL penalty to the supervised-finetuned or reference model. The clean finite-action formula above is the exact optimum of a finite-action regularized objective. PPO is a stochastic optimizer for the language-model version; it is not this closed-form update, and a parametric policy with a per-token KL penalty need not reach the toy optimum exactly. Later pipelines often skip the reinforcement-learning step and fit the preferences directly, as in Direct Preference Optimization.
PPO also trains a value function to estimate how good each state is. Group-relative policy optimization (GRPO), introduced with DeepSeekMath (Shao et al., 2024), drops that value function. It samples a group of outputs for the same prompt from the policy before the update, scores each one, and weights each output by its reward minus the group's mean reward, divided by the group's standard deviation. It keeps PPO's clipped ratio and adds a KL penalty to a reference model directly to the loss. The group-relative update investigation after the demo works one such step through for a single decision with two actions.
If differs from the real target , then low can concentrate the policy on outputs with high proxy reward and low true utility. KL regularization reduces this pressure but does not make the proxy correct. Gao, Schulman and Hilton (2023) measure the effect for learned reward models; the reward hacking page works through it.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
The code keeps three pieces visible: fitting a reward model to pairwise comparisons, the invariance of the policy to a constant reward shift, and the KL-regularized policy that reweights a reference distribution.
import numpy as np

def sigmoid(z):
    return 1.0 / (1.0 + np.exp(-z))

def softmax(logits):
    logits = logits - logits.max()
    e = np.exp(logits)
    return e / e.sum()

# One prompt, four candidate completions.
# Shape: rewards, pi_ref, pi_star are all (K,).
pairs = np.array([
    [0, 1],
    [0, 2],
    [2, 1],
    [3, 1],
    [0, 3],
])

K = 4
r = np.zeros(K)
lr = 0.3
l2 = 0.05

for _ in range(800):
    grad = l2 * r

    for winner, loser in pairs:
        margin = r[winner] - r[loser]
        p = sigmoid(margin)
        g = p - 1.0
        grad[winner] += g
        grad[loser] -= g

    r -= lr * grad / len(pairs)
    r -= r.mean()  # choose one representative of the shift-equivalence class

pi_ref = np.array([0.35, 0.30, 0.20, 0.15])
beta = 0.7

def kl_regularized_policy(reward):
    logits = np.log(pi_ref) + reward / beta
    return softmax(logits)

pi_star = kl_regularized_policy(r)
pi_shifted = kl_regularized_policy(r + 10.0)

kl = np.sum(pi_star * (np.log(pi_star) - np.log(pi_ref)))

print("learned reward representative:", np.round(r, 3))
print("reference policy:             ", np.round(pi_ref, 3))
print("KL-regularized policy:        ", np.round(pi_star, 3))
print("KL(pi* || pi_ref):            ", round(float(kl), 4))

assert np.allclose(pi_star, pi_shifted)
Adding a constant to every reward changes neither pairwise preference probabilities nor the KL-regularized policy. The policy depends on reward differences and on how strongly anchors it to the reference.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in RLHF: Reward Modeling + KL-Regularized Policy Optimization, then open its guide.
The demo reweights a reference distribution over four completions. Change , toggle a proxy reward gap, and add a reward shift. Watch the reference policy get reweighted, and notice that shifting every reward leaves the policy unchanged.
After the demo, a separate investigation follows one group-relative policy update: four scored choices from a frozen policy, their relative weights, one gradient step, and PPO's clipped objective evaluated on the same records. Its controls change only the investigation.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Investigation · one decision, four scored episodes, one step
A frozen policy chooses A or B four times; each choice is scored and its episode ends. The scores become relative weights, one gradient step moves the logits, and the clipped objective scores the result against the same fixed records. It does not limit how far the step goes.
A worked calculation with chosen numbers, not training. Fixed here: old logits (0, 0), so πold = (½, ½); reward rule R(A) = 1, R(B) = 0; step size η = ½; clip width ε = 0.2; β = 0, so no KL penalty, and no value function, entropy term or optimizer state. The weights follow group-relative policy optimization (GRPO) specialized to one context and one token; the clipped ratio is PPO’s. Nothing here is saved.
e1 chose A
e2 chose A
e3 chose B
e4 chose B
b = (1 + 1 + 0 + 0) / 4 = 0.5, the group’s mean reward.
σ = √(((0.5)² + (0.5)² + (−0.5)² + (−0.5)²) / 4) = 0.5. Dividing by four, the number of records, is a convention chosen here; it does not treat four records as a whole population.
Âi = (Ri − b) / σ. A negative weight means below this group’s mean, not a negative reward.
score ea − πold = ∇z log π(a) at zoldg = ¼ Σ Âi(eai − πold)z1 = zold + ηg, η = 0.5π1 = softmax(z1)
e3 chose B and scored 0, below the group mean 0.5, so its weight is −1. Its score vector at πold is eB − πold = (−0.5, 0.5), the direction that would raise log π(B). Weighted by −1 it becomes (0.5, −0.5): this row pushes toward A.
e1 A+0.5e2 A+0.5e3 B+0.5e4 B+0.5z1 = (0, 0) + 0.5 · (0.5, −0.5) = (0.25, −0.25)
The step moves the logits, and softmax turns (0.25, −0.25) into π1(A) = 0.622459. Adding the same step ηg to the probabilities instead would give (0.75, 0.25), which is not this update. Every row pushes toward A: under this rule A is always above a mixed group’s mean and B below it.
Known expected return J = π(A)·1 + π(B)·0: 0.5 → 0.622459. The four records are not re-scored by the step: their mean is still 0.5.
The old probabilities stay attached to the records they produced; π1 describes future choices. Changing the group restarts this calculation from the same πold.
ρi = π(ai) / πold(ai)L = ¼ Σ min(ρiÂi, clip(ρi, 0.8, 1.2)Âi)
Each ratio compares a policy’s probability of the same recorded action with its fixed old probability. It is not the odds of A against B. L is maximized; the records, weights and denominators do not move.
| Record | ρ | ρ | clip(ρ) | Kept (min) |
|---|---|---|---|---|
e1 AÂ +1 | 1.2449 | 1.2449 | 1.2 | 1.2clipped |
e2 AÂ +1 | 1.2449 | 1.2449 | 1.2 | 1.2clipped |
e3 BÂ −1 | 0.7551 | −0.7551 | −0.8 | −0.8clipped |
e4 BÂ −1 | 0.7551 | −0.7551 | −0.8 | −0.8clipped |
| L | 0.2 |
After the step L = 0.2. The ratios 1.244919 and 0.755081 lie outside [0.8, 1.2], and nothing projected them back: one plain gradient step from πold, where every ratio is 1, never meets the clip. Every term is now on a clipped, flat piece, so for these fixed records the surrogate’s gradient at π1 is (0, 0).
Clipping removes the objective’s incentive to push a recorded action’s ratio further past 1 ± 0.2 in the direction its weight favors. It is not a hard limit on the policy, a bound on KL, or a guarantee about performance or forgetting.
This comparison holds the worked group AABB fixed, whichever group is selected above. For a candidate π = (p, 1 − p) its surrogate is L(p) = min(2p − 1, 0.2). The candidates are supplied for comparison; none is a result of the step, and nothing here continues the optimization.
A rows: ρ = 1.8, clipped; B rows: ρ = 0.2, clipped. L = 0.2, KL(πold ‖ π) = 0.510826 nats, known return J = 0.9.
Every term is clipped, so the surrogate is flat here: it gives no incentive to move further, and none to move back.
| Policy π(A) | L | KL(πold ‖ π) | J |
|---|---|---|---|
| 0.5πold | 0 | 0 | 0.5 |
| 0.622459after one step | 0.2 | 0.03093 | 0.622459 |
| 0.6supplied | 0.2 | 0.020411 | 0.6 |
| 0.9supplied | 0.2 | 0.510826 | 0.9 |
| 0.3unfavorable | −0.4 | 0.087177 | 0.3 |
| 0.1unfavorable | −0.8 | 0.510826 | 0.1 |
Equal surrogate, different policies. π(A) = 0.6 and π(A) = 0.9 both give L = 0.2, yet their KL from πold is 0.020411 and 0.510826 nats and their known returns are 0.6 and 0.9. Past the favored bound the objective is flat, so it cannot tell a small move from a large one. KL is shown as a diagnostic: it is not a term of L here (β = 0), and 0.2 is not a KL bound.
Unfavorable moves stay in. At π(A) = 0.3 the A rows have ρ = 0.6 and the B rows ρ = 1.4: both moves go against their weights, so the minimum keeps the unclipped terms. L = −0.4, not the clipped-only −0.2. At π(A) = 0.1, L = −0.8. L never exceeds the unclipped surrogate: a move that worsens it is counted in full.
In AAAA every record scored 1: b = 1, σ = 0. By the convention used here every weight is 0, L is 0 at every policy and the step leaves π at (½, ½). The old policy is not optimal: ∇zJ at πold is (0.25, −0.25). The group simply carries no relative signal. Under πold, 2 of the 16 orders (probability 0.125) are flat.
A separate example, with a black-box scorer instead of this page’s rule, so nothing determines the missing value: e1 chose A and scored 1, e2 chose A and scored 1, e3 chose B and scored 0, and e4 chose B with no score returned. b and σ need all four scores, so every weight is unknown, including e1’s.
| Repair | b | σ | e1’s weight |
|---|---|---|---|
| Fill e4 with 0 | 0.5 | 0.5 | +1 |
| Fill e4 with 1 | 0.75 | 0.433013 | +0.57735 |
| Drop e4, divide by three | 0.666667 | 0.471405 | +0.707107 |
Each repair is a different invented record with a different update. The calculation is unavailable: report the score as missing and take no step.
This page’s public rule is a different situation. Under it, a stored record with no score has a determined value (0 for B), yet it is still refused as incomplete, so that a corrected record is supplied rather than silently filled in. A B scored 1 contradicts the rule and is refused, not treated as noise.
Where this stops. One step from one old policy on a fully known two-action problem. It does not show what repeated steps, fresh samples, a learned reward model, many tokens per output or a nonzero β would do. Nearby and different: DPO minimizes a loss on recorded preference pairs against a fixed reference policy, with no scores and no old-policy ratio; best-of-N selection picks the highest-scored of several sampled answers at answer time and leaves the policy unchanged.
With π = softmax(z), log π(a) = za − log(ezA + ezB), so ∇z log π(a) = ea − π. For a record’s ratio, ∇zρi = ρi(eai − π), because πold(ai) is a fixed number. At zold every ρi = 1 lies strictly inside the band, so each term is ρiÂi nearby and ∇L = ¼ Σ Âi(eai − πold) = g. L is maximized, so the step adds ηg.
The full reward table is known here, so the true objective is available: J(π) = π(A)·1 + π(B)·0 = π(A), with ∂J/∂zc = π(c)(R(c) − J). At πold the true advantages are R(a) − J = (0.5, −0.5) and ∇J = (0.25, −0.25). The standardized weights of AABB, (+1, +1, −1, −1), are not these advantages. Because the table is known, sampling is unnecessary for solving this toy problem; the four records illustrate an estimator and a surrogate, not a need for reinforcement learning.
PPO usually estimates advantages across time steps with generalized advantage estimation (GAE), which bootstraps from a learned value function; the PPO reference page gives the formula. With one action, no later state and no value function, there is nothing to discount or bootstrap, and these weights come from the group, not from GAE.
| A records k | Orders | gA normalized | centered only | raw R |
|---|---|---|---|---|
| 0 | 1 | 0 | 0 | 0 |
| 1 | 4 | 0.433013 | 0.1875 | 0.125 |
| 2 | 6 | 0.5 | 0.25 | 0.25 |
| 3 | 4 | 0.433013 | 0.1875 | 0.375 |
| 4 | 1 | 0 | 0 | 0.5 |
| Mean over 16 | 0.404006 | 0.1875 | 0.25 |
Every order with the same count gives the same gradient, √(k(4 − k)) / 4 for A. Weighting the rows by their counts 1, 4, 6, 4, 1, the expected normalized gradient is 3/16 + √3/8 = 0.404006, not the true ∇JA = 0.25. Averaging the five menu groups equally would give 0.273205, which weights them wrongly.
Raw rewards with no baseline average exactly to ∇J. Centering alone already gives 0.1875 = ¾ · 0.25: the group mean includes the record’s own reward, so this baseline is not independent of the action and the usual unbiasedness argument for a baseline does not apply. Dividing by a shared σ also makes the four weights depend on one another, although the draws are independent. These are exact finite calculations; a larger expected gradient is not evidence that this estimator learns better or worse.
| In the source | Here |
|---|---|
| PPO (Schulman et al., arXiv 1707.06347v2), §2.1 Eqs. 1–2: the policy-gradient estimator from fixed data | The mean of Âi ∇ log π(ai) over four one-step records at zold |
| PPO §3, Eq. 7 and Fig. 1: the ratio to the old policy and the minimum with its clipped copy | L, with ρ over πold of the same recorded action; ε = 0.2 is a chosen value |
| PPO §5, Algorithm 1: many actors, GAE advantages, several epochs of minibatch updates; Eq. 9 adds value and entropy terms | One step on one group; no value function, entropy term, epochs or GAE |
| DeepSeekMath (Shao et al., arXiv 2402.03300v1), printed p. 13, Eq. 3: the GRPO objective over a group of G outputs and their tokens, with a KL penalty to a reference model | G = 4 one-token outputs for one context; β = 0, so no reference model enters. The old policy that sampled, the group baseline and a reference model are three different things |
| DeepSeekMath p. 14, §4.1.2: outcome rewards normalized by the group mean and standard deviation | The same form. The displayed definition fixes no divisor, epsilon or zero-σ branch; division by four and zero weights for a flat group are choices made here |
| DeepSeekMath p. 14, Algorithm 1: the iterative loop | Not run. Its line 11 points to Eq. 21, which on printed p. 30 is a gradient coefficient rather than the objective; this page cites Eq. 3 for the objective. The note describes the v1 PDF as inspected, not an author correction |
TRL v0.24.0 grpo_trainer.py, lines 1495–1509: group std through .std(dim=1) (PyTorch’s default correction 1, divisor n − 1), then division by std + 1e-4 | Applied to AABB as arithmetic only, those choices give weights ±0.86587543 rather than ±1. Lines 1507–1527 log an is_std_zero fraction rather than selecting a division branch; a constant group gets zero weights from centering, though other configured losses or optimizer state could still change parameters |
| TRL lines 1680–1743: an optional KL term when β ≠ 0, token-level ratios exp(new − old log-probability), a sequence-level option, the negated minimum as a loss and several loss reductions | One token, so token and sequence ratios coincide; L is maximized directly. No TRL code runs here, and no runtime or bit parity, current default or training result is claimed |
Sources: Schulman et al. (2017). Proximal Policy Optimization Algorithms. arXiv:1707.06347v2. Shao et al. (2024). DeepSeekMath: Pushing the Limits of Mathematical Reasoning in Open Language Models. arXiv:2402.03300v1 (PDF). Hugging Face TRL v0.24.0: advantage normalization and loss. PyTorch documentation: torch.std.
A separate implementation of the validation, normalization, step, surrogate, candidates and sixteen orders, with NumPy float64 arrays and the same refusals. The site’s test suite runs this exact text and compares it with the TypeScript helper on every ordered group, every short binary score list, a grid of candidates and each refusal. Results agree to within a few units in the last place, not bit for bit.
import math
import re
from fractions import Fraction
from itertools import product

import numpy as np

# One context, one choice of A or B, then the episode ends: its return is that one reward.
ACTIONS = ("A", "B")
REWARD = {"A": 1, "B": 0}          # the rule chosen for this example, not a learned reward
Z_OLD = np.array([0.0, 0.0])       # frozen old logits, shape (2,), float64
ETA = 0.5                          # one ascent step: this objective is maximized
LOWER, UPPER = 0.8, 1.2            # the ratio band 1 - 0.2 to 1 + 0.2 (clip width 0.2)
ID_PATTERN = re.compile(r"[A-Za-z0-9][A-Za-z0-9._-]{0,31}", re.ASCII)


class GroupUpdateError(ValueError):
    """A coded refusal. Nothing is repaired, zero-filled or dropped."""

    def __init__(self, code, detail):
        super().__init__(f"{code}: {detail}")
        self.code = code


def softmax(z):
    """Internal: two validated float64 logits of shape (2,), in shifted coordinates."""
    e = np.exp(z - z.max())
    return e / e.sum()


PI_OLD = softmax(Z_OLD)            # (0.5, 0.5): the denominator of every ratio, never re-estimated


def is_number(x):
    """A Python int or float (NumPy float64 is a float). A bool, a NumPy int or a string is not a score."""
    return isinstance(x, (int, float)) and not isinstance(x, bool)


def validate_group(records):
    """Four records, checked one at a time: shape, id, duplicate, action, then the reward."""
    if not isinstance(records, list) or len(records) != 4:
        raise GroupUpdateError("malformed-group", "a group is a list of exactly four records")
    seen, valid = set(), []
    for i, record in enumerate(records, start=1):
        if type(record) is not dict or set(record) != {"id", "action", "reward"}:
            raise GroupUpdateError("malformed-record", f"record {i} needs exactly id, action and reward")
        rid, action, reward = record["id"], record["action"], record["reward"]
        if type(rid) is not str or not ID_PATTERN.fullmatch(rid):
            raise GroupUpdateError("invalid-id", f"record {i} needs a string ID such as e1")
        if rid in seen:
            raise GroupUpdateError("duplicate-id", f"record ID {rid} appears twice")
        seen.add(rid)
        if type(action) is not str or action not in ACTIONS:
            raise GroupUpdateError("invalid-action", f"record {rid}: the action must be A or B")
        if reward is None:  # the rule fixes what it would be, but the record must carry it: refuse, never fill
            raise GroupUpdateError("missing-feedback", f"record {rid} has no stored score; under the rule {action} scores {REWARD[action]}, but a corrected record must be supplied")
        if not is_number(reward):
            raise GroupUpdateError("invalid-feedback-type", f"record {rid}: a score must be a number")
        if isinstance(reward, float) and not math.isfinite(reward):
            raise GroupUpdateError("nonfinite-feedback", f"record {rid}: a score must be finite")
        if reward != REWARD[action]:
            raise GroupUpdateError("contradictory-feedback", f"record {rid}: under the rule, {action} scores {REWARD[action]}")
        valid.append((rid, action, float(reward)))
    return valid


def check_scores(scores):
    """For the normalization comparisons only: 2 to 4 scores, each exactly 0 or 1."""
    if not isinstance(scores, list) or not 2 <= len(scores) <= 4:
        raise GroupUpdateError("malformed-scores", "a score list has 2 to 4 entries")
    for i, s in enumerate(scores, start=1):
        if not is_number(s) or s not in (0, 1):
            raise GroupUpdateError("invalid-score", f"score {i} must be exactly 0 or 1")
    return [float(s) for s in scores]


def normalize(scores):
    """Internal. Center on the group mean b, then divide by sigma with divisor n (here, division by four)."""
    R = np.array(scores, dtype=np.float64)                 # shape (n,)
    b = R.sum() / R.size
    sigma = np.sqrt(((R - b) ** 2).sum() / R.size)         # R.std(ddof=0); torch.std's default would divide by n - 1
    if sigma == 0:                                         # (R - b) / sigma is 0 / 0: zero weights by convention
        return b, sigma, np.zeros_like(R)
    return b, sigma, (R - b) / sigma


def sample_std_plus_epsilon(scores):
    """The inspected TRL v0.24.0 arithmetic, for comparison: divisor n - 1, plus 1e-4. Not TRL itself."""
    R = np.array(check_scores(scores), dtype=np.float64)
    c = R - R.sum() / R.size
    return c / (np.sqrt((c ** 2).sum() / (R.size - 1)) + 1e-4)


def branch(rho, w):
    """Internal. For w > 0 the term is w * min(rho, UPPER); for w < 0 it is w * max(rho, LOWER).

    So a weighted term has one kink, at the bound its weight favors, and passes smoothly through the other.
    """
    if w == 0:
        return "no-weight"                                 # zero at every policy, smooth everywhere
    if rho == (UPPER if w > 0 else LOWER):
        return "edge"                                      # the favored bound: a kink, no unique derivative
    if (rho > UPPER) if w > 0 else (rho < LOWER):
        return "clipped"                                   # past the favored bound: constant, no incentive
    if (rho < LOWER) if w > 0 else (rho > UPPER):
        return "unclipped"                                 # past the unfavorable bound: the full rho * w stays
    return "inside"                                        # includes the unfavorable bound itself


def surrogate(recs, w, pi):
    """Internal. L(pi) = mean of min(rho w, clip(rho) w), rho over the OLD probability of the SAME recorded action."""
    idx = np.array([ACTIONS.index(a) for _, a, _ in recs])  # int64, used only to index
    rho = pi[idx] / PI_OLD[idx]                              # (4,)
    clipped = np.clip(rho, LOWER, UPPER)
    terms = np.minimum(rho * w, clipped * w)
    branches = [branch(r, x) for r, x in zip(rho, w)]
    grad = None
    if "edge" not in branches:                               # d rho / dz = rho (e_a - pi) where the term moves
        active = np.array([x in ("inside", "unclipped") for x in branches])
        grad = ((active * w * rho)[:, None] * (np.eye(2)[idx] - pi)).sum(axis=0) / len(recs)
    return {
        "rho": rho, "terms": terms, "branches": branches, "L": terms.sum() / len(recs),
        "clipped_only": (clipped * w).sum() / len(recs), "unclipped": (rho * w).sum() / len(recs), "grad": grad,
        "J": float(pi @ np.array([REWARD[a] for a in ACTIONS], dtype=np.float64)),
        "kl": float((PI_OLD * (np.log(PI_OLD) - np.log(pi))).sum()),
    }


def analyze(records):
    """One group, one step, always from the same old policy."""
    recs = validate_group(records)
    b, sigma, w = normalize([r for _, _, r in recs])
    idx = np.array([ACTIONS.index(a) for _, a, _ in recs])
    scores = np.eye(2)[idx] - PI_OLD                          # grad log pi(a_i) at z_old, shape (4, 2)
    contributions = w[:, None] * scores                      # (4, 2)
    g = contributions.sum(axis=0) / 4                        # (2,): at z_old every rho is 1, inside the band
    z1 = Z_OLD + ETA * g                                     # the logits move; probabilities follow by softmax
    pi1 = softmax(z1)
    return {"recs": recs, "b": b, "sigma": sigma, "w": w, "old_prob": PI_OLD[idx], "scores": scores,
            "contributions": contributions, "g": g, "z1": z1, "pi1": pi1,
            "old": surrogate(recs, w, PI_OLD), "new": surrogate(recs, w, pi1)}


def evaluate_candidate(records, p):
    """The fixed group's L at a supplied pi = (p, 1 - p), 0.05 <= p <= 0.95. A comparison, not a step."""
    recs = validate_group(records)
    if not is_number(p) or not 0.05 <= p <= 0.95:
        raise GroupUpdateError("invalid-candidate", "pi(A) must be a number from 0.05 to 0.95")
    return surrogate(recs, normalize([r for _, _, r in recs])[2], np.array([float(p), 1 - float(p)]))


def group(order):
    return [{"id": f"e{i}", "action": a, "reward": REWARD[a]} for i, a in enumerate(order, start=1)]


def v(x, digits=6):
    return tuple(round(float(t), digits) for t in x)


# 1. The default group AABB: two As scored 1, two Bs scored 0.
AABB = analyze(group("AABB"))
print("b =", AABB["b"], "sigma =", AABB["sigma"], "(divide by 4); weights", v(AABB["w"]))
print("shapes: scores", AABB["scores"].shape, "contributions", AABB["contributions"].shape, AABB["g"].dtype)
print("contributions:", [v(c) for c in AABB["contributions"]], "-> g =", v(AABB["g"]))
print("z1 =", v(AABB["z1"]), "-> pi1 =", v(AABB["pi1"]), "; adding ETA * g to pi instead would give", v(PI_OLD + ETA * AABB["g"]))
assert AABB["b"] == 0.5 and AABB["sigma"] == 0.5 == np.std([1.0, 1.0, 0.0, 0.0]) and v(AABB["w"]) == (1, 1, -1, -1)
assert v(AABB["g"]) == (0.5, -0.5) and v(AABB["z1"]) == (0.25, -0.25)
assert math.isclose(AABB["pi1"][0], 1 / (1 + math.exp(-0.5)), rel_tol=1e-15)
old, new = AABB["old"], AABB["new"]
print("J:", old["J"], "->", round(new["J"], 12), "while the recorded mean stays", AABB["b"])
print("L at z_old:", old["L"], "gradient", v(old["grad"]), "| L at z1:", round(new["L"], 12), new["branches"])
print("ratios at z1:", v(new["rho"]), "outside [0.8, 1.2]: nothing projects them back; gradient", v(new["grad"]))
assert old["L"] == 0 and np.array_equal(old["grad"], AABB["g"]) and math.isclose(new["L"], 0.2, rel_tol=1e-15)
assert new["branches"] == ["clipped"] * 4 and not new["grad"].any() and new["L"] <= new["unclipped"]

# Central differences through the fixed-record surrogate and through J confirm both gradients at z_old.
h, w, recs = 1e-6, AABB["w"], AABB["recs"]
for c in range(2):
    up, down = Z_OLD.copy(), Z_OLD.copy()
    up[c], down[c] = h, -h
    dL = (surrogate(recs, w, softmax(up))["L"] - surrogate(recs, w, softmax(down))["L"]) / (2 * h)
    dJ = (softmax(up)[0] - softmax(down)[0]) / (2 * h)
    assert abs(dL - AABB["g"][c]) < 1e-9 and abs(dJ - (0.25, -0.25)[c]) < 1e-9

# 2. AAAB: the group mean is 0.75, but every denominator is still pi_old = 0.5.
AAAB = analyze(group("AAAB"))
print("AAAB: b =", AAAB["b"], "; old denominators", v(AAAB["old_prob"]), "; weights", v(AAAB["w"]), "; g =", v(AAAB["g"]))
assert np.array_equal(AAAB["old_prob"], [0.5] * 4)                                # not the group's 3/4 and 1/4
assert np.allclose(AAAB["w"], [3 ** -0.5] * 3 + [-(3 ** 0.5)], rtol=1e-15, atol=0)
assert np.allclose(analyze(group("ABBB"))["g"], AAAB["g"], rtol=1e-15, atol=0)   # the same step, from mean 0.25

# 3. A flat group: every score known and equal. Zero signal by convention, not an optimum.
for order in ("AAAA", "BBBB"):
    flat = analyze(group(order))
    assert flat["sigma"] == 0 and not flat["w"].any() and not flat["g"].any() and np.array_equal(flat["pi1"], PI_OLD)
    print(f"{order}: b = {flat['b']}, sigma = 0, zero weights, no step; grad J at z_old is still (0.25, -0.25)")

# 4. The fixed AABB group at supplied candidates: L(p) = min(2p - 1, 0.2).
for p in (0.6, 0.9, 0.3, 0.1):
    e = evaluate_candidate(group("AABB"), p)
    assert math.isclose(e["L"], min(2 * p - 1, 0.2), rel_tol=1e-12)
    print(f"p = {p}: L {e['L']:.6f}, clip only {e['clipped_only']:.6f}, KL(old || p) {e['kl']:.12f}, J {e['J']}")
assert evaluate_candidate(group("AABB"), 0.6)["grad"] is None                        # the favored bounds: a kink

# At p = 0.4 the A rows (w > 0) sit at 0.8 and the B rows (w < 0) at 1.2: their unfavorable bounds. The kept
# minimum is smooth there, dL/dp = 2, so the logit gradient is 2 p (1 - p) (1, -1) = (0.48, -0.48). At 0.6 the
# one-sided slopes are 2 and 0.
L_at = lambda p: evaluate_candidate(group("AABB"), p)["L"]
at_04, h = evaluate_candidate(group("AABB"), 0.4), 1e-6
assert at_04["branches"] == ["inside"] * 4 and np.allclose(at_04["grad"], [0.48, -0.48], rtol=1e-14, atol=0)
assert abs((L_at(0.4 + h) - L_at(0.4 - h)) / (2 * h) * 0.4 * 0.6 - at_04["grad"][0]) < 1e-8
left, right = (L_at(0.6) - L_at(0.6 - h)) / h, (L_at(0.6 + h) - L_at(0.6)) / h
assert abs(left - 2) < 1e-6 and abs(right) < 1e-6
print("p = 0.4: ratios", v(at_04["rho"]), "on their unfavorable bounds, smooth; gradient", v(at_04["grad"]),
      "| p = 0.6: one-sided slopes", round(left, 6), "and", round(right, 6))

# 5. All sixteen ordered groups, each with probability 1/16.
orders = ["".join(o) for o in product("AB", repeat=4)]
g_A = [analyze(group(o))["g"][0] for o in orders]
counts = [sum(o.count("A") == k for o in orders) for k in range(5)]
assert counts == [math.comb(4, k) for k in range(5)] == [1, 4, 6, 4, 1]
assert all(math.isclose(x, math.sqrt(o.count("A") * (4 - o.count("A"))) / 4, abs_tol=1e-15) for x, o in zip(g_A, orders))
E = sum(g_A) / 16


def exact_A(order, centered):
    """(1/4) sum of weight * (e_a - pi_old)_A in exact fractions, with weight R - b or the raw R."""
    R = [Fraction(REWARD[a]) for a in order]
    b = sum(R) / 4 if centered else 0
    return sum((r - b) * (Fraction(1, 2) if a == "A" else Fraction(-1, 2)) for r, a in zip(R, order)) / 4


centered, raw = (sum(exact_A(o, c) for o in orders) / 16 for c in (True, False))
print("counts", counts, "; E[g_A] =", round(E, 12), "; centering only", centered, "; raw rewards", raw, "= grad J_A")
assert math.isclose(E, 3 / 16 + math.sqrt(3) / 8, rel_tol=1e-15) and (centered, raw) == (Fraction(3, 16), Fraction(1, 4))

# 6. A different divisor, for comparison only.
print("sample std + 1e-4 on AABB:", v(sample_std_plus_epsilon([1, 1, 0, 0]), 8))


# 7. Refusals: an incomplete, invalid or contradictory record is never filled, dropped or read as a flat group.
def refusal(f, *args):
    try:
        f(*args)
    except GroupUpdateError as error:
        return error.code
    return None


missing = group("AABB")
missing[3]["reward"] = None
assert refusal(analyze, missing) == "missing-feedback"
assert refusal(analyze, group("AABB")[:3]) == "malformed-group"
assert refusal(analyze, [dict(r, reward=float("nan")) if r["id"] == "e2" else r for r in group("AABB")]) == "nonfinite-feedback"
assert refusal(analyze, [dict(r, reward=1) for r in group("AABB")]) == "contradictory-feedback"
assert refusal(analyze, [dict(r, reward=True) if r["id"] == "e1" else r for r in group("AABB")]) == "invalid-feedback-type"
assert refusal(evaluate_candidate, group("AABB"), 0.99) == "invalid-candidate"
print("refusals checked")
The helper refuses rather than repairs: no zero fill, dropped record, epsilon or clamping. Each line is its actual response. A refusal is not always ignorance: the first record’s value is fixed by the rule, but the record itself is incomplete.
missing-feedback: record e4 has no stored score. Under the stated rule action B scores 0, but a record must carry its own score: supply a corrected record; nothing is filled innonfinite-feedback: record e2: a score must be finitecontradictory-feedback: record e4: under the stated rule, action B scores 0, not 1invalid-feedback-type: record e1: a score must be a numbermalformed-group: a group must have 4 entriesduplicate-id: record ID e1 appears twiceinvalid-candidate: π(A) must be a finite number from 0.05 to 0.95Rehearsal with the worked values in view. Opening an answer is help, and nothing is recorded. This is practice, not an assessment.
In AABB, e3 chose B and scored 0. Why does its row push the policy toward A?
Its weight is −1 (below the mean 0.5). Its score vector is (−½, ½); times −1 it is (½, −½), the same direction as the A rows.
In AAAB the mean reward is 0.75. What goes in each ratio’s denominator?
πold of the record’s own action, ½ for every record. The group’s frequencies ¾ and ¼ are not the old policy.
After the AABB step, L = 0.2 and the ratios are 1.2449 and 0.7551. Did clipping stop the step at the band?
No. The step was computed at πold, where the clip is inactive, and nothing projects it back. Clipping only makes L flat once a ratio has passed the band in its favored direction.
AAAA, and part 5’s black-box group whose fourth score never came back, both leave π where it was. What is different?
AAAA is fully scored: zero weights by the convention used here, no relative signal. In the black-box group no rule determines the missing score, so b, σ and every weight are unknown: the calculation is unavailable, not zero. Under this page’s rule a record missing its score is also refused, but there its value is determined; the record must be corrected, not filled in silently.
What is the smallest example of RLHF you can work through by hand, and what does it show?
concept:alignment/rlhfAfter the first pass
Section by section
RLHF trains a reward model from pairwise preferences, then reweights a reference policy toward high learned reward while a KL penalty limits distribution shift.
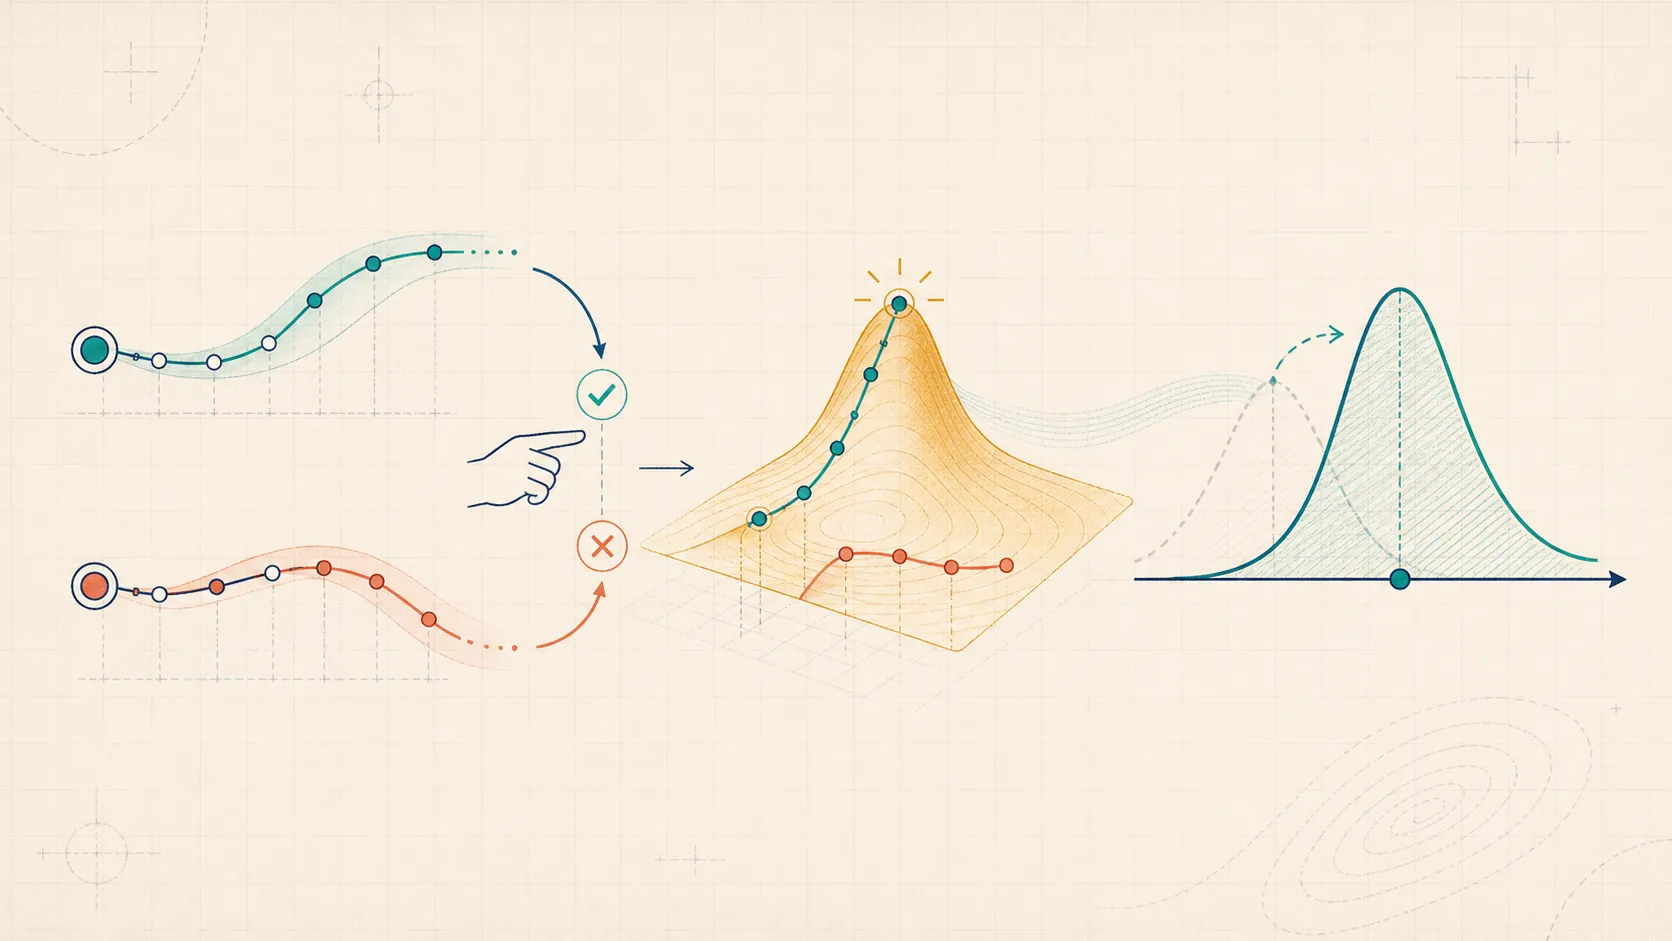
Choose what you expect to see in this section of RLHF: Reward Modeling + KL-Regularized Policy Optimization.
Looking at the picture
RLHF trains a reward model from pairwise preferences, then reweights a reference policy toward high learned reward while a KL penalty limits distribution shift.
Pick the part of the picture you expect to explain RLHF: Reward Modeling + KL-Regularized Policy Optimization.
Sources
NeurIPS 2017. Fits a reward model to human comparisons of pairs of short behavior clips and trains a policy against the learned reward.
NeurIPS 2022. The InstructGPT pipeline: supervised fine-tuning on demonstrations, a reward model trained on human rankings, then PPO against that reward with a per-token KL penalty to the supervised model.
NeurIPS 2020. Trains a reward model on human comparisons of summaries and fine-tunes the summarizer with PPO, subtracting a KL penalty to the supervised model from the reward.
arXiv preprint. Applies preference-trained reward models to language models and subtracts beta times log(pi/rho) from the reward, a KL penalty that keeps the policy pi close to the pretrained model rho.
arXiv preprint. Defines PPO, the clipped policy-gradient method that Ziegler et al., Stiennon et al. and Ouyang et al. use as the RL optimizer. (Christiano et al. predate it and used TRPO and A2C.)
arXiv preprint. Introduces GRPO: PPO's clipped objective without a value function; each sampled output's reward is normalized by its group's mean and standard deviation, with a KL penalty to a reference model in the loss.
Biometrika 39(3/4). The paired-comparison model behind the reward-model likelihood: with exp(r) as each item's strength, P(i beats j) = sigma(r_i - r_j).
Manning, 2026; the same text is free on arXiv and at rlhfbook.com. A book-length treatment of reward modeling, KL regularization, policy-gradient optimizers such as PPO and direct alignment methods such as DPO.
Claims and sources
The checks were made by this site, not by an independent reviewer.
Christiano et al. fit a reward model to pairwise human comparisons and optimize a policy against it. Ouyang et al. add supervised fine-tuning and run PPO with a per-token KL penalty to the supervised model.
Covers the preference model and the KL-regularized optimum only. A learned reward is not the true human objective, PPO need not reach the finite-action optimum, the pretraining-gradient mix (PPO-ptx) is not...
Christiano et al. learn a reward model from pairwise preferences between trajectory segments and optimize a policy against it. Ouyang et al. describe InstructGPT: supervised fine-tuning on demonstrations, a reward model trained on rankings, and PPO against that reward with a per-token KL penalty to the supervised model. The small math, code and demo on this page illustrate sigmoid preferences, KL reweighting, invariance to a reward shift and the proxy gap.
Practice · RLHF: Reward Modeling + KL-Regularized Policy Optimization
RLHF trains a reward model from pairwise preferences, then reweights a reference policy toward high learned reward while a KL penalty limits distribution shift.
Concept · Selected for practice
What it rests on: Sources: Deep reinforcement learning from human preferences; Training language models to follow instructions with human feedback; Learning to summa...
Alignment
For RLHF: Reward Modeling + KL-Regularized Policy Optimization: What is the smallest example of RLHF you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
assert np.allclose(pi_star, pi_shifted)Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of RLHF you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 8 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/alignment/rlhf
concept:alignment/rlhf