Why it is cited
NeurIPS 2023. Derives DPO from the KL-regularized RLHF objective: the optimal policy defines an implicit reward, and the Bradley-Terry likelihood of that reward becomes a binary cross-entropy loss on the policy itself.
DPO turns pairwise preferences into binary cross-entropy on reference-relative log odds, using the KL-regularized RLHF optimum to make the policy itself an implicit reward model.
The idea in plain words, before the symbols.
Suppose a prompt has two candidate completions:
RLHF usually trains a reward model , then runs an RL algorithm to make the policy choose higher-reward outputs while staying close to a reference model.
DPO asks a sharper question: can the policy itself act as the reward model?
Under the KL-regularized RLHF objective, the answer is yes, but only up to a prompt-only constant. If a policy has moved away from the reference model, that movement gives a convenient representative of an implicit reward class:
The exact reward can differ from this representative by a term that depends only on . Only reward differences matter for preference pairs, so that prompt-only term cancels, and DPO compares how much the current policy has changed the winner-vs-loser odds relative to the reference policy.
The core idea is:
A preferred response should beat a rejected response by more than the reference model already made it beat it.
That "more than the reference" phrase is the whole mechanism. DPO is not just "make the winner more likely." It is binary cross-entropy on reference-relative log odds.
A finite set of recorded comparisons constrains only the pairs it compares. Records that compare A with B say how the policy should move A relative to B; they say nothing about a response they never mention, or about how that response should be judged. The preference-coverage investigation follows four such records through one update, then separates what they fit from what they leave undecided.
Sources. DPO was introduced by Rafailov et al. (2023), "Direct Preference Optimization: Your Language Model is Secretly a Reward Model". Azar et al. (2024), "A General Theoretical Paradigm to Understand Learning from Human Preferences", analyze when its regularization fails, and Xu et al. (2024), "Is DPO Superior to PPO for LLM Alignment?", compare it with PPO-based RLHF.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
DPO's implicit reward is the -scaled policy/reference log-ratio:
For a prompt , is the full sequence probability of completion . In an autoregressive language model,
A preference datum is . All compared completions must have positive probability under the reference policy for the log ratio to be finite.
Define the policy and reference log-odds:
and
The reference-relative margin is
DPO predicts the preference probability as
For one hard winner/loser label, the DPO loss is
Let . The browser demo below uses a soft target so the finite target log-odds is visible:
Ordinary hard-label DPO is the edge case , where an isolated two-response target diverges.
For a fixed prompt , write for the distribution-level KL from a candidate policy to the reference policy at that prompt. The direction is to :
Also write the expected reward as
The KL-regularized RLHF objective is to maximize
Its optimizer has the reweighted form
Rearrange it:
The partition term depends on the prompt, not on which completion won. Bradley-Terry preferences use reward differences, so the prompt-only term cancels between and .
The Bradley-Terry model (Bradley and Terry, 1952) writes a preference as
Substituting the implicit reward gives the DPO probability. With the margin from above:
Maximum likelihood on preference labels gives the DPO loss. This is why DPO is a supervised objective even though it comes from a KL-regularized RLHF derivation.
Here follows the DPO paper's convention: it is the coefficient on the KL penalty in the KL-regularized RLHF objective.
For a soft preference probability , matching requires
DPO removes the explicit reward-model training stage and the RL loop. It does not remove the assumptions behind preference learning.
It still relies on a pairwise preference model such as Bradley-Terry. It only identifies rewards up to prompt-dependent constants. It needs a usable reference policy. And in an isolated two-response hard-label setting, the logistic loss can keep increasing the winner-over-loser log-ratio rather than settling at a finite target.
Azar et al. (2024) make the last point precise: if a preference is deterministic, the DPO optimum gives the loser probability zero whatever the value of , so the KL term no longer holds the policy near the reference. With only a few comparisons per pair, the estimated preference can easily be 1 even when the true preference is, say, 0.8. Their IPO objective replaces the log-sigmoid with a squared loss whose target margin stays finite.
Removing the RL loop also does not settle which method works better. Xu et al. (2024) argue that DPO can favor responses that never appear in the preference data, and report that a carefully tuned PPO pipeline outperformed DPO on the dialogue and code-generation benchmarks they studied.
A finite set of records for the same prompt gives each record an oriented pair with its own scaled margin . The empirical objective used in the investigation below is the mean
Taking the mean is a choice made here; the paper's reference code returns one loss per pair. For a free categorical policy over the candidate completions, , so each record contributes
The weight is : a record the policy already orders well pulls weakly, and a badly ordered one pulls with weight near 1. The records constrain only the log-ratios of pairs they compare, so a completion that appears in no record is left free by . This is a small finite version of the concern Xu et al. raise about responses outside the preference data. The preference-coverage investigation works it through for three completions and four records, and notes where Appendix A.4 of the arXiv version used here (v3) prints a different orientation.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
This finite-action example checks the derivation in a setting where it holds exactly. A synthetic reward defines the KL-regularized target policy. DPO sees full-support, exact soft Bradley-Terry preference probabilities and recovers the same unconstrained categorical policy through reference-relative log-ratio cross-entropy. Sampled hard labels, missing pairs, or a restricted neural parameterization would not make the equality exact in finite data.
import numpy as np

def softmax(z):
    z = z - z.max()
    e = np.exp(z)
    return e / e.sum()

def sigmoid(x):
    return 1.0 / (1.0 + np.exp(-x))

def kl(p, q):
    return float(np.sum(p * (np.log(p) - np.log(q))))

# One prompt, three possible completions.
# Shapes: ref, reward, logits, pi are all (K,).
ref = np.array([0.15, 0.70, 0.15], dtype=float)
reward = np.array([1.0, 0.2, -0.5], dtype=float)
beta = 0.5
log_ref = np.log(ref)

# KL-regularized RLHF optimum:
# pi*(y|x) is proportional to pi_ref(y|x) exp(r(x,y)/beta).
pi_star = ref * np.exp(reward / beta)
pi_star = pi_star / pi_star.sum()

# DPO sees pairwise preferences. We use exact Bradley-Terry
# probabilities instead of sampled hard labels so the equality is visible.
pairs = [(0, 1), (0, 2), (1, 2)]

# Initialize policy at the reference.
logits = log_ref.copy()
lr = 0.2

for _ in range(3000):
    grad = np.zeros_like(logits)

    for i, j in pairs:
        rel_log_odds = (logits[i] - logits[j]) - (log_ref[i] - log_ref[j])
        pred = sigmoid(beta * rel_log_odds)

        target = sigmoid(reward[i] - reward[j])

        # Binary cross-entropy gradient for the soft preference target.
        g = beta * (pred - target)
        grad[i] += g
        grad[j] -= g

    logits -= lr * grad / len(pairs)
    logits -= logits.mean()  # logits are identifiable only up to a constant

pi = softmax(logits)

print("reference policy:      ", np.round(ref, 3))
print("KL-reg optimum:        ", np.round(pi_star, 3))
print("DPO learned policy:    ", np.round(pi, 3))
print("KL(pi || ref):         ", round(kl(pi, ref), 4))

assert np.allclose(pi, pi_star, atol=1e-6)

for i, j in pairs:
    implicit_gap = beta * (
        (np.log(pi[i]) - np.log(ref[i]))
        - (np.log(pi[j]) - np.log(ref[j]))
    )
    reward_gap = reward[i] - reward[j]
    assert abs(implicit_gap - reward_gap) < 1e-6

for i, j in pairs:
    dpo_pref = sigmoid(beta * (
        (np.log(pi[i]) - np.log(ref[i]))
        - (np.log(pi[j]) - np.log(ref[j]))
    ))
    bt_pref = sigmoid(reward[i] - reward[j])
    assert abs(dpo_pref - bt_pref) < 1e-6
The preference-coverage investigation below the demo has its own code for a different example: four hard-label records over three completions, row losses computed stably from logit differences, the averaged gradient and one step, supplied policies that fit the records equally well, and a NumPy transcription of the paper's Appendix B dpo_loss, which refuses inputs outside its supported domain. The site's tests run that code; the code above is unchanged.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Direct Preference Optimization, then open its guide.
The demo collapses the world to two completions, and , so its KL is the binary KL over this toy pair, not the full language-model KL over all completions. Change the reference winner probability, the soft target preference, and . Watch how the required policy log-odds moves relative to the reference, how the DPO probability changes, and when the two-action KL from the reference spikes.
The demo works as soon as the page loads. A short question after it is optional practice and changes nothing in the demo.
After this section, the preference-coverage investigation is a different example: three complete responses, four recorded hard-label comparisons and one full-batch update with fixed and step size, followed by policies that fit those records equally well and evaluation rubrics written separately.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Investigation · three responses, four recorded comparisons
Four example records about one prompt cause one calculable update. Policies that fit those records equally well can still treat response C very differently, and nothing in the records says how C should be judged. The parts below keep three things apart: the fit to the records, the step one optimizer actually takes, and an evaluation written separately.
Illustrative numbers in a finite teaching calculation, not a training run, a dataset or a measurement of human values. Fixed here: β = ½, step size η = 1, reference q = (⅓, ⅓, ⅓), start z₀ = (0, 0, 0). The ratio demo above keeps its own two-response example and controls; nothing here changes it or is saved.
In words: the A–B pair has 3 records one way and 1 the other. No record compares A with C or B with C, so C is uncompared. An absent comparison is not a judgment that C is bad, and it is not a held-out prompt.
m = (zw − zℓ) − log(qw / qℓ)v = βmrow loss −log σ(v)row gradient −β σ(−v)(ew − eℓ)L = mean of the rowsz₁ = z₀ − η∇L
Softmax normalization cancels inside zw − zℓ, which equals log πw − log πℓ. The reference term is written even though it is log 1 = 0 here. All four rows are evaluated at the same z₀, averaged, and then one update is made.
| Record | Preferred | m at z₀ | σ(v) at z₀ | Loss at z₀ | Gradient at z₀ (A, B, C) | Loss at z₁ |
|---|---|---|---|---|---|---|
r1 | A ≻ B | 0 | 0.5 | 0.693147 | (−0.25, 0.25, 0) | 0.632599 |
r2 | A ≻ B | 0 | 0.5 | 0.693147 | (−0.25, 0.25, 0) | 0.632599 |
r3 | A ≻ B | 0 | 0.5 | 0.693147 | (−0.25, 0.25, 0) | 0.632599 |
r4 | B ≻ A | 0 | 0.5 | 0.693147 | (0.25, −0.25, 0) | 0.757599 |
| Mean of 4 | 0.693147 | (−0.125, 0.125, 0) | 0.663849 |
r4 prefers B to A. At z₀ its margin is m = (zB − zA) − log(qB / qA) = (0 − 0) − log 1 = 0, so v = 0, σ(v) = 0.5 and its loss is −log σ(v) = 0.693147. Its gradient −β σ(−v)(eB − eA) = (0.25, −0.25, 0). Subtracting it would, for this record alone, raise zB and lower zA. After the averaged step its loss is 0.757599, higher than before.
z₁ = (0, 0, 0) − 1 · (−0.125, 0.125, 0) = (0.125, −0.125, 0)
C’s logit did not move: its gradient entry is 0. Its probability still fell, from 0.333333 to 0.331604, because πC = ezC / (ezA + ezB + ezC) and the denominator grew from 3 to 3.015645. With shared neural parameters C’s logit need not stay fixed; the free logits here are a deliberate simplification.
The mean loss fell from 0.693147 to 0.663849, while r4’s own loss rose to 0.757599. A lower mean does not mean every record is better fitted.
This is one step of one optimizer from one start, with β and η fixed. It is not a training run, and its result is not one of the policies in part 3.
Over all strictly positive policies, the smallest mean record loss is 0.562335, reached when the model’s predicted probability that A is preferred to B equals the records’ 3/4. At β = ½ and this reference that fixes one ratio, πA / πB = 9. Nothing in the records fixes πC. The two policies below are supplied for comparison; neither was produced by the step in part 2.
| Quantity | Value | What it is |
|---|---|---|
| Records preferring A to B | 3/4 | A proportion of these four example labels |
| σ(βm) for A over B | 0.75 at P and Q; 0.531209 after the step | The model’s predicted preference, which the loss fits |
| πA / (πA + πB) | 0.9 at P and Q | Sampling A when A or B is sampled |
| πA | 0.81 at P; 0.27 at Q | Sampling A at all. Q’s is below qA = ⅓ although its A/B odds rose. |
This control chooses which fitted policy to look at. It is not training time and not a path any optimizer follows. Every c between 0 and 1 gives the same loss; the 0.05–0.95 range is a display choice, not an inferred bound. P is c = 0.10 and Q is c = 0.70.
Mean record loss 0.562335, πA / πB = 9: the same as P and Q.
Fit is not the optimizer’s choice. Repeating the worked step keeps zA + zB = 0 and zC = 0, so every iterate has πAπB = πC². Its stationary point is (9/13, 1/13, 3/13) ≈ (0.692, 0.077, 0.231), the member c = 3/13. P (0.0729 against 0.01) and Q (0.0081 against 0.49) are off that curve, so neither is a checkpoint of that run. Which fitted policy an optimizer returns depends on its start and update rule; that selection is not further evidence about preferences.
| Policy | πAuA | πBuB | πCuC | Expected score | Record loss |
|---|---|---|---|---|---|
| P | 0.81 | 0 | 0 | 0.81 | 0.562335 |
| Q | 0.27 | 0 | 0 | 0.27 | 0.562335 |
| π(c = 0.30) | 0.63 | 0 | 0 | 0.63 | 0.562335 |
Under uold = (1, 0, 0), P scores higher: 0.81 against 0.27. The two rubrics reverse the ranking of two policies that fit the records equally well.
Unchanged by this choice: the 4 records, the record loss 0.562335 of every row above, and the worked step z₁ = (0.125, −0.125, 0).
Equal fit is not complete alignment, and an unjudged response to the same prompt is not a held-out prompt: nothing here is evidence about generalization.
With π = softmax(z), log πy = zy − log Σk ezk, so ∇z log πy = ey − π and ∇z(log πw − log πℓ) = ew − eℓ. The reference q is fixed, so ∇zv = β(ew − eℓ).
For one record, ℓ(v) = −log σ(v) = log(1 + e−v), so dℓ/dv = −σ(−v) and ∇zℓ = −β σ(−v)(ew − eℓ). A well-ordered record (large v) pulls weakly; a badly ordered one pulls with weight near 1.
With nAB = 3 and nBA = 1, the mean is L = −(3 log s + log(1 − s)) / 4 with s = σ(β(zA − zB − log(qA/qB))). This is an average of hard labels, not label smoothing. It is minimized at s = 3/4, which gives zA − zB = log(qA/qB) + logit(3/4)/β = 2 log 3, so πA/πB = 9, with minimum H(3/4) = 0.562335 nats. zC does not appear.
Every gradient has the form (g, −g, 0). From z₀ = 0, plain steps therefore keep z = (a, −a, 0), with a ← a + ½η(¾ − σ(a)) at β = ½. The fixed point is a = log 3, giving (9/13, 1/13, 3/13). A finite number of steps approaches it; this holds for this start and plain full-batch steps, not for other initializations, momentum, weight decay or shared parameters.
The ledger’s coverage: the compared responses split into {A, B} and {C}, so no unique policy is identified.
Records r5 (B ≻ C) and r6 (C ≻ B) are appended under the same comparison task. They are two judgments, not a tie label and not proof of indifference. The comparisons now link A, B and C, and the minimizer is unique up to a common logit shift: π = (9/11, 1/11, 1/11) ≈ (0.818182, 0.090909, 0.090909), with mean record loss 0.605939.
In this changed ledger the four-record family no longer fits equally: P gives 0.606055 and Q gives 0.700098. The mean 0.605939 belongs to a different dataset than 0.562335; comparing the two is not a measure of improvement.
Whole-ledger copies. The whole ledger written three times, with distinct IDs, makes 12 rows in the same proportions. At z₁ the mean loss is 0.663849 (the four-record value is 0.663849) and the mean gradient is unchanged; only the summed loss triples. Copies are not independent evidence, and they still say nothing about C.
One more A ≻ B record. The counts become 4:1, the share 0.8, and the optimal A/B odds (4)1/β = 16 instead of 9. Duplicating an existing favorable row would reweight the objective in the same way without adding a new judgment.
B ≻ C only. Adding just r5 connects all three responses, but the B–C comparison is one-sided: pushing πC toward 0 keeps lowering the loss (0.593835 at c = 0.1, 0.505064 at c = 0.01, 0.456095 at c = 0.0001) toward (4/5)H(3/4) = 0.449868, which no strictly positive policy attains. Connectedness alone does not give a finite fit. Three A ≻ B records and no reverse record likewise have no finite optimum for the A–B log-ratio.
KL(P ‖ q) = 0.480955 and KL(Q ‖ q) = 0.390223 nats over all three responses. In the source, β is the coefficient of this KL in the regularized objective from which the loss is derived, but the recorded loss itself has no KL term. A smaller KL is not a tie-break the records supply, and it does not make either policy the intended one.
| In the source | Here |
|---|---|
| Eq. 7 (§4, printed p. 4): −log σ of β times the winner-minus-loser policy/reference log-ratio difference | Each record’s loss −log σ(v), v = βm |
| §4 gradient (printed p. 5): weight σ(r̂ℓ − r̂w) on ∇log πw − ∇log πℓ | −β σ(−v)(ew − eℓ) for free categorical logits |
Appendix B dpo_loss (printed p. 20): per-pair losses and detached rewards | pi_logps = log_softmax(z) over (A, B, C), ref_logps = log q, yw_idxs = (0, 0, 0, 1), yl_idxs = (1, 1, 1, 0) |
| Not in the source’s function | The mean over rows and one step on free logits are additions made here. No reward model, RL loop or neural network is involved. |
| §6.4, Appendix C.2 and §7 | The paper’s own evaluations and discussion. They do not report this constructed utility reversal and are not evidence of generalization here. |
A discrepancy in this version. Appendix A.4 (printed p. 17) writes the loss as Eq. 21 with the loser-minus-winner margin inside −log σ, and its final gradient weights each pair by σ(v) rather than σ(−v). Eq. 7, the §4 gradient and Appendix B all use the winner-minus-loser margin, and differentiating Eq. 7 gives the weight σ(−v). This page follows Eq. 7; the note concerns this PDF version, not the method or other versions.
The weights agree only at v = 0, so the worked step at z₀ cannot tell them apart. At P, where each A ≻ B record has v = log 3, the correct weight is σ(−log 3) = ¼, not ¾. The correct mean gradient at P is (0, 0, 0); the printed weight would give (−0.25, 0.25, 0), as though P were not yet fitted.
A different freedom. The source identifies rewards only up to a prompt-only term β log Z(x). Moving from P to Q changes the detached scores β log(π/q) by (−0.549306, −0.549306, 0.972955): not one constant for all responses. The freedom here comes from comparisons that were never recorded.
Source: Rafailov et al. (2023). Direct Preference Optimization: Your Language Model is Secretly a Reward Model. NeurIPS 2023. arXiv:2305.18290v3 (PDF).
A separate implementation of the ledger, update, policy logits, log-softmax and implicit scores. The site’s test suite runs this exact text with Python and NumPy and compares shared valid and invalid cases with the TypeScript helper. The rubric, interval, sampling-share, identification and display helpers exist only in TypeScript.
import math
import re
from fractions import Fraction

import numpy as np

# One prompt; three complete responses, always in the order A, B, C.
RESPONSES = ("A", "B", "C")
ID_PATTERN = re.compile(r"[A-Za-z0-9][A-Za-z0-9._:-]{0,63}", re.ASCII)
MAX_RECORDS = 10_000
SUM_TOLERANCE = 1e-12


class PreferenceCoverageError(ValueError):
    """A coded refusal: the calculation does not apply, or a value is not representable."""

    def __init__(self, code, detail):
        super().__init__(f"{code}: {detail}")
        self.code = code


def real(x):
    """A Python int or float as binary64, else None. A bool is not a number here."""
    if isinstance(x, bool) or not isinstance(x, (int, float)):
        return None
    try:
        return float(x)
    except OverflowError:
        return None


def vector(value, what):
    if not isinstance(value, (list, tuple)) or len(value) != 3:
        raise PreferenceCoverageError("malformed-vector", f"{what} must be exactly three numbers")
    xs = [real(x) for x in value]
    if None in xs:
        raise PreferenceCoverageError("malformed-vector", f"{what} has a missing or non-numeric entry")
    return xs


def check_logits(z):
    z = vector(z, "logits")
    if not all(map(math.isfinite, z)):
        raise PreferenceCoverageError("nonfinite-logit", "every logit must be finite")
    return z


def check_distribution(p, role):
    """Three finite, strictly positive entries summing to 1: never clamped or renormalized."""
    p = vector(p, role)
    if not all(map(math.isfinite, p)):
        raise PreferenceCoverageError(f"{role}-nonfinite", f"every {role} entry must be finite")
    if any(x < 0 for x in p):
        raise PreferenceCoverageError(f"{role}-negative", f"a {role} entry is negative")
    if any(x == 0 for x in p):
        raise PreferenceCoverageError(f"{role}-zero", "a structural zero: its log-ratio is undefined, so the calculation does not apply")
    if not abs(p[0] + p[1] + p[2] - 1) <= SUM_TOLERANCE:
        raise PreferenceCoverageError(f"{role}-not-normalized", f"{role} entries must sum to 1 within {SUM_TOLERANCE}")
    return p


def check_beta(beta):
    b = real(beta)
    if b is None or not math.isfinite(b) or not b > 0:
        raise PreferenceCoverageError("invalid-beta", "beta must be finite and greater than 0")
    return b


def check_step_size(eta):
    e = real(eta)
    if e is None or not math.isfinite(e) or not e >= 0:
        raise PreferenceCoverageError("invalid-step-size", "the step size must be finite and at least 0")
    return e


def check_records(records):
    """Each record is (id, winner, loser). An empty ledger has no mean and no update."""
    if not isinstance(records, (list, tuple)):
        raise PreferenceCoverageError("malformed-ledger", "records must be a list")
    if not records:
        raise PreferenceCoverageError("empty-ledger", "no records: no empirical mean and no update, not a loss of 0")
    if len(records) > MAX_RECORDS:
        raise PreferenceCoverageError("too-many-records", f"at most {MAX_RECORDS} records")
    seen = set()
    for i, record in enumerate(records):
        if not isinstance(record, (list, tuple)) or len(record) != 3:
            raise PreferenceCoverageError("malformed-record", f"record {i} must be (id, winner, loser)")
        rid, w, l = record
        if not isinstance(rid, str) or not ID_PATTERN.fullmatch(rid):
            raise PreferenceCoverageError("invalid-id", f"record {i} needs an ID such as r1")
        if not all(isinstance(x, str) and x in RESPONSES for x in (w, l)):
            raise PreferenceCoverageError("invalid-label", f"record {rid}: winner and loser must be A, B or C")
        if w == l:
            raise PreferenceCoverageError("same-response", f"record {rid} compares {w} with itself")
        if rid in seen:
            raise PreferenceCoverageError("duplicate-id", f"record ID {rid} appears twice")
        seen.add(rid)
    return [tuple(r) for r in records]


def softplus(x):
    """log(1 + e^x) without overflow. A record's loss is softplus(-v) = -log sigmoid(v)."""
    return x + math.log1p(math.exp(-x)) if x > 0 else math.log1p(math.exp(x))


def sigmoid(x):
    if x >= 0:
        return 1 / (1 + math.exp(-x))
    e = math.exp(x)
    return e / (1 + e)


def mean(values):
    """Divide each term first, add left to right (not sum(), which compensates); refuse a mean that rounds past the largest double."""
    n, total = len(values), 0.0
    for v in values:
        total += v / n
    return finite(total, "the mean")


def finite(x, what):
    if not math.isfinite(x):
        raise PreferenceCoverageError("unrepresentable", f"{what} is not representable in binary64")
    return x


def evaluate(z, q, records, beta):
    """Every record at the same logits z, then the mean loss and the mean gradient."""
    beta, z = check_beta(beta), check_logits(z)
    q, records = check_distribution(q, "reference"), check_records(records)
    log_q = [math.log(x) for x in q]
    rows = []
    for rid, w, l in records:
        i, j = RESPONSES.index(w), RESPONSES.index(l)
        policy = finite(z[i] - z[j], "z_w - z_l")  # = log pi_w - log pi_l: the normalizer cancels
        reference = log_q[i] - log_q[j]  # kept explicit even when it is 0
        m = finite(policy - reference, "the margin m")
        v = finite(beta * m, "beta * m")
        grad = [0.0, 0.0, 0.0]
        grad[i], grad[j] = -beta * sigmoid(-v), beta * sigmoid(-v)  # -beta sigma(-v) (e_w - e_l)
        rows.append({"id": rid, "m": m, "v": v, "s": sigmoid(v), "loss": softplus(-v), "grad": grad})
    return {
        "rows": rows,
        "loss": mean([r["loss"] for r in rows]),
        "grad": [mean([r["grad"][c] for r in rows]) for c in range(3)],
    }


def step(z, q, records, beta, eta):
    """One full-batch update: all rows at the same z, averaged, then z' = z - eta * mean gradient."""
    beta, eta, z = check_beta(beta), check_step_size(eta), check_logits(z)
    before = evaluate(z, q, records, beta)
    z_next = [finite(z[c] - eta * before["grad"][c], "a stepped logit") for c in range(3)]
    return z_next, before, evaluate(z_next, q, records, beta)


def softmax(z):
    top = max(z)
    e = [math.exp(x - top) for x in z]
    return [x / (e[0] + e[1] + e[2]) for x in e]


def policy_logits(p):
    """z = log pi for a supplied positive policy (any common shift would do)."""
    return [math.log(x) for x in check_distribution(p, "policy")]


# Appendix B of the source (arXiv 2305.18290v3), with NumPy in place of PyTorch.
# -F.logsigmoid(x) is softplus(-x), which np.logaddexp(0, -x) computes stably.
def dpo_loss(pi_logps, ref_logps, yw_idxs, yl_idxs, beta):
    pi_yw_logps, pi_yl_logps = pi_logps[yw_idxs], pi_logps[yl_idxs]
    ref_yw_logps, ref_yl_logps = ref_logps[yw_idxs], ref_logps[yl_idxs]
    pi_logratios = pi_yw_logps - pi_yl_logps
    ref_logratios = ref_yw_logps - ref_yl_logps
    losses = np.logaddexp(0.0, -beta * (pi_logratios - ref_logratios))
    rewards = beta * (pi_logps - ref_logps)  # .detach() in the source: scores, not a training signal
    return losses, rewards


def log_softmax(z):
    """In shifted coordinates, so a common offset cannot absorb the normalizer; an unrepresentable shift is refused."""
    z = check_logits(z)
    top = max(z)
    shifted = [finite(x - top, "a shifted logit") for x in z]
    return np.array(shifted) - math.log(math.exp(shifted[0]) + math.exp(shifted[1]) + math.exp(shifted[2]))


def implicit_scores(p, q, beta):
    """beta log(pi / q) per response, the source's detached score; a product out of range is refused."""
    beta, p, q = check_beta(beta), check_distribution(p, "policy"), check_distribution(q, "reference")
    return [finite(beta * (math.log(a) - math.log(b)), "a scaled score") for a, b in zip(p, q)]


q = [1 / 3, 1 / 3, 1 / 3]
records = [("r1", "A", "B"), ("r2", "A", "B"), ("r3", "A", "B"), ("r4", "B", "A")]
beta, eta, z0 = 0.5, 1.0, [0.0, 0.0, 0.0]

# 1. One full-batch step from z0.
z1, before, after = step(z0, q, records, beta, eta)
print("row gradients at z0:", [r["grad"] for r in before["rows"]])
print("mean gradient:", before["grad"], "-> z1:", z1)
print("pi(z1):", [round(x, 12) for x in softmax(z1)])
print("mean loss:", round(before["loss"], 12), "->", round(after["loss"], 12))
print("row losses at z1:", [round(r["loss"], 6) for r in after["rows"]])
assert [r["grad"] for r in before["rows"]] == 3 * [[-0.25, 0.25, 0.0]] + [[0.25, -0.25, 0.0]]
assert before["grad"] == [-0.125, 0.125, 0.0] and z1 == [0.125, -0.125, 0.0]
# The same four rows written as counts: -(3 log s + log(1 - s)) / 4, with s = sigma(beta (z_A - z_B)).
s1 = sigmoid(beta * (z1[0] - z1[1]))
assert math.isclose(after["loss"], -(3 * math.log(s1) + math.log(1 - s1)) / 4, rel_tol=1e-14)
# The after-state again from literal logits, not from the step's own output. The mean fell; r4's loss rose.
again = evaluate([0.125, -0.125, 0.0], q, records, beta)
assert again["loss"] == after["loss"] < before["loss"] < after["rows"][3]["loss"]
# C's logit gradient is 0, yet pi_C moved: the softmax denominator changed.
assert before["grad"][2] == 0 and softmax(z1)[2] < 1 / 3
# The source's operation returns the same row losses at z0 and at z1.
chosen, rejected = np.array([0, 0, 0, 1]), np.array([1, 1, 1, 0])
for z, state in ((z0, before), (z1, after)):
    losses, _ = dpo_loss(log_softmax(z), np.log(q), chosen, rejected, beta)
    assert np.allclose(losses, [r["loss"] for r in state["rows"]], rtol=1e-13, atol=0)

# 2. Repeating this step keeps z_A + z_B = 0 and z_C = 0, so pi_A pi_B = pi_C ** 2 along the whole path.
z = z0
for _ in range(400):
    z, _, _ = step(z, q, records, beta, eta)
    assert z[0] + z[1] == 0 and z[2] == 0
print("400 steps approximate the stationary point (9/13, 1/13, 3/13):", [round(x, 9) for x in softmax(z)])
assert max(abs(a - b) for a, b in zip(softmax(z), [9 / 13, 1 / 13, 3 / 13])) < 1e-9

# 3. A different question: supplied policies that fit the four records equally well.
P, Q = [0.81, 0.09, 0.10], [0.27, 0.03, 0.70]
H = -(0.75 * math.log(0.75) + 0.25 * math.log(0.25))  # the minimum mean loss when 3 of 4 prefer A
for name, p in (("P", P), ("Q", Q)):
    fit = evaluate(policy_logits(p), q, records, beta)
    assert math.isclose(fit["loss"], H, rel_tol=1e-12) and max(map(abs, fit["grad"])) < 1e-12
    print(f"{name}: loss {fit['loss']:.12f}; predicted A over B {fit['rows'][0]['s']:.6f};",
          f"sampling A given A or B {p[0] / (p[0] + p[1]):.6f}; sampling A {p[0]:.2f};",
          f"pi_A pi_B - pi_C^2 = {p[0] * p[1] - p[2] ** 2:.4f}")


def kl(p):
    return sum(x * (math.log(x) - math.log(r)) for x, r in zip(p, q))


print(f"KL(P || q) = {kl(P):.12f}, KL(Q || q) = {kl(Q):.12f}; a diagnostic, the loss has no KL term")
# The source's detached scores change by different amounts per response from P to Q: not one prompt-only constant.
shift = np.subtract(implicit_scores(Q, q, beta), implicit_scores(P, q, beta))
assert np.allclose(shift, [-0.5 * math.log(3), -0.5 * math.log(3), 0.5 * math.log(7)])
_, rewards_P = dpo_loss(log_softmax(policy_logits(P)), np.log(q), chosen, rejected, beta)
assert np.allclose(rewards_P, implicit_scores(P, q, beta))  # the transcription's rewards are these scores


# 4. The pinned appendix's final line weights each record by sigma(v); Eq. 7 differentiates to sigma(-v).
def printed_weight_gradient(z, q, records, beta):
    rows, grads = evaluate(z, q, records, beta)["rows"], []
    for (_, w, l), row in zip(records, rows):
        g = [0.0, 0.0, 0.0]
        i, j = RESPONSES.index(w), RESPONSES.index(l)
        g[i], g[j] = -beta * row["s"], beta * row["s"]
        grads.append(g)
    return [mean([g[c] for g in grads]) for c in range(3)]


zP = policy_logits(P)
correct, printed = evaluate(zP, q, records, beta)["grad"], printed_weight_gradient(zP, q, records, beta)
print("gradient at P (v = log 3):", [round(x, 12) for x in correct], "; with the printed weight:", [round(x, 12) for x in printed])
assert max(map(abs, correct)) < 1e-12 and math.isclose(printed[0], -0.25, rel_tol=1e-12)
assert printed_weight_gradient(z0, q, records, beta) == before["grad"]  # equal at v = 0: a zero-margin test cannot tell

# 5. The analytic gradient against central differences, at nonzero margins and a nonuniform reference.
six = records + [("r5", "B", "C"), ("r6", "C", "B")]
q2, z2, h = [0.5, 0.25, 0.25], [0.3, -0.7, 1.1], 1e-6
g2 = evaluate(z2, q2, six, 0.8)["grad"]
for c in range(3):
    up, down = list(z2), list(z2)
    up[c], down[c] = z2[c] + h, z2[c] - h
    fd = (evaluate(up, q2, six, 0.8)["loss"] - evaluate(down, q2, six, 0.8)["loss"]) / (2 * h)
    assert abs(fd - g2[c]) < 1e-8

# 6. Evaluation: rubrics written for this page, in exact arithmetic. They change no record, logit, loss or gradient.
Pf = [Fraction(x) for x in ("0.81", "0.09", "0.10")]
Qf = [Fraction(x) for x in ("0.27", "0.03", "0.70")]


def utility(p, u):
    return sum(x * y for x, y in zip(p, u))


u_old, u_new = [1, 0, 0], [Fraction("0.2"), 0, 1]
print("u_old:", utility(Pf, u_old), utility(Qf, u_old), "| u_new:", utility(Pf, u_new), utility(Qf, u_new))
# C unscored: u = (0.2, 0, t) with t in [0, 1], so U(t) = 0.2 pi_A + pi_C t stays symbolic.
gap, slope = Pf[0] * Fraction("0.2") - Qf[0] * Fraction("0.2"), Pf[2] - Qf[2]
print(f"U_P(t) - U_Q(t) = {gap} + ({slope}) t; equal at t = {-gap / slope}")
assert -gap / slope == Fraction(9, 50) and gap > 0 > gap + slope  # P above Q at t = 0, below at t = 1

# 7. Optional data depth: a unique optimum, a connected graph without one, and copies.
fit6 = evaluate(policy_logits([9 / 11, 1 / 11, 1 / 11]), q, six, beta)
assert math.isclose(fit6["loss"], (4 * H + 2 * math.log(2)) / 6, rel_tol=1e-12) and max(map(abs, fit6["grad"])) < 1e-12
print(f"six records: optimum (9/11, 1/11, 1/11), mean loss {fit6['loss']:.12f}")
one_sided = records + [("r5", "B", "C")]
path = [evaluate(policy_logits([0.9 * (1 - c), 0.1 * (1 - c), c]), q, one_sided, beta)["loss"] for c in (0.1, 0.01, 0.0001)]
print("B over C only, as c -> 0:", [round(x, 12) for x in path], "> infimum 4H/5 =", round(4 * H / 5, 12))
assert path[0] > path[1] > path[2] > 4 * H / 5
copies = [(rid if k == 1 else f"{rid}-copy{k}", w, l) for k in (1, 2, 3) for rid, w, l in records]
assert math.isclose(evaluate(z1, q, copies, beta)["loss"], after["loss"], rel_tol=1e-14)  # same mean, not new evidence
selective = records + [("r5", "A", "B")]  # counts 4:1, so the optimal A/B odds are 16, not 9
assert max(map(abs, evaluate(policy_logits([0.8 * 16 / 17, 0.8 / 17, 0.2]), q, selective, beta)["grad"])) < 1e-12


# 8. Where the calculation does not apply, or a value is not representable: a coded refusal, no repair.
def refusal(f, *args):
    try:
        f(*args)
    except PreferenceCoverageError as error:
        return error.code
    return None


assert refusal(evaluate, z0, [0.5, 0.5, 0.0], records, beta) == "reference-zero"
assert refusal(evaluate, z0, [0.5, 0.25, 0.26], records, beta) == "reference-not-normalized"
assert refusal(evaluate, z0, q, [], beta) == "empty-ledger"
assert refusal(evaluate, z0, q, [("r1", "A", "A")], beta) == "same-response"
assert refusal(evaluate, z0, q, [("r1", "A", "Z")], beta) == "invalid-label"
assert refusal(evaluate, [1e308, -1e308, 0.0], q, records, beta) == "unrepresentable"
assert refusal(log_softmax, [1.7e308, -1.7e308, 0.0]) == "unrepresentable"
assert refusal(implicit_scores, [0.8, 0.1, 0.1], [0.01, 0.49, 0.5], 1e308) == "unrepresentable"
# A common offset keeps the normalizer: each log-probability is -log 3, not 0.
assert np.allclose(log_softmax([1e20, 1e20, 1e20]), [-math.log(3)] * 3, rtol=1e-15, atol=0)
extreme = evaluate([1000.0, -1000.0, 0.0], q, records, beta)  # pi_B and pi_C underflow to 0; the loss does not
assert extreme["loss"] == 250.0 and extreme["grad"] == [0.125, -0.125, 0.0] and softmax([1000.0, -1000.0, 0.0])[1:] == [0.0, 0.0]
print("refusals checked; at logits (1000, -1000, 0) the mean loss is", extreme["loss"])
The helper refuses rather than repairs: no epsilon, clamping, renormalizing or dropped record. Each line is its actual response.
reference-zero: a reference entry is exactly 0, so a log-ratio involving it is undefined; the calculation does not apply (no epsilon is added)reference-not-normalized: reference entries sum to 1.01, not 1 within 1e-12; nothing is renormalizedempty-ledger: no records: there is no empirical mean and no update (not a loss of 0)same-response: record r1 compares A with itselfduplicate-id: record ID r1 appears twiceinvalid-beta: beta must be a finite number greater than 0unrepresentable: z_A - z_B is not representable in binary64; nothing is returned or appliedFinite extremes are different: at logits (1000, −1000, 0) the displayed probabilities round to (1, 0, 0), yet the mean record loss is 250 and the mean gradient (0.125, −0.125, 0), computed from logit differences rather than from logs of rounded probabilities.
Rehearsal with the worked values above in view. Opening an answer is help; a later retry is practice, not a test. Nothing is recorded.
At z₀, which way does r4’s own gradient push zA, and why does the step still raise it?
r4’s gradient is (0.25, −0.25, 0); subtracting it lowers zA for that record alone. The step uses the mean: (3 · (−0.25) + 0.25) / 4 = −0.125 for A, so zA rises by 0.125.
zC is still 0 after the step. Why did πC change?
πC = 1 / (e0.125 + e−0.125 + 1): the normalizer grew from 3 to 3.015645.
P and Q have the same record loss. Which should be used?
The records cannot say. They fix πA/πB only. The answer depends on an evaluation rubric; with C’s score known only to lie in [0, 1], it depends on t. What is missing is a judgment about C, or comparisons that involve C.
Two extra copies of the whole ledger, or one extra A ≻ B record: which changes the optimum?
The extra record: counts 4:1 give odds 16. Whole-ledger copies keep the mean and the optimum. Neither is new independent evidence about C.
What is the smallest example of Direct Preference Optimization you can work through by hand, and what does it show?
concept:alignment/dpoAfter the first pass
Section by section
DPO turns pairwise preferences into binary cross-entropy on reference-relative log odds, using the KL-regularized RLHF optimum to make the policy itself an implicit reward model.
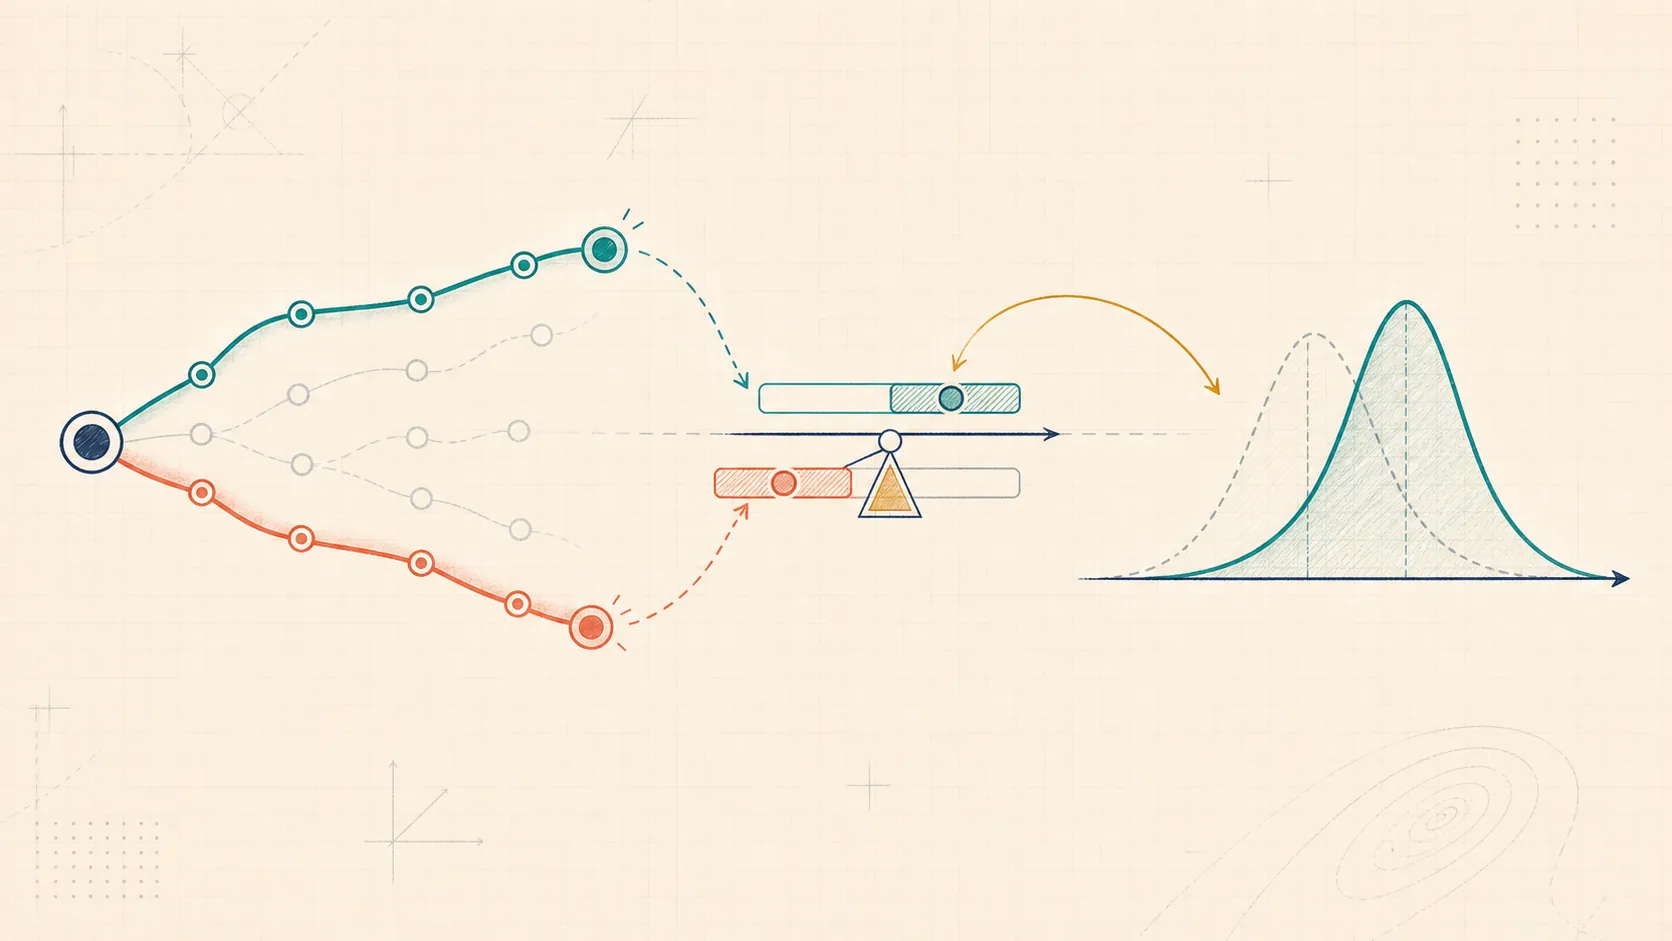
Choose what you expect to see in this section of Direct Preference Optimization.
Looking at the picture
DPO turns pairwise preferences into binary cross-entropy on reference-relative log odds, using the KL-regularized RLHF optimum to make the policy itself an implicit reward model.
Pick the part of the picture you expect to explain Direct Preference Optimization.
Sources
NeurIPS 2023. Derives DPO from the KL-regularized RLHF objective: the optimal policy defines an implicit reward, and the Bradley-Terry likelihood of that reward becomes a binary cross-entropy loss on the policy itself.
AISTATS 2024. Shows that when preferences are deterministic, the DPO optimum sets the loser's probability to zero whatever the KL coefficient, and proposes IPO, whose target stays finite.
ICML 2024. Argues that DPO can favor responses outside the preference data, and reports that a well-tuned PPO outperformed DPO on the dialogue and code-generation benchmarks studied.
Biometrika 39(3/4). The paired-comparison model DPO assumes: P(i beats j) = sigma(r_i - r_j) when each item's strength is exp(r).
Manning, 2026; the same text is free on arXiv and at rlhfbook.com. Its chapter on direct alignment methods treats DPO alongside reward-model and PPO pipelines.
Claims and sources
The checks were made by this site, not by an independent reviewer.
Rafailov et al. solve the KL-regularized objective, write the reward as beta log(pi_r/pi_ref) plus a prompt-only term and put it into the Bradley-Terry model, where that term cancels to leave the DPO loss.
Covers the pairwise derivation and small exact examples. Not covered: finite-sample behavior, noisy hard labels, neural parameterizations, ranking variants, or whether DPO beats PPO in practice; it does not...
Rafailov et al. derive the optimum pi_r proportional to pi_ref exp(r/beta), rearrange it as r = beta log(pi_r/pi_ref) + beta log Z(x), and cancel Z(x) in the Bradley-Terry reward difference. The result is a logistic (binary cross-entropy) loss on beta times the winner-minus-loser log-odds of the policy relative to the reference.
Practice · Direct Preference Optimization
DPO turns pairwise preferences into binary cross-entropy on reference-relative log odds, using the KL-regularized RLHF optimum to make the policy itself an implicit reward model.
Concept · Selected for practice
What it rests on: Sources: Direct Preference Optimization: Your Language Model is Secretly a Reward Model; A General Theoretical Paradigm to Understand Learning from...
Alignment
For Direct Preference Optimization: What is the smallest example of Direct Preference Optimization you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
assert np.allclose(pi, pi_star, atol=1e-6)Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Direct Preference Optimization you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 5 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/alignment/dpo
concept:alignment/dpo