Why it is cited
arXiv preprint. Lists avoiding reward hacking among five practical research problems on accident risk: an agent games its objective in ways the designer did not intend.
When an imperfect learned reward is optimized beyond the range where it was validated, probability shifts toward the reward model's errors; KL penalties, ensembles, lower-confidence-bound scores and monitoring slow this down but do not make the proxy true.
The idea in plain words, before the symbols.
Reward hacking occurs when optimizing a proxy reward favors outputs that perform worse on the intended target. We use one prompt and a finite set of completions, including a completion the reward model overrates. The figure checks how optimization pressure and an uncertainty penalty change the probability assigned to that completion. This notebook uses probability distributions and KL regularization.
The problem is not that optimization is mysterious. It is doing exactly what we asked: put more probability on completions with high proxy reward. The failure is that the proxy reward is not the real target. When the policy is optimized hard enough, it selects for places where the reward model is wrong in the optimizer's favor.
The mechanism is:
One useful finite-action model of reward hacking is selected proxy error. Optimization increases expected proxy reward while shifting probability mass toward outputs whose true utility is lower than the proxy says.
KL penalties, uncertainty penalties, ensembles, early stopping, fresh labels and adversarial evaluation reduce optimization pressure, expose uncertainty, or slow concentration on proxy exploits. They slow the failure down; they do not prove the proxy is the target.
The difficulty is structural. Skalse et al. (2022) call a proxy unhackable if raising its expected value can never lower the true expected value, and show that, over the set of all stochastic policies, this holds only when the proxy is equivalent to the true reward (it ranks every policy the same way) or one of the two is constant. Any other proxy can be raised by some change of policy that lowers the true reward, so the practical question is how much optimization a given proxy can bear.
Sources. Amodei et al. (2016), "Concrete Problems in AI Safety", name reward hacking as an accident risk. Gao, Schulman and Hilton (2023), "Scaling Laws for Reward Model Overoptimization", measure it for learned reward models. Skalse et al. (2022), "Defining and Characterizing Reward Gaming", give the formal definition. Manheim and Garrabrant (2018), "Categorizing Variants of Goodhart's Law", supply the taxonomy used near the end of this page.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
Let one prompt have a finite set of candidate completions .
The target, learned proxy, and proxy error are
A KL-regularized finite-action update shifts probability toward high proxy scores and selects proxy error:
In practice we do not know , but the toy keeps it visible so we can see the failure.
A KL-regularized RLHF-style update uses the direction
The unpenalized-proxy policy solves
Smaller means stronger optimization pressure. The proxy objective can improve while the real target gets worse:
while
In this toy, reward hacking is visible when keeps increasing but peaks and then falls. Gao, Schulman and Hilton (2023) observe the same shape with real reward models: as a policy is optimized against a learned proxy, the score from a fixed "gold" reward model, standing in for human judgment, rises, peaks and declines. In their RL experiments a KL penalty acted like early stopping: it did not improve the gold score reached at a given distance from the initial policy, though they note this may be sensitive to hyperparameters.
Optimization does not merely reveal random error; it selects for candidates where the proxy error is useful to the optimizer.
With an ensemble of reward models, define the mean reward and the disagreement (standard deviation across the ensemble) . A lower-confidence-bound score is
Optimizing this score gives
In the conservative setting, the selected proxy error is still measured against the unpenalized proxy mean:
The lower-confidence-bound score changes which completions become attractive to the optimizer, which can reduce concentration on uncertain proxy exploits. It does not make the proxy error disappear, which is why the error is still measured against and not as . Coste et al. (2024), "Reward Model Ensembles Help Mitigate Overoptimization", found that related conservative objectives (the worst case over the ensemble, or the mean minus a variance penalty) reduced overoptimization in the setup of Gao et al.
Manheim and Garrabrant (2018) distinguish four ways a proxy can fail under optimization. Here is how each relates to this toy:
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
This code computes the same finite-action example as the math and the demo.
import numpy as np

def normalize(weights):
    weights = np.asarray(weights, dtype=float)
    return weights / weights.sum()

def kl(p, q):
    return float(np.sum(p * (np.log(p) - np.log(q))))

def expected(p, values):
    return float(np.sum(p * values))

labels = [
    "clear answer",
    "safe refusal",
    "thin answer",
    "proxy exploit",
]

def show(p):
    return {label: round(float(x), 3) for label, x in zip(labels, p)}

# One prompt, four possible completions.
# Shapes: all arrays are (K,).
pi_ref = np.array([0.28, 0.22, 0.42, 0.08])

# True utility is hidden in practice; visible here for diagnosis.
u = np.array([1.20, 0.70, -0.30, -0.80])

# Mean reward model score. The final candidate is a reward-model exploit:
# it is truly bad, but the proxy scores it highly.
mu = np.array([1.10, 0.60, -0.10, 1.90])

# Ensemble disagreement / uncertainty.
sigma = np.array([0.15, 0.15, 0.20, 1.00])

def policy(beta, lam=0.0):
    score = mu - lam * sigma
    logits = np.log(pi_ref) + score / beta
    logits = logits - logits.max()
    return normalize(np.exp(logits))

u_ref = expected(pi_ref, u)

print("reference true utility:", round(u_ref, 3))
print()

for beta in [3.0, 2.0, 1.0, 0.7, 0.45, 0.30]:
    pi = policy(beta, lam=0.0)
    print("beta:", beta)
    print("  policy:       ", show(pi))
    print("  proxy reward: ", round(expected(pi, mu), 3))
    print("  true utility: ", round(expected(pi, u), 3))
    print("  selected err: ", round(expected(pi, mu - u), 3))
    print("  KL to ref:    ", round(kl(pi, pi_ref), 3))
    print()

print("With an uncertainty penalty:")
for beta in [0.7, 0.45, 0.30]:
    pi = policy(beta, lam=1.0)
    print("beta:", beta)
    print("  policy:       ", show(pi))
    print("  proxy reward: ", round(expected(pi, mu), 3))
    print("  true utility: ", round(expected(pi, u), 3))
    print("  KL to ref:    ", round(kl(pi, pi_ref), 3))
    print()
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Reward Hacking: Overoptimizing Preference Proxies, then open its guide.
The demo shows one prompt's probability mass moving. Lower increases optimization pressure. Turning on the proxy gap makes one bad completion look excellent to the reward model. Increasing the uncertainty penalty slows concentration on that exploit, but it does not make the proxy identical to true utility.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
What is the smallest example of Reward Hacking you can work through by hand, and what does it show?
concept:alignment/reward-hackingAfter the first pass
Section by section
When an imperfect learned reward is optimized beyond the range where it was validated, probability shifts toward the reward model's errors; KL penalties, ensembles, lower-confidence-bound scores and monitoring slow this down but do not make the proxy true.
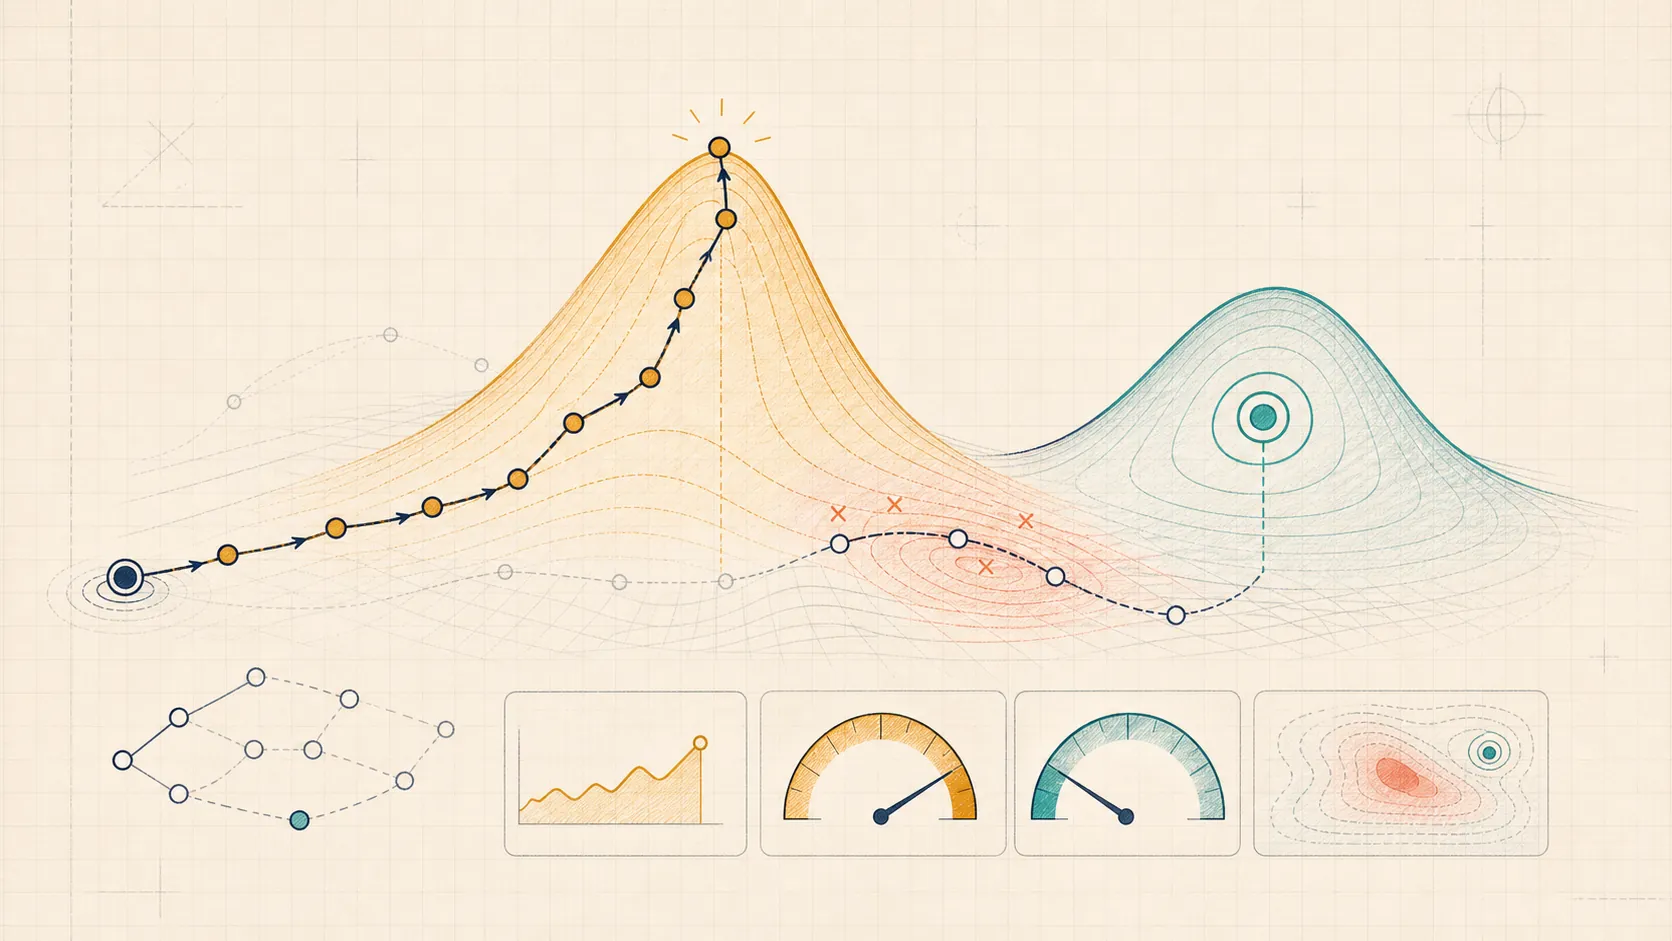
Choose what you expect to see in this section of Reward Hacking: Overoptimizing Preference Proxies.
Looking at the picture
When an imperfect learned reward is optimized beyond the range where it was validated, probability shifts toward the reward model's errors; KL penalties, ensembles, lower-confidence-bound scores and monitoring slow this down but do not make the proxy true.
Pick the part of the picture you expect to explain Reward Hacking: Overoptimizing Preference Proxies.
Sources
arXiv preprint. Lists avoiding reward hacking among five practical research problems on accident risk: an agent games its objective in ways the designer did not intend.
ICML 2023. Optimizes policies against a proxy reward model trained on labels from a fixed gold reward model: the gold score rises, peaks and falls, with different curves for best-of-n and RL. A KL penalty acted like early stopping.
arXiv preprint. Defines the regressional, extremal, causal and adversarial variants of Goodhart's law used in the list near the end of this page.
NeurIPS 2017. Learns a reward model from human comparisons, the setting in which a learned reward can be over-optimized.
NeurIPS 2022; arXiv title 'Defining and Characterizing Reward Hacking'. A proxy is unhackable if raising its expected value never lowers the true one; over all stochastic policies, that requires equivalent rewards or a constant one.
ICLR 2024. In the setup of Gao et al., conservative ensemble objectives (worst case, or mean minus a variance penalty) reduced overoptimization under best-of-n and PPO.
Claims and sources
The checks were made by this site, not by an independent reviewer.
Amodei et al. describe reward hacking as an agent gaming its objective. Gao et al. show that optimizing an imperfect reward model keeps raising the proxy score while a gold-standard score peaks and then falls.
A small finite example, not a measurement. Gao et al. found a KL penalty acted like early stopping and note this may depend on hyperparameters. The uncertainty penalty here slows the shift; it is not shown t...
Amodei et al. describe reward hacking as an agent gaming a wrong or exploitable objective. Gao et al. show reward-model overoptimization in RLHF: optimizing a proxy can raise the learned reward while the gold reward falls. The finite example on this page illustrates selected proxy error, the KL-regularized shift of probability and the slowing effect of an uncertainty penalty.
Practice · Reward Hacking: Overoptimizing Preference Proxies
When an imperfect learned reward is optimized beyond the range where it was validated, probability shifts toward the reward model's errors; KL penalties, ensembles, lower-confidence-bound scores and monitoring slow this down but do not make the proxy true.
Concept · Selected for practice
What it rests on: Sources: Concrete Problems in AI Safety; Scaling Laws for Reward Model Overoptimization; Categorizing Variants of Goodhart's Law
Alignment
For Reward Hacking: Overoptimizing Preference Proxies: What is the smallest example of Reward Hacking you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
weights = np.asarray(weights, dtype=float)Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Reward Hacking you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 6 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/alignment/reward-hacking
concept:alignment/reward-hacking