Why it is cited
ICLR 2024. Trains process reward models on PRM800K, human labels for each step of model-written solutions to MATH problems, and finds they select correct solutions more reliably than outcome reward models in best-of-N search.
A process reward model scores intermediate reasoning steps rather than only the final answer. These learned scores can guide reranking and search, but remain proxies for correctness.
The idea in plain words, before the symbols.
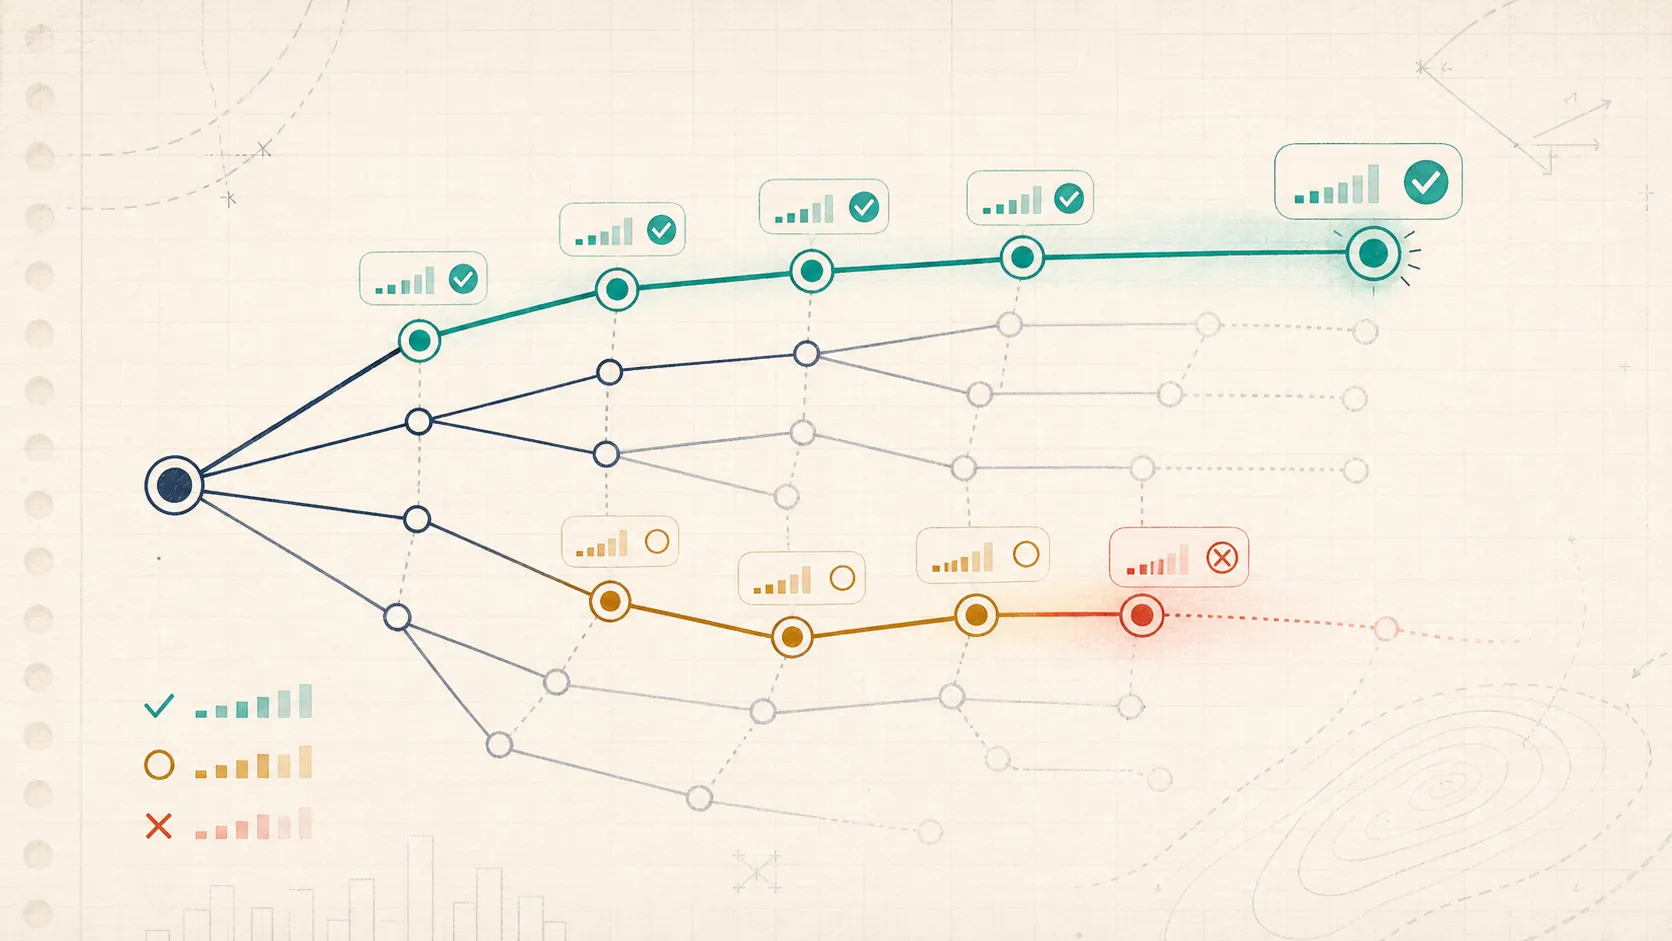
A process reward model scores each intermediate reasoning step, while an outcome reward model gives one score for the completed solution. We compare complete reasoning traces that differ in their final-answer correctness and local step validity. The figure checks how outcome scoring, process scoring, and verifier errors change which trace receives the most probability. You will need the sigmoid, cross-entropy, and softmax over a finite set of choices.
A process reward model asks a local question at every step: given the prompt and the reasoning prefix so far, is this next step valid?
That changes the shape of feedback. Instead of treating a whole solution as one indivisible completion, the verifier sees a path through intermediate states. A lucky final answer with broken reasoning can receive high outcome reward and low process reward. A trace with one early algebra mistake can be rejected before the mistake compounds.
Uesato et al. (2022) measured this on grade-school math word problems: outcome supervision matched process supervision on final-answer error, but reducing reasoning errors among solutions whose final answer was correct required process supervision, or a learned reward model that imitates it.
The important caveat is that a process reward model is still a learned proxy. It can localize errors better than terminal-only feedback, but its step labels can be ambiguous, expensive, domain-limited, or wrong. PRMs do not solve reward hacking; they move the proxy from the leaf of the reasoning tree onto the edges.
Sources. Cobbe et al. (2021), "Training Verifiers to Solve Math Word Problems", train outcome verifiers that rerank sampled solutions. Uesato et al. (2022), "Solving math word problems with process- and outcome-based feedback", compare outcome and process supervision. Lightman et al. (2024), "Let's Verify Step by Step", train process reward models on the PRM800K step labels. Snell et al. (2025), "Scaling LLM Test-Time Compute Optimally can be More Effective than Scaling Model Parameters", use process reward models to guide search at inference time.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
Fix one prompt . In the simplified binary notation used here, a process reward model sees a reasoning prefix and a candidate next step, then predicts whether that step is locally correct. Lightman et al.'s PRM800K labels include positive, negative, and neutral ratings; here we collapse them into correct vs. not correct to show how the verifier works.
For labeled steps , the binary verifier can be trained with cross-entropy:
A complete solution is a terminal trace
Outcome supervision observes only a terminal label
For a terminal trace, one simple additive score is the sum of step logits:
Other aggregations, such as mean step probability, product of step probabilities, or minimum step score, are design choices rather than a universal PRM definition. Lightman et al. define the solution score as the probability, under the PRM, that every step is correct, implemented as the product of per-step predictions with neutral labels counted as positive. The key definition is local verification of steps.
Separate from Lightman et al.'s best-of-N evaluation, this page also shows a finite KL-style RLHF bridge. A KL-regularized trajectory update is
This is the same finite-action probability-shaping pattern as RLHF, but the learned reward decomposes over reasoning steps. Smaller pushes harder on the verifier score. If the step verifier is wrong, optimization can still select verifier error.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
This code uses four fixed traces for the equation . The outcome verifier prefers a trace with the correct final answer but invalid reasoning. The accurate process verifier prefers the clean trace. If we inject a false-positive process error, the process verifier can be fooled too.
import math
import numpy as np

def logit(p):
    p = min(max(p, 1e-6), 1 - 1e-6)
    return math.log(p / (1 - p))

def policy(scores, ref, beta=0.7):
    logits = np.log(ref) + np.asarray(scores) / beta
    logits = logits - logits.max()
    weights = np.exp(logits)
    return weights / weights.sum()

traces = ["clean", "lucky_final", "slip", "wrong"]
ref = np.array([0.30, 0.22, 0.28, 0.20])
outcome_p = np.array([0.86, 0.92, 0.16, 0.12])
step_p = [
    [0.93, 0.91],
    [0.16, 0.24],
    [0.93, 0.22],
    [0.20, 0.35],
]

def process_scores(step_probs):
    return [sum(logit(p) for p in probs) for probs in step_probs]

outcome_winner = traces[int(policy([logit(p) for p in outcome_p], ref).argmax())]
process_winner = traces[int(policy(process_scores(step_p), ref).argmax())]

hacked_steps = [list(probs) for probs in step_p]
hacked_steps[1] = [0.98, 0.97]
hacked_winner = traces[int(policy(process_scores(hacked_steps), ref).argmax())]

print(outcome_winner, process_winner, hacked_winner)
assert outcome_winner == "lucky_final"
assert process_winner == "clean"
assert hacked_winner == "lucky_final"
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Process Reward Models: Step-Level Verifiers for Reasoning, then open its guide.
In the demo, switch between outcome-only scoring and process scoring, change the process aggregation, inject verifier errors, and lower to increase optimization pressure. Watch how probability mass moves across complete traces, and whether the selected trace has a correct final answer, valid local steps, or merely a high verifier score.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
What is the smallest example of Process Reward Models you can work through by hand, and what does it show?
concept:alignment/process-reward-modelsAfter the first pass
Section by section
A process reward model scores intermediate reasoning steps rather than only the final answer. These learned scores can guide reranking and search, but remain proxies for correctness.
Choose what you expect to see in this section of Process Reward Models: Step-Level Verifiers for Reasoning.
Looking at the picture
A process reward model scores intermediate reasoning steps rather than only the final answer. These learned scores can guide reranking and search, but remain proxies for correctness.
Pick the part of the picture you expect to explain Process Reward Models: Step-Level Verifiers for Reasoning.
Sources
ICLR 2024. Trains process reward models on PRM800K, human labels for each step of model-written solutions to MATH problems, and finds they select correct solutions more reliably than outcome reward models in best-of-N search.
arXiv preprint. On GSM8K, outcome supervision matched process supervision on final-answer error, but process supervision, or a reward model that imitates it, was needed to cut reasoning errors among solutions with correct final answers.
arXiv preprint. Introduces GSM8K and trains outcome verifiers that judge whole solutions by their final answer, then reranks many sampled solutions with them.
ICLR 2025, under a shorter title. Uses process reward models as verifiers for best-of-N and beam search at inference time, and finds that the best search strategy depends on how hard the prompt is.
Claims and sources
The checks were made by this site, not by an independent reviewer.
Lightman et al. contrast outcome reward models, trained on final results, with process reward models trained on a label for each step; they combine the step scores to rank whole solutions in best-of-N search.
The binary label and cross-entropy loss simplify Lightman et al.'s positive, negative and neutral labels. Not covered: the best way to combine step scores, calibration, training a generator against a PRM, ga...
Lightman et al. train process reward models on step-level labels and evaluate them by best-of-N selection of the highest-ranked generated solution. The binary cross-entropy notation here simplifies their positive, negative and neutral labels. Their examples of reward-model mistakes and false positives support the point that a PRM is still a proxy. The KL reweighting on this page is not part of the checked claim.
Practice · Process Reward Models: Step-Level Verifiers for Reasoning
A process reward model scores intermediate reasoning steps rather than only the final answer. These learned scores can guide reranking and search, but remain proxies for correctness.
Concept · Selected for practice
What it rests on: Sources: Let's Verify Step by Step; Solving math word problems with process- and outcome-based feedback; Training Verifiers to Solve Math Word Prob...
Alignment
For Process Reward Models: Step-Level Verifiers for Reasoning: What is the smallest example of Process Reward Models you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
assert outcome_winner == "lucky_final"Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Process Reward Models you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 4 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/alignment/process-reward-models
concept:alignment/process-reward-models