Why it is cited
Neurocomputing 568, 127063 (arXiv 2021). Rotary position embedding, whose query-key product depends on the relative offset; not a RoPE-scaling method.
How models handle long inputs: keeping positions within the range seen in training (RoPE scaling), sliding windows, and cutting KV-cache memory with GQA, paging, quantization and compression.
Storage, visibility and position are different questions. Choose one to inspect; each view states what it leaves untested.
Start with eight tokens → A separate worked example, in single-token units. The demos below also cover grouped key–value heads and larger memory settings.
The idea in plain words, before the symbols.
Running a model on a long input raises two separate problems: the model must handle token positions it never saw in training, and it must store and read the keys and values of every earlier token. We compare the techniques that address each. The code counts KV-cache bytes and the attention work a sliding window saves. Fitting a longer context does not show that the model can find and use the evidence it contains.
The two problems are:
The two problems have separate remedies. RoPE scaling methods (position interpolation, YaRN, LongRoPE) keep the rotation angles of distant positions inside the range seen in training. KV-cache techniques (GQA/MQA, paging, quantization, eviction) reduce how many bytes must be stored and read per token.
A third question sits on top of both: does the model find and use the evidence it needs? A cache that fits and positions that are familiar do not answer it. Retrieving one planted fact is the easiest case; harder tests move the evidence around, add distractors and need several facts at once (Hsieh et al., 2024; Liu et al., 2024).
Which resource runs out depends on the phase. Processing a long prompt (prefill) handles all its tokens in parallel and is usually limited by arithmetic. Generating the answer (decode) produces one token per step, and each step must read the model's weights and the whole KV cache from memory, so at small batch sizes it is limited by memory bandwidth, and the longer the context, the more of that traffic is cache (Pope et al., 2023, §2).
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
If each token attends only to itself and the tokens before it, a window of keys (Beltagy et al., 2020), then attention compute is closer to instead of . One way to express this is with a mask:
and:
Across a batch of sequences and layers, storing keys and values for tokens costs roughly:
Here is the number of key/value heads per layer and their width. This grows linearly in . At long context and large batch it can exceed the memory taken by the model's weights: with the settings in the code below (80 layers, 8 KV heads of width 128, batch 8, 2 bytes per value), it reaches about 344 GB at 131,072 tokens.
"Supports 131,072 tokens" can mean three things, and each needs its own evidence.
These are not the only constraints; prefill compute, decode bandwidth and scheduling sit beside them. The practice section works the first claim exactly and matches the other two to their evidence.
RoPE encodes position by rotating queries and keys. At positions far beyond training, those rotations reach angles the model never saw, especially in the slowly rotating (low-frequency) pairs, which never completed a full turn during training. RoPE scaling methods change the map from position to angle so that long inputs produce familiar angles while short-range detail is preserved. Position interpolation (Chen et al., 2023) replaces by for every pair, where is the training context length and the extended one; YaRN (Peng et al., 2024) rescales the slow pairs more than the fast ones.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
import numpy as np

def kv_gb(T, L, Hkv, d_head, B=1, bytes_per_elem=2):
    elems = B * L * T * Hkv * d_head * 2  # K and V
    return elems * bytes_per_elem / 1e9

L, Hkv, d_head, B = 80, 8, 128, 8  # example: 80 layers, GQA with 8 KV heads, fp16
for T in [2048, 8192, 32768, 131072]:
    print("T=", T, "KV~", round(kv_gb(T, L, Hkv, d_head, B), 2), "GB")

def attn_work(T, W, d):
    # crude: per token ~ 2 * W * d multiply-adds (QK + weights*V)
    return T * W * d * 2

T, d = 131072, 128
full = attn_work(T, T, d)
for W in [128, 512, 2048, T]:
    print("window=", W, "relative attention work:", round(attn_work(T, W, d) / full, 6))
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Long Context Engineering: RoPE Scaling, KV Compression & Memory Optimization, then open its guide.
Use the figures to connect each formula to what a serving system experiences:
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Work out the cache for a 131,072-token request exactly, then match each long-context claim to the evidence it needs.
What is the smallest example of Long Context Engineering you can work through by hand, and what does it show?
concept:attention-transformers/long-contextEquation, code and demo
The cache stores keys and values for every layer, token, KV head, and head dimension. With batch, layers, KV heads, head size, and bytes fixed, memory grows linearly with context length T.
\mathrm{Mem}_{KV} \approx B\cdot L\cdot T\cdot H_{kv}\cdot d_{\mathrm{head}}\cdot 2 \cdot \mathrm{bytes}.CodeCode example 1elems = B * L * T * Hkv * d_head * 2 # K and VDemoDemo sectionKV memory estimate updates when context length, layers, heads, width, batch, or precision changes.After the first pass
Section by section
How models handle long inputs: keeping positions within the range seen in training (RoPE scaling), sliding windows, and cutting KV-cache memory with GQA, paging, quantization and compression.
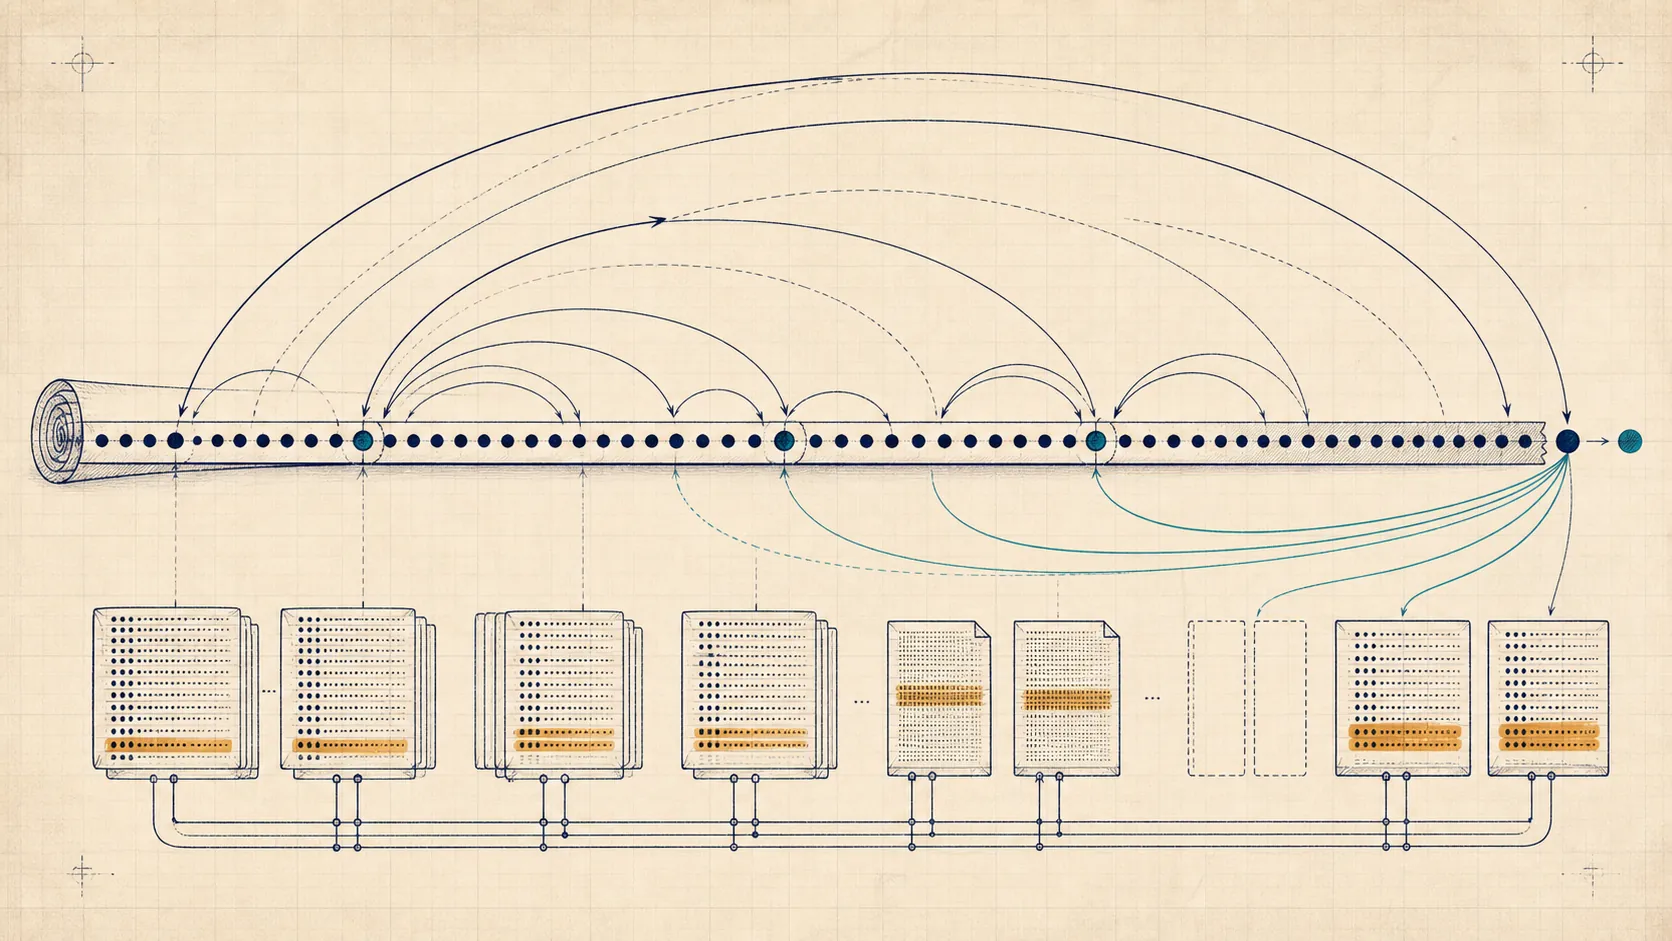
Choose what you expect to see in this section of Long Context Engineering: RoPE Scaling, KV Compression & Memory Optimization.
Looking at the picture
How models handle long inputs: keeping positions within the range seen in training (RoPE scaling), sliding windows, and cutting KV-cache memory with GQA, paging, quantization and compression.
Pick the part of the picture you expect to explain Long Context Engineering: RoPE Scaling, KV Compression & Memory Optimization.
Sources
Neurocomputing 568, 127063 (arXiv 2021). Rotary position embedding, whose query-key product depends on the relative offset; not a RoPE-scaling method.
ICLR 2022. Treats extrapolation to inputs longer than in training as a problem of how position is represented, and proposes ALiBi, an alternative to RoPE.
SOSP 2023. Treats serving long and many sequences as a KV-cache memory-management problem and allocates the cache in fixed-size pages.
arXiv preprint. Sliding-window attention, in which each token attends to a fixed-size window of nearby tokens, so cost grows linearly with length.
arXiv preprint. Scales position indices of a RoPE model down into the trained range, then fine-tunes briefly.
ICLR 2024. Interpolates slow rotary frequencies more than fast ones and rescales attention to extend RoPE models' context.
MLSys 2023. Section 2 separates prefill from decode and shows that each decode step reloads weights and the KV cache, which can exceed the weights in size.
COLM 2024. Adds multi-fact retrieval, tracing and aggregation to the single-fact test; models near-perfect on that test lose accuracy as inputs grow.
Claims and sources
The checks were made by this site, not by an independent reviewer.
RoFormer grounds the rotary relative-position mechanism; ALiBi directly frames train-short/test-long length extrapolation as a position-representation problem; PagedAttention directly frames high-throughput...
Checks two long-context constraints, not every bottleneck; RoFormer is not a RoPE-scaling recipe, ALiBi is not RoPE, and this page's code and figures are small illustrations, not production guarantees.
RoFormer supports rotary relative-position mechanics; ALiBi supports train-short/test-long extrapolation as a position-representation issue; PagedAttention supports KV-cache memory as a serving bottleneck. The code and figures on this page are small illustrations of KV sizing and rotation angles, not evidence about real serving systems.
Kwon et al. treat the cache as a memory problem, Chen et al. change how positions are mapped and evaluate the result, and Hsieh et al. test whether models find and use evidence beyond a single planted fact.
The 131,072-token request and its 16 GiB cache are an ideal count chosen for round numbers, not a measurement. Prefill, bandwidth and scheduling are further constraints.
The RULER abstract and venue were checked for the single-fact finding, and Lost in the Middle (linked in the text) for the position finding. The 2^34-byte cache and its halving at four key–value heads were recomputed independently.
Practice · Long Context Engineering: RoPE Scaling, KV Compression & Memory Optimization
How models handle long inputs: keeping positions within the range seen in training (RoPE scaling), sliding windows, and cutting KV-cache memory with GQA, paging, quantization and compression.
Concept · Selected for practice
What it rests on: Sources: RoFormer: Enhanced Transformer with Rotary Position Embedding; Train Short, Test Long: Attention with Linear Biases Enables Input Length E...
Attention & Transformers
For Long Context Engineering: RoPE Scaling, KV Compression & Memory Optimization: What is the smallest example of Long Context Engineering you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
elems = B * L * T * Hkv * d_head * 2 # K and VYour question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Long Context Engineering you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 8 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/attention-transformers/long-context
concept:attention-transformers/long-context