Why it is cited
A fast model drafts γ tokens, the target scores every draft prefix in one pass, and accept/reject sampling with a residual keeps the target's distribution; §3 gives tokens per pass, (1 − α^(γ+1))/(1 − α), and the speedup (ICML 2023).
Draft several tokens with a fast model, score all the draft prefixes with the target model in one parallel pass, then use modified rejection sampling so the output distribution matches the target model's.
The idea in plain words, before the symbols.
Speculative decoding has a large model accept several tokens per forward pass while still sampling from its own distribution. We compare draft length, acceptance rate, and the mismatch between draft and target distributions, and work one example of the predicted speedup. Ordinary decoding needs one pass of the large model per token, and each pass must wait for the previous token. For a large model at small batch sizes, each pass is limited by reading the weights from memory, not by arithmetic, so scoring several positions in one pass costs about as much time as scoring one (see the LLM serving page).
Speculative decoding uses that spare capacity by splitting the work into two roles (Leviathan et al., 2023; Chen et al., 2023):
In the full algorithm, the target produces next-token distributions: one for the current prefix, one after each draft prefix, and an extra distribution that can supply a new target token if every draft token is accepted. If draft tokens pass the target/draft probability-ratio checks, you accept a prefix of the draft and "skip ahead" in the sequence. If one fails, you reject at the first failed token and replace it with a sample from a residual distribution, so the target distribution is preserved. The method is lossless in this sense: the generated text has exactly the distribution you would get by sampling from the target model alone, up to floating-point rounding.
The gain is in the system, not the model: fewer sequential passes of the large model, with the same output distribution.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
Let be the draft distribution at position and be the target distribution. This page follows Leviathan et al.'s notation, where is the target and is the draft; Chen et al. use the opposite symbols. If the draft proposes token , it is accepted with probability:
If a proposed token is rejected, you sample from a residual distribution that corrects for what the draft already "used up":
This rejection-and-residual mechanism is what makes the method lossless: accepted tokens come from but are filtered to match , and the residual sample at a rejected position supplies exactly the probability the filter removed.
Averaged over the draft's proposals, a position is accepted with probability , which is 1 when the two distributions agree and 0 when they do not overlap (Leviathan et al., 2023, Theorem 3.5). Let be the average of over positions. Leviathan et al. make the simplifying assumption that acceptances are independent, each with probability . Then one target pass with draft tokens produces on average tokens.
This counts the accepted prefix plus one token from the target: either the residual sample at the first rejection or a new token when all are accepted. The count ranges from 1 (the first draft token is rejected) to .
Each round also runs the draft model times. If one draft pass takes times as long as one target pass, the expected wall-clock speedup is (Leviathan et al., 2023, Theorem 3.8). For example, with , and , a target pass yields about 3.36 tokens and the speedup is about 2.8×. A longer draft helps only while is high; when the draft is often wrong, the extra draft passes cost more than the extra accepted tokens save. The formula also assumes the target can score positions in about the time of one, which holds when decoding is limited by memory bandwidth, not when the hardware is already busy with large batches.
Take four tokens A, B, C, D with the target and draft from the code below, and . A proposed token is kept with probability , which is . The probability that each token is proposed and kept is :
A rejection therefore happens with probability , and the residual it samples from is
Rejections add , and kept plus repaired is . The residual is a distribution over the tokens the draft under-proposed, A and D, in proportion to their shortfalls, and ; scaled by the rejection probability , it adds back exactly each shortfall. When every proposal is kept and the residual is never sampled; when and differ, however slightly, it must be normalized and used, or the output loses that probability.
The token count above assumes every position is accepted independently with the same . Without that assumption, let be the probability that draft position is accepted given that positions were, and let be the number of draft tokens accepted. By the chain rule,
With and , the survival probabilities are , so and one target pass yields tokens on average. Reverse the order to : the mean acceptance is the same , but the survival probabilities are and . A rejection ends the draft, so the early positions count most, and the mean acceptance alone does not determine the expected length; independent acceptance at gives a third value, .
These are tokens per target pass, not speedups. The speedup also depends on the draft's cost and on how long the target takes to score the draft, as above.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
First check the one-token correction. Even though some samples come from the draft model, the accepted-or-resampled output should match the target distribution. Then simulate the length of the accepted prefix, which is where the speedup comes from, and compare it with the formula , the expected number of accepted draft tokens (one fewer than the tokens per target pass).
import numpy as np

target_p = np.array([0.45, 0.30, 0.15, 0.10])
draft_q = np.array([0.30, 0.45, 0.20, 0.05])
rng = np.random.default_rng(0)

def residual_distribution(p, q):
    repair_mass = np.maximum(0.0, p - q)
    return repair_mass / repair_mass.sum()

def speculative_one_token(p, q):
    draft = rng.choice(len(q), p=q)
    accept_prob = min(1.0, p[draft] / q[draft])
    if rng.random() < accept_prob:
        return draft, True
    repair = rng.choice(len(p), p=residual_distribution(p, q))
    return repair, False

samples = np.zeros_like(target_p)
accepted = 0
for _ in range(200_000):
    token, was_accepted = speculative_one_token(target_p, draft_q)
    samples[token] += 1
    accepted += int(was_accepted)

print("target distribution:   ", np.round(target_p, 3))
print("speculative samples:   ", np.round(samples / samples.sum(), 3))
print("draft-token acceptance:", round(accepted / samples.sum(), 3))

def expected_accepted(alpha, k):
    # Expected length of consecutive acceptances (prefix), capped at k.
    if alpha == 1.0:
        return float(k)
    return alpha * (1.0 - alpha**k) / (1.0 - alpha)

def simulate(alpha, k, trials=50000, seed=0):
    rng = np.random.RandomState(seed)
    total = 0
    for _ in range(trials):
        a = 0
        for _ in range(k):
            if rng.rand() < alpha:
                a += 1
            else:
                break
        total += a
    return total / trials

for alpha in [0.3, 0.6, 0.85]:
    for k in [2, 4, 8]:
        theo = expected_accepted(alpha, k)
        mc = simulate(alpha, k)
        print(f"alpha={alpha:.2f} k={k:>2}  E[accepted] theo={theo:.3f}  mc={mc:.3f}")
This standard-library Python code does the worked examples above without sampling: the kept and repaired mass for one position, and the survival of a four-token draft.
def repair(p, q):
    kept = [min(pi, qi) for pi, qi in zip(p, q)]
    shortfall = [max(0.0, pi - qi) for pi, qi in zip(p, q)]
    z = sum(shortfall)                       # probability of a rejection
    residual = [s / z for s in shortfall] if z > 0 else [0.0] * len(p)
    return kept, z, residual, [k + z * r for k, r in zip(kept, residual)]

def survival(a):
    s, running = [], 1.0
    for ai in a:
        running *= ai                        # P(L >= i) = a_1 ... a_i
        s.append(running)
    return s, sum(s)                         # E[L] is the sum of the survival probabilities

kept, z, residual, output = repair([0.45, 0.30, 0.15, 0.10], [0.30, 0.45, 0.20, 0.05])
print("kept:", kept, "rejection:", round(z, 12), "residual:", [round(r, 12) for r in residual])
assert all(abs(o - t) < 1e-12 for o, t in zip(output, [0.45, 0.30, 0.15, 0.10]))

# A tiny positive residual is still normalized and used.
output = repair([0.5, 0.5], [0.5000000005, 0.4999999995])[3]
assert abs(sum(output) - 1) < 1e-15

for a in ([0.80, 0.75, 0.50, 0.25], [0.25, 0.50, 0.75, 0.80]):
    s, expected = survival(a)
    print(a, "P(L >= i):", [round(x, 6) for x in s], "E[L]:", round(expected, 6))
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in Speculative Decoding: Lossless Multi-Token Generation, then open its guide.
Use the demo to see how the acceptance rate, the draft length and the mismatch between the two distributions affect the expected speedup, and why verification is nearly free only if the target model can score the whole draft in about the time of one step. The practice after the demo works the two calculations above by hand: where the rejected probability goes, and how far a draft survives.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Follow kept and rejected probability until they rebuild the target, then work out how far a four-token draft survives and reverse its order.
What is the smallest example of Speculative Decoding you can work through by hand, and what does it show?
concept:llm-systems/speculative-decodingAfter the first pass
Section by section
Draft several tokens with a fast model, score all the draft prefixes with the target model in one parallel pass, then use modified rejection sampling so the output distribution matches the target model's.
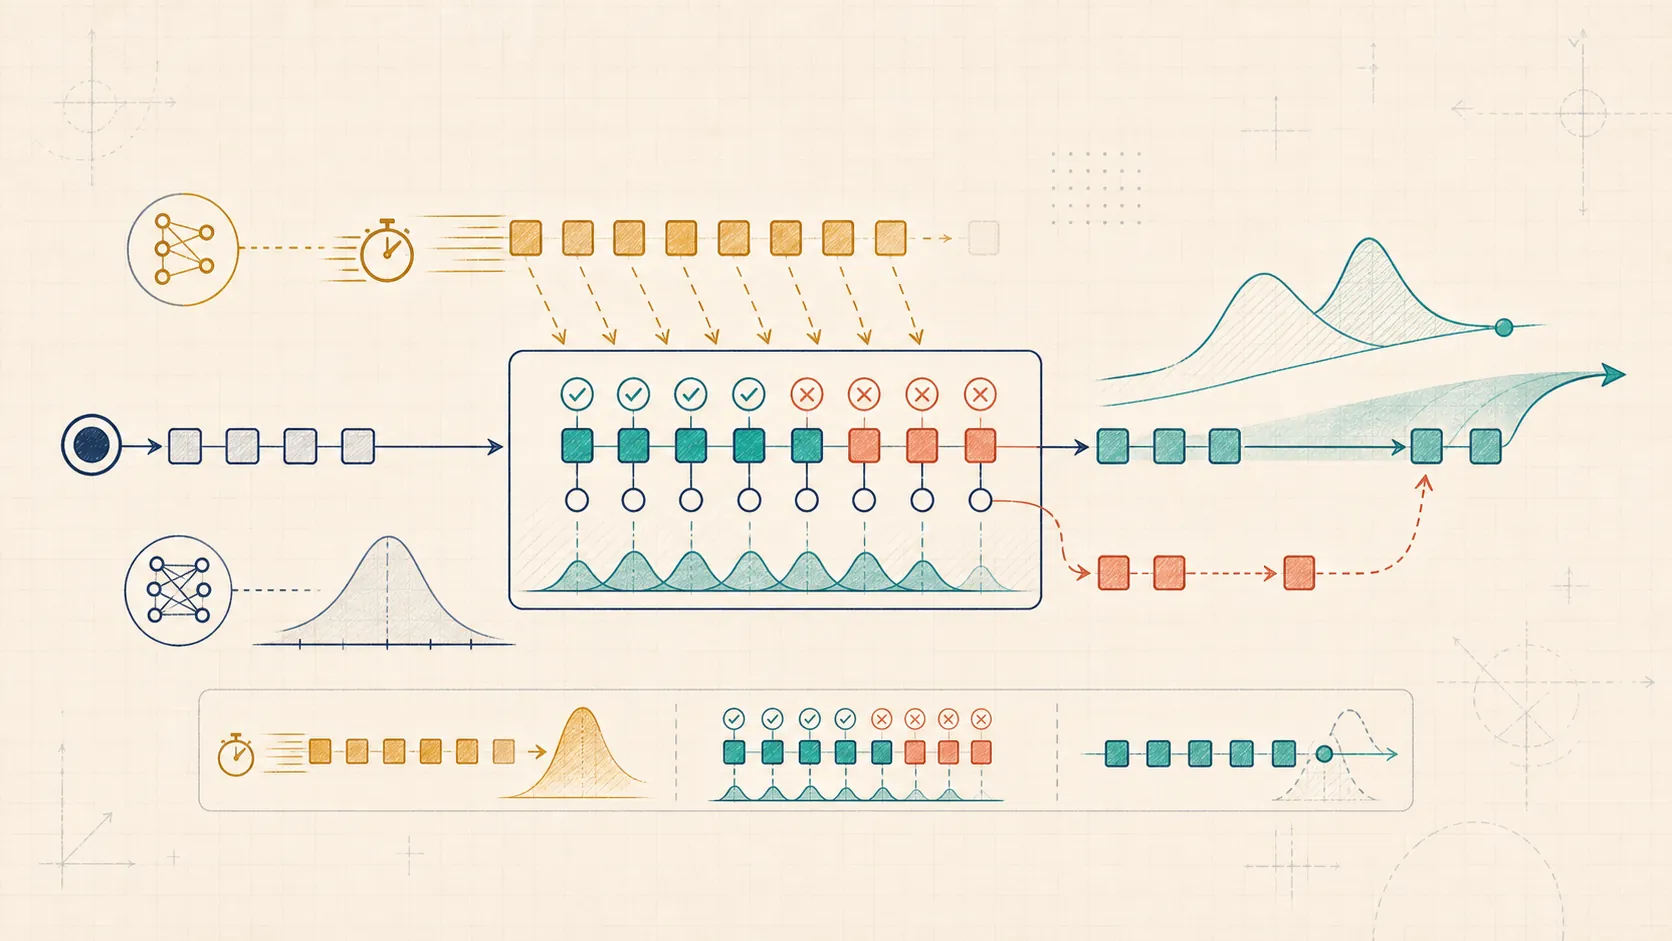
Choose what you expect to see in this section of Speculative Decoding: Lossless Multi-Token Generation.
Looking at the picture
Draft several tokens with a fast model, score all the draft prefixes with the target model in one parallel pass, then use modified rejection sampling so the output distribution matches the target model's.
Pick the part of the picture you expect to explain Speculative Decoding: Lossless Multi-Token Generation.
Sources
A fast model drafts γ tokens, the target scores every draft prefix in one pass, and accept/reject sampling with a residual keeps the target's distribution; §3 gives tokens per pass, (1 − α^(γ+1))/(1 − α), and the speedup (ICML 2023).
Independently proposes the same draft-then-verify scheme with modified rejection sampling, and reports a 2–2.5× decoding speedup for the 70-billion-parameter Chinchilla model in a distributed setup (arXiv preprint).
Claims and sources
The checks were made by this site, not by an independent reviewer.
Leviathan et al. define γ draft tokens from a faster approximation model, parallel target scoring of the draft prefixes, accept/reject filtering and residual sampling from norm(max(0, p − q)), and prove that...
The guarantee is about the output distribution, exact up to floating-point arithmetic, as Chen et al. note. It is not a latency guarantee: the speedup depends on the acceptance rate and the draft's cost. The...
Leviathan et al. (2023) support drafting γ tokens, parallel target scoring of the draft prefixes, accept/reject filtering, residual sampling from norm(max(0, p − q)), and a proof that the output follows the target distribution. Chen et al. (2023) independently support K-token drafts, parallel scoring and modified rejection sampling, with the guarantee qualified by hardware numerics and with p and q swapped. The page's math follows Leviathan et al.'s notation.
Practice · Speculative Decoding: Lossless Multi-Token Generation
Draft several tokens with a fast model, score all the draft prefixes with the target model in one parallel pass, then use modified rejection sampling so the output distribution matches the target model's.
Concept · Selected for practice
What it rests on: Sources: Fast Inference from Transformers via Speculative Decoding; Accelerating Large Language Model Decoding with Speculative Sampling
LLM Systems
For Speculative Decoding: Lossless Multi-Token Generation: What is the smallest example of Speculative Decoding you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
assert all(abs(o - t) < 1e-12 for o, t in zip(output, [0.45, 0.30, 0.15, 0.10]))Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of Speculative Decoding you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 2 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/llm-systems/speculative-decoding
concept:llm-systems/speculative-decoding