Why it is cited
NeurIPS 2022. Tiling between GPU main memory (HBM) and on-chip SRAM, with running softmax statistics, gives exact attention without writing the full N × N matrix (T × T here) to HBM.
Exact attention computed tile by tile with a running softmax, so the full T × T matrix is never written to GPU main memory; in the paper's benchmarks the reduced memory traffic made attention faster.
The idea in plain words, before the symbols.
FlashAttention computes attention in tiles, keeping a running softmax so that the full score matrix need not be written to GPU main memory. We follow one masked attention calculation through a conventional schedule and a tiled schedule. The code checks that they compute the same result, while the cost comparison separates stored bytes, transferred bytes, and arithmetic. You will need matrix multiplication and softmax.
Standard attention takes three steps:
The trouble is the matrix in steps 1 and 2. It is large, and writing it to the GPU's main memory (HBM) and reading it back is slow. Several of these steps, the softmax for example, are memory-bandwidth bound: their time is set by reads and writes, not by arithmetic, so for long sequences the traffic of that matrix dominates (Dao et al., 2022, §2.2).
FlashAttention splits the work into tiles small enough to stay in fast on-chip memory (SRAM), and computes the softmax as a running calculation, so the full matrix is never stored.
To separate stored bytes, transferred bytes and arithmetic, follow one masked calculation through two schedules. A reported GPU profile then supplies a different kind of evidence: elapsed time under its own conditions.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Definitions, assumptions and the derivation.
For one head, with :
The attention weights matrix is . If you store it explicitly, memory scales like .
For a single row of scores , the softmax uses:
You can compute this in blocks without ever storing all scores at once by keeping a running maximum and a running normalizer (Milakov & Gimelshein, 2018).
For a block of scores with:
you can merge block statistics with the running state via:
At the end, the attention output for that row is:
This is the core idea: you can compute without ever storing all of .
The optional schedule investigation uses a separate four-token, one-head example, not the size controls or the six-score row above. Its each have shape , with tokens and features. The causal mask allows key for query exactly when . The maximum and the normalizing sum include only allowed keys. A row with no allowed key has no distribution, so it is rejected. Allowing all keys changes the question; changing the tile width must leave the answer unchanged for the same mask and arrays.
Both schedules use the scaled scores and weighted average above. The materialized schedule writes all scores to a slow array store, overwrites them with probabilities, then reads those probabilities to form the output. The tiled schedule holds a query tile and its running numerator, maximum and sum in a fast scratchpad while visiting key/value tiles, and writes only the final output back. Here the query tiles form the outer loop; this simplified schedule is not Algorithm 1 of the paper, whose outer loop runs over key/value blocks.
Three costs answer different questions. Arithmetic counts executed scalar additions, subtractions, multiplications and divisions. Traffic counts numeric words read or written between the slow store and the scratchpad, including repeated reads. Peak live storage counts allocated words that exist at the same time: inputs, output, score/weight buffers, running statistics and workspace. Storing less need not mean fewer transfers, fewer operations or less time.
Let count allowed query/key pairs, be the query/key tile width, and count active query-row/key-tile pairs: pairs of one query row and one key tile that contain at least one allowed key. For these two schedules, total traffic in words is
For the materialized schedule, reads are : queries, keys loaded again for every query, the score and probability rows, and the allowed value rows. Writes are : scores, probabilities and output. For the tiled schedule, reading queries and writing the output contribute , and each query tile reads all keys and values. This schedule loads key/value tiles even when some or all of their pairs are masked; skipping those loads would be a different schedule with different counts.
All arrays sit in slow storage from the start, including the not-yet-filled output. They occupy words; only the materialized schedule adds a buffer, reused in place for scores and then probabilities. The inputs already exist when counting begins, and reserving output or score storage is not counted as writing. The materialized schedule's largest scratchpad use holds one probability row, one value row, one output row and six scalar workspace words: . For a tiled step with query rows and key rows, the scratchpad holds
Partial tiles use their actual ; the peak is the largest of these. The six
scalar slots are reused for dot-product sums, scalar products, old and new
maxima, the rescaling factor and shifted scores. Built-in operations such as
exp count as single steps, and their own internal workspace is not counted.
In both schedules, constants, indices, instructions, caches, allocator metadata
and the step-by-step display are outside the count. Eight bytes per number is a
convention chosen for this example, not a measurement of browser memory or of
the paper's precision. The scratchpad holds 32 words. Query and key tiles four
tokens wide would need 62 words, so the code refuses that setting with a
capacity error rather than spill data it does not count.
The mask is treated as control logic: no mask array is stored or transferred. The Python lists of true/false values show the rule for inspection; an implementation that loads a stored mask would need extra cost entries.
Each dot product starts at zero, counts multiplications and additions, then one multiplication by the precomputed . Exponentials and maximum comparisons are counted separately rather than converted into a FLOP count. Mask tests and indexing are not counted. The materialized arithmetic total is . The tiled total is : the extra terms come from rescaling the running state and from dividing the final numerator. On a row's first active tile the rescaling factor is set to zero, so no exponential of is evaluated. A tile-row with no allowed key leaves the running state unchanged.
The first active tile still performs the multiplications by that zero factor. Every later active tile computes its rescaling factor once, even when the maximum does not change. Sums start at zero, and each allowed weight is added to the rescaled running sum. Maxima start at and are compared with every allowed score; the tiled schedule also compares the old and new block maxima for each active tile-row. The maximum-comparison counts are therefore and , and the exponential counts and . Starting each maximum at the first score instead would give the same answer with slightly fewer operations.
The running numerator is the sum of value vectors weighted by over the allowed keys seen so far, and the running is the sum of those same weights. Rescaling both whenever changes keeps them measured against the current maximum; the numerator is divided by only at the end. The two schedules agree to within , not bit for bit.
For the causal example, ; at , . The materialized and tiled schedules use 150 and 168 arithmetic operations, transfer 132 and 48 words, and peak at 48 and 32 words of slow storage. Their scratchpad peaks are 14 and 30 words, so their combined peaks are both 62 words: which memory level you mean matters. None of these counts predicts elapsed time without evidence about a particular implementation and machine.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
The same calculation as runnable code, in the notation of the derivation.
import numpy as np

def softmax(x):
    m = float(x.max())
    e = np.exp(x - m)
    return e / e.sum()

def attn_out_stream(scores, values, block=2):
    m, l, o = -np.inf, 0.0, 0.0
    for i in range(0, len(scores), block):
        sb = scores[i:i+block]
        vb = values[i:i+block]
        mb = float(sb.max())
        eb = np.exp(sb - mb)
        lb = float(eb.sum())
        ob = float((eb * vb).sum())
        m_new = max(m, mb)
        l = np.exp(m - m_new) * l + np.exp(mb - m_new) * lb
        o = np.exp(m - m_new) * o + np.exp(mb - m_new) * ob
        m = m_new
    return o / l

s = np.array([2.0, 1.0, -1.0, 0.5, 3.2, -0.3])
v = np.array([0.1, 0.2, -0.4, 0.0, 0.7, 0.3])

out_full = float((softmax(s) * v).sum())
out_stream = float(attn_out_stream(s, v, block=2))
print("full:", round(out_full, 6), "stream:", round(out_stream, 6), "diff:", round(abs(out_full - out_stream), 9))
This second program uses only the standard library. It computes both outputs and the integer cost counts derived above. The figure on this page counts the same operations, allocations and transfers as it runs, and the two counts agree. Neither measures your computer. Each case runs from the same arrays.
from math import exp, sqrt, ceil, isfinite

Q = [[1., 0.], [0., 1.], [1., 1.], [-1., .5]]
K = [[1., 0.], [0., 1.], [1., -1.], [-.5, 1.]]
V = [[1., 0.], [0., 2.], [-1., 1.], [2., -1.]]
MASK = [[j <= i for j in range(4)] for i in range(4)]

def inspect(q=Q, k=K, v=V, mask=MASK, tile=2, capacity=32):
    n = len(q) if isinstance(q, (list, tuple)) else 0
    d = len(q[0]) if n and isinstance(q[0], (list, tuple)) else 0
    if not 1 <= n <= 8 or not 1 <= d <= 4:
        raise ValueError("Use 1-8 tokens and 1-4 features")
    def matrix(a):
        return isinstance(a, (list, tuple)) and len(a) == n and all(
            isinstance(row, (list, tuple)) and len(row) == d and all(
                type(x) in (int, float) and isfinite(x) and abs(x) <= 4 for x in row)
            for row in a)
    if not all(matrix(a) for a in (q, k, v)):
        raise ValueError("Q, K, V must have the same bounded finite shape")
    if not isinstance(mask, (list, tuple)) or len(mask) != n or not all(
            isinstance(row, (list, tuple)) and len(row) == n
            and all(type(x) is bool for x in row) and any(row) for row in mask):
        raise ValueError("Every mask row must allow at least one key")
    if type(tile) is not int or not 1 <= tile <= n:
        raise ValueError("Invalid tile width")
    if type(capacity) is not int or not 1 <= capacity <= 4096:
        raise ValueError("Invalid capacity")
    dense_fast, tiled_fast = n+2*d+6, 4*tile*d+tile*tile+2*tile+6
    if max(dense_fast, tiled_fast) > capacity:
        raise ValueError("Schedule exceeds scratch capacity; no spill is modeled")

    scale = 1/sqrt(d)
    scores = [[sum(a*b for a, b in zip(qi, kj))*scale for kj in k] for qi in q]
    dense = []
    for i, row in enumerate(scores):
        maximum = max(s for j, s in enumerate(row) if mask[i][j])
        weights = [exp(s-maximum) if mask[i][j] else 0. for j, s in enumerate(row)]
        total = sum(weights)
        weights = [w/total if mask[i][j] else 0. for j, w in enumerate(weights)]
        dense.append([sum(weights[j]*v[j][h] for j in range(n) if mask[i][j]) for h in range(d)])

    streamed = [[0.]*d for _ in range(n)]
    trace = []
    for i in range(0, n, tile):
        r = min(tile, n-i)
        maxima, sums = [-float("inf")]*r, [0.]*r
        numerators = [[0.]*d for _ in range(r)]
        for j in range(0, n, tile):
            keys = list(range(j, min(j+tile, n)))
            # Compute every score; skipping masked tile loads is not this schedule.
            block = [[sum(q[i+a][h]*k[b][h] for h in range(d))*scale
                      for b in keys] for a in range(r)]
            for a in range(r):
                allowed = [b for b in keys if mask[i+a][b]]
                old, alpha = maxima[a], None
                if allowed:
                    new = max(old, max(block[a][b-j] for b in allowed))
                    alpha = 0. if old == -float("inf") else exp(old-new)
                    weights = {b: exp(block[a][b-j]-new) for b in allowed}
                    sums[a] = alpha*sums[a] + sum(weights.values())
                    numerators[a] = [alpha*o + sum(weights[b]*v[b][h] for b in allowed)
                                     for h, o in enumerate(numerators[a])]
                    maxima[a] = new
                trace.append(dict(query=i+a, keys=keys, allowedKeys=allowed,
                    oldMax=old if isfinite(old) else None,
                    max=maxima[a] if isfinite(maxima[a]) else None, scale=alpha,
                    sum=sums[a], numerator=list(numerators[a])))
        for a in range(r):
            streamed[i+a] = [o/sums[a] for o in numerators[a]]

    allowed_count = sum(sum(row) for row in mask)
    active = sum(any(row[j:j+tile]) for row in mask for j in range(0, n, tile))
    dot_work = n*n*(2*d+1)  # Declared schedule, including addition from zero.
    def result(output, arithmetic, exps, comparisons, reads, writes, slow, fast):
        return dict(output=output, counts=dict(arithmetic=arithmetic,
            exponentials=exps, comparisons=comparisons, readWords=reads, writeWords=writes),
            peakSlowWords=slow, peakFastWords=fast, peakCombinedWords=slow+fast)
    materialized = result(dense, dot_work+allowed_count*(3+2*d), allowed_count,
        allowed_count, n*d+n*n*d+2*n*n+allowed_count*d, 2*n*n+n*d,
        4*n*d+n*n, dense_fast)
    tiled = result(streamed,
        dot_work+allowed_count*(2+2*d)+(active-n)+active*(d+1)+n*d,
        allowed_count+active-n, allowed_count+active,
        n*d+2*ceil(n/tile)*n*d, n*d, 4*n*d, tiled_fast)
    tiled["onlineRows"] = trace
    return dict(dense=materialized, streamed=tiled)

if __name__ == "__main__":
    for width in (1, 2):
        result = inspect(tile=width)
        for name in ("dense", "streamed"):
            row = result[name]
            print(width, name, row["output"], row["counts"])
            print("peak slow/fast/combined words", row["peakSlowWords"],
                  row["peakFastWords"], row["peakCombinedWords"])
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
Change an input, predict the result, and see which quantities respond.
Optional and ungraded. Opening a guide saves nothing.
Choose what to inspect in FlashAttention: IO-Aware Attention, then open its guide.
Optional investigation · one attention calculation
Can an implementation do more arithmetic yet move less data?
Follow the memory. Four tokens · causal mask · fixed case
Q, K, V: queries, keys, values. S: scores; P: probabilities; wⱼ: unnormalized weights. m: running maximum; ℓ: denominator; Õ: unnormalized output. O = Õ / ℓ. Aᵢ: keys allowed for query i. Indices start at 0; a:b excludes b.
allocate · Reserve scalar workspace
Reserve 6 fast-memory words for scalar workspace; reserving space transfers no data.
Warm outline: current event. Empty space: no live buffer. Each w is one eight-byte word; block areas are schematic. Six scalar workspace words stay reserved. Counts follow the simple memory model defined for this example; the table below counts exponentials and comparisons separately. Home / End in the step controls jumps to the first / last event.
Same output, different memory work: dense transfers 132 words; tiled transfers 48. Fast-memory peaks are 14 and 30 words. The largest output difference is 1.11e-16 (below 10⁻¹²).
A silent, 32-second recording of query 3 from the fixed causal, tile-2 trace. The selectors below do not change the recording.
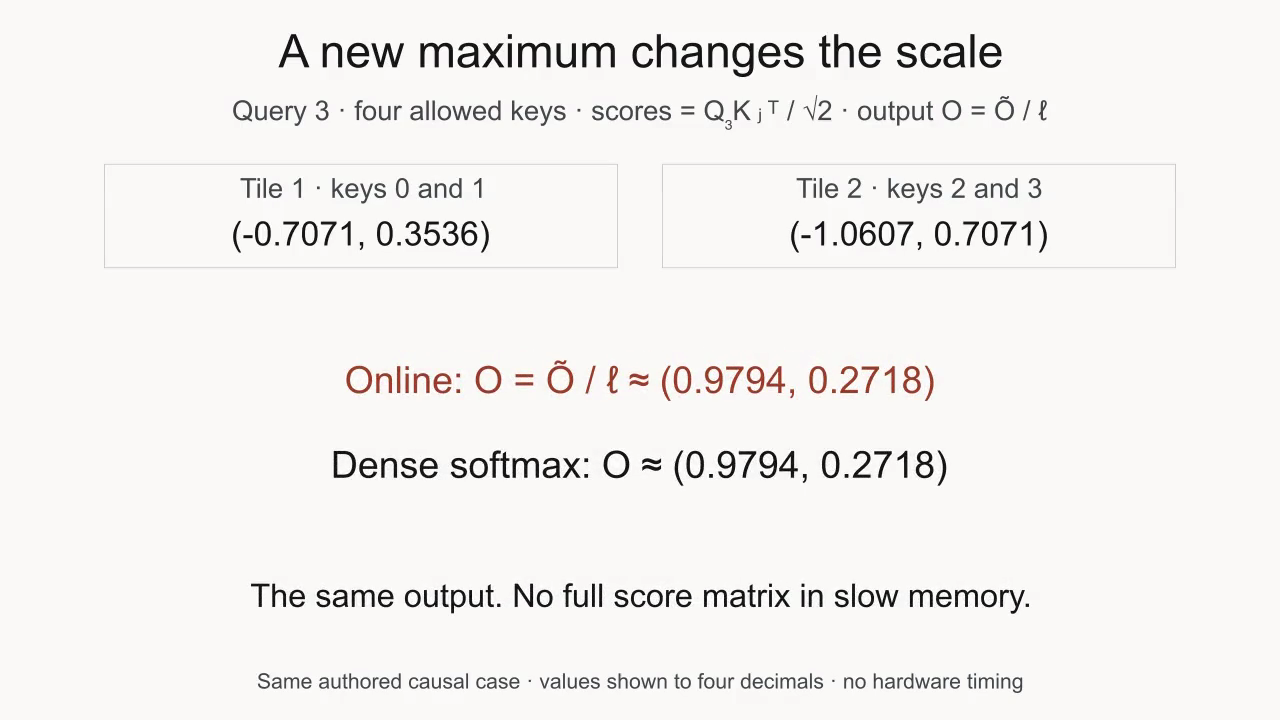
m is the running maximum; ℓ is the sum of shifted exponential weights; Õ is their value-weighted numerator. The output is O = Õ / ℓ. Scores are Q₃Kⱼᵀ / √2; all four keys are allowed for query 3.
One head, four tokens, two features. A token’s query is compared with allowed keys; their softmax weights mix the value vectors. Each output is still a two-feature vector.
| Token | Q | K | V | Allowed keys |
|---|---|---|---|---|
| 0 | [1, 0] | [1, 0] | [1, 0] | 0 |
| 1 | [0, 1] | [0, 1] | [0, 2] | 0, 1 |
| 2 | [1, 1] | [1, -1] | [-1, 1] | 0, 1, 2 |
| 3 | [-1, 0.5] | [-0.5, 1] | [2, -1] | 0, 1, 2, 3 |
Rows are tokens; columns are features. Scores are dot products divided by √2. The causal mask allows j ≤ i; allowing all keys permits all four. Every row must allow at least one key.
Causal attention excludes future keys. Change tile width to change the execution order; change allowed keys to change the mathematical question. Both columns below always use the same current inputs and mask. Both schedules calculate all 16 scores, including positions excluded by the mask.
| Query | Materialized | Tiled |
|---|---|---|
| 0 | [1, 0] | [1, 0] |
| 1 | [0.330238, 1.339523] | [0.330238, 1.339523] |
| 2 | [0.203336, 1] | [0.203336, 1] |
| 3 | [0.979388, 0.27178] | [0.979388, 0.27178] |
Maximum component difference: 1.11e-16. Agreement is checked within 10⁻¹² + 10⁻¹¹ × |reference|. Query 0 can use only value 0, so its output is [1, 0].
Work: how many operations? Traffic: how many bytes cross the slow-store ↔ scratchpad boundary, including rereads? Live storage: what must fit at the same time, at each level?
| Quantity | Materialized | Tiled |
|---|---|---|
| Arithmetic operations | 150 | 168 |
| Exponential calls | 10 | 12 |
| Maximum comparisons | 10 | 16 |
| Bytes transferred | 1056 B | 384 B |
| Peak slow storage | 384 B | 256 B |
| Peak fast storage | 112 B | 240 B |
| Combined live peak | 496 B | 496 B |
The tiled schedule moves fewer bytes while doing more arithmetic. Its combined peak equals the materialized schedule’s: the smaller slow-store allocation is offset by a larger scratchpad live set. These counts do not predict a runtime.
Costs are calculated for a simple two-level memory model defined on this page, at eight bytes per number. Q/K/V and the output are included; the mask is treated as control logic and is never stored or transferred. Only the forward pass is counted, and nothing here measures a GPU or your browser’s memory.
Materialized reads 92 words and writes 40; tiled reads 40 and writes 8. The score/probability buffer is reused in place. Tiled maximum, sum and numerator stay in the scratchpad until a query tile finishes.
| Phase | Reads | Writes | Arithmetic |
|---|---|---|---|
| Scores to slow storage | 40 | 16 | 80 |
| Scores to probabilities, in place | 16 | 16 | 30 |
| Probabilities and values to output | 36 | 8 | 40 |
| Query rows 0–1 | 20 | 4 | 68 |
| Query rows 2–3 | 20 | 4 | 100 |
30 of 32 words fit. Setting both query and key tile widths to four needs 62 words and is infeasible under this budget. No spill is assumed. Slow Q/K/V/O occupy 32 words; materialized scores/probabilities add 16. The six reserved scalar workspace words are counted in both schedules.
Q/K/V already exist when counting begins. Reserving output or score storage is not counted as a write. Six scalar slots are reused for sums, the rescaling factor and scalar products; a vector copy would need its own allocation. Built-in operations such as exp count as single steps, and their own workspace is not counted.
Constants, indices, instructions, caches, allocation metadata and this explanatory trace are outside the model. Add/subtract/multiply/divide each count once; exponentials and maximum comparisons remain separate: materialized 10/10, tiled 12/16. The counts include dot-product additions from zero and exclude setup of 1/√2.
| Keys | Allowed | New max | Old-state scale | Sum ℓ | Numerator |
|---|---|---|---|---|---|
| 0, 1 | 0, 1 | 0.353553 | 0 | 1.346227 | [0.346227, 2] |
| 2, 3 | 2, 3 | 0.707107 | 0.702189 | 2.116019 | [2.072403, 0.575091] |
When a new maximum arrives, multiply the old numerator and sum by exp(old max − new max) before adding the new weights. A wholly masked tile-row changes nothing. A row with no allowed key is rejected. The numerator divided by ℓ gives O.
The numerator is the sum of exp(score − current max) × value for allowed keys seen so far; ℓ is the sum of those same exponential weights. Rescaling both expresses their previous contributions relative to the new maximum. The current tiles and running state stay fast; the inputs still cross the boundary on every specified visit.
Dao et al., FlashAttention (2022), Figure 2 left reports attention forward + backward on A100: GPT-2 medium attention; 1,024 tokens; width 64; 16 heads; batch 64. These are the paper’s measurements, separate from the four-token calculation.
| Quantity | Standard | FlashAttention |
|---|---|---|
| Floating-point operations, billions | 66.6 | 75.2 |
| HBM read + write, GB | 40.3 | 4.4 |
| Runtime ms | 41.7 | 7.3 |
The reported timing ratio is about 5.71; the traffic ratio is about 9.16. More arithmetic accompanies lower time here, but the two ratios are not equal. The toy’s storage ratio supplies neither measured ratio. This table does not identify a universal bottleneck or predict speed on another workload.
Paper version: arXiv 2205.14135v2. The figure does not specify its exact dtype, mask/dropout settings, profiler counters, timing repetitions or synchronization procedure. It does not report full-model training time or peak storage. Appendix E.6 uses a different workload; its settings cannot fill these gaps. The toy has a query-outer schedule, eight-byte accounting and no backward pass; it does not reproduce this experiment or the paper’s Algorithm 1. The paper’s extra work includes backward recomputation; the toy’s extra forward rescaling is a different source of work.
Use the default example (causal mask, two-token tiles), whatever the controls above are set to. Solutions are available directly. This page does not grade or save your response.
Q, K and V each contain eight words. Two query tiles each visit all K and V. How many words are read and written? Why is that different from the peak slow allocation?
Count Q once, K and V once per query tile, and the final output once. Q/K/V/O remain allocated while transfers occur.
Reads: 8 + 2 × (8 + 8) = 40. Writes: 8. Total: 48 words, or 384 bytes. The slow peak is four eight-word arrays, 32 words or 256 bytes. Repeated visits count again as traffic without making another resident copy.
What stays fixed when tile width changes from two to one? Explain the traffic/scratchpad tradeoff. Then remove the causal mask: must query 0 remain [1, 0]?
Tile width preserves Q/K/V, the mask and output. Width one reloads all K/V for four query tiles: 80 transferred words instead of 48, but a fast peak of 17 instead of 30 words. Removing the mask permits future values; query 0 generally changes. Two schedules agreeing on an unmasked result cannot establish causal correctness.
Hypothetical, same-device forward-only comparison with equal outputs: A uses 64 MiB peak storage, transfers 64 MiB, performs 1.0 billion arithmetic operations and takes 4 ms. B uses 32 MiB, transfers 96 MiB, performs 1.5 billion operations and takes 6 ms. Does B’s smaller storage support a speed claim? What remains unknown, and what would you measure next?
B uses half the peak storage but takes longer in this hypothetical profile; both traffic and work increase. The table alone does not isolate which resource caused the delay. Keep the device, workload, correctness check, precision and what is timed fixed; repeat synchronized timings and inspect transfer counters and arithmetic utilization while varying one schedule choice. Memory capacity can still matter even if latency is worse. These numbers are hypothetical, not another paper measurement.
Review attention’s weighted averageConnect stored bytes to KV caching
The demo asks you to compare calculated storage for the selected dimensions, then shows how the online softmax state is merged across tiles. The storage calculation does not measure memory traffic or kernel speed. The point to keep: FlashAttention computes exact attention without ever storing the probability matrix.
Each button copies a prompt about this section to your clipboard, for an AI assistant you already use. Nothing is sent by this site.
What is the smallest example of FlashAttention you can work through by hand, and what does it show?
concept:attention-transformers/flash-attentionAfter the first pass
Section by section
Exact attention computed tile by tile with a running softmax, so the full T × T matrix is never written to GPU main memory; in the paper's benchmarks the reduced memory traffic made attention faster.
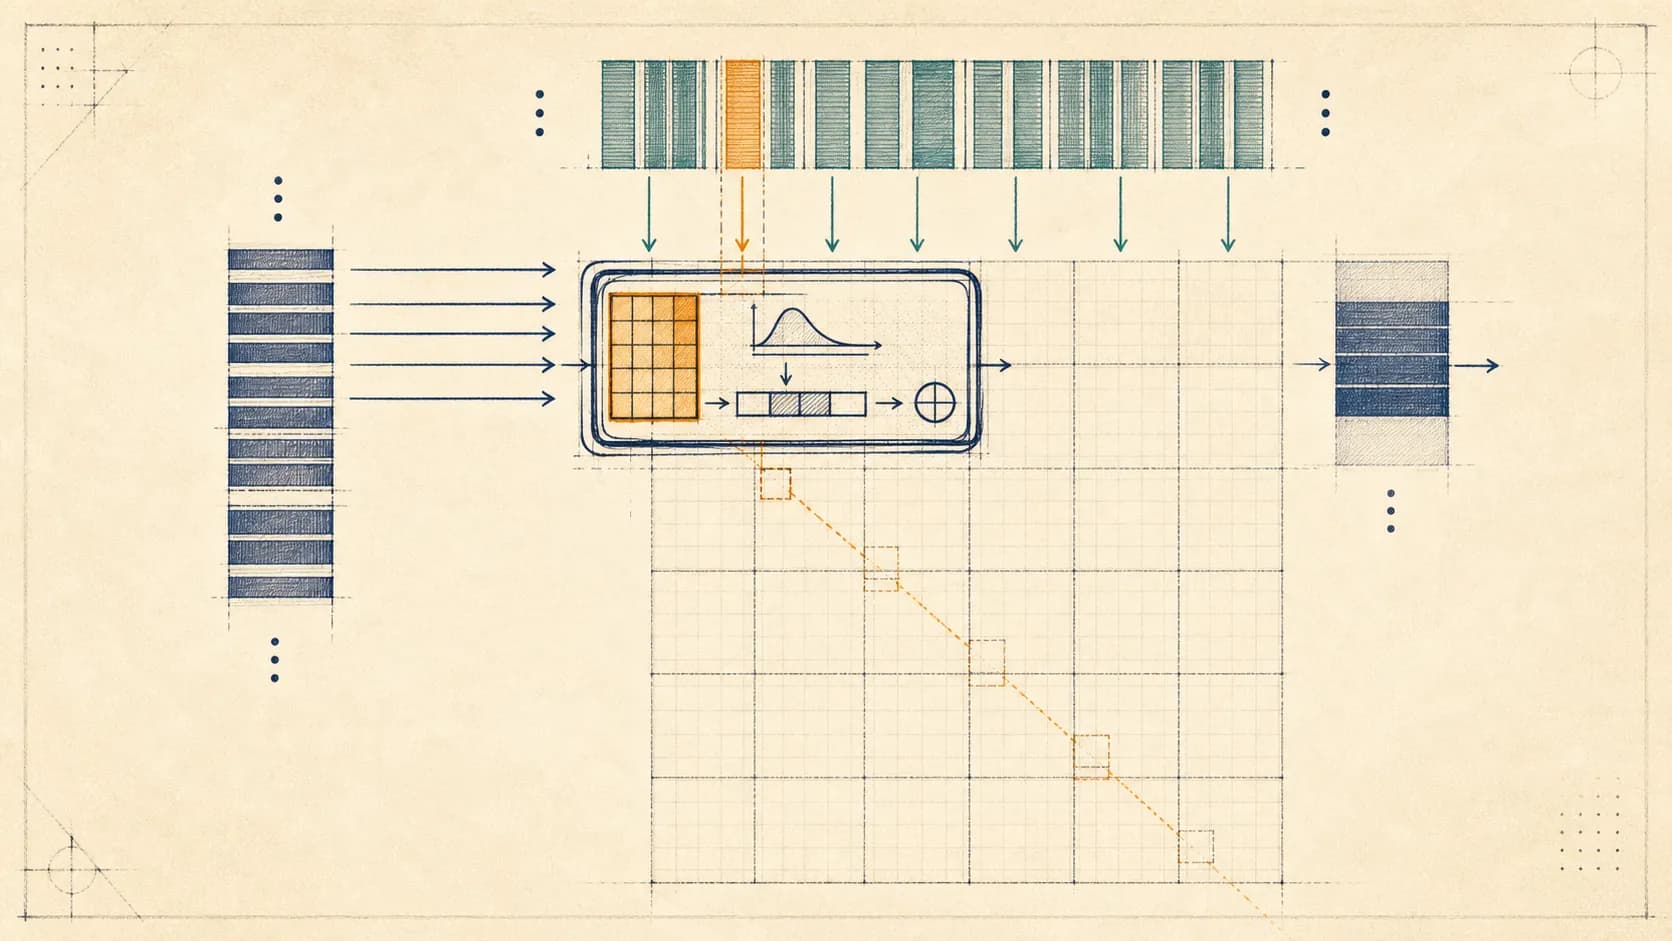
Choose what you expect to see in this section of FlashAttention: IO-Aware Attention.
Looking at the picture
Exact attention computed tile by tile with a running softmax, so the full T × T matrix is never written to GPU main memory; in the paper's benchmarks the reduced memory traffic made attention faster.
Pick the part of the picture you expect to explain FlashAttention: IO-Aware Attention.
Sources
NeurIPS 2022. Tiling between GPU main memory (HBM) and on-chip SRAM, with running softmax statistics, gives exact attention without writing the full N × N matrix (T × T here) to HBM.
arXiv preprint (NVIDIA). Computes the softmax normalizer in one pass by keeping a running maximum and rescaling the running sum when the maximum changes: the merge rule used here.
Figure 2 left: A100, GPT-2 medium, sequence length 1,024, head width 64, 16 heads, batch 64, forward plus backward. Reports arithmetic, HBM traffic and time; number format, mask, dropout and timing method are not stated.
Claims and sources
The checks were made by this site, not by an independent reviewer.
Dao et al. frame FlashAttention as IO-aware exact attention using HBM/SRAM tiling; Algorithm 1 updates block softmax statistics and returns O=softmax(QK^T)V while avoiding reads/writes of the full N x N atte...
"Online softmax" means the paper's block-wise/incremental softmax statistics. This checks the dense FlashAttention mechanism, not block-sparse variants, CUDA numeric equivalence, backward-pass implementation...
Checked Dao et al. against the exact claim: the paper presents FlashAttention as exact attention, uses HBM/SRAM tiling, maintains block softmax statistics (m,l,O) to compute the same softmax(QK^T)V result, and avoids reading/writing the full N x N attention matrix to HBM; the mathematics, code and figure on this page show the same running-softmax merge on small rows.
Figure 2 supplies the stated A100 attention profile. The query-outer schedules, eight-byte words, 32-word scratchpad, mask-as-control convention and cost counts are this page's own conventions, checked separ...
The small example is forward-only and is neither Algorithm 1 nor a hardware benchmark. Figure 2 is forward plus backward, and some of its settings are not stated. Storage, traffic and timing ratios differ; n...
Checked the cells and caption of Figure 2 (arXiv v2) against the stated hardware, workload and passes. The page's output was checked separately with high-precision decimal arithmetic, and its cost counts by listing every operation, transfer and allocation. Agreement between the page's Python and TypeScript is separate from the paper's GPU measurements; it neither reproduces the paper nor measures learning.
Practice · FlashAttention: IO-Aware Attention
Exact attention computed tile by tile with a running softmax, so the full T × T matrix is never written to GPU main memory; in the paper's benchmarks the reduced memory traffic made attention faster.
Concept · Selected for practice
What it rests on: Sources: FlashAttention: Fast and Memory-Efficient Exact Attention with IO-Awareness; Online normalizer calculation for softmax; FlashAttention (20...
Attention & Transformers
For FlashAttention: IO-Aware Attention: What is the smallest example of FlashAttention you can work through by hand, and what does it show? Explain your answer, including what changes, why, and which assumption matters.
A rough first thought is enough. Your draft stays when you change tasks.
Your draft stays on this page and is cleared when you leave or reload.
Open one hint at a time. These are suggestions, not your answer or a grade.
0 of 3 hints shown for this question.
Clearing your answer keeps this help record. Outside help is your own report; this page cannot check it.
No AI feedback runs here. You can copy a prompt to use elsewhere; nothing is sent automatically. Review the text before sharing, and leave out private information.
Write an attempt before copying a feedback prompt.
A draft, or an AI reply to it, is not a test of what you have learned. To check that, try a different case later without help.
out_stream = float(attn_out_stream(s, v, block=2))Your question
Open the draft below to save one note and next action in this browser.
What is the smallest example of FlashAttention you can work through by hand, and what does it show?
Fixed prompts generated from this item. They are not comments from people or independent reviews.
The 3 cited sources must support this exact item, not just the surrounding topic.
Connect the definition to one equation, piece of code or demo before widening the discussion.
Change one input, then check that the same relationship holds in the mathematics, the code and the demo.
You can state the mechanism in your own words
This draft stays in this browser and is attached to this item only.
concept/concept-notebook/attention-transformers/flash-attention
concept:attention-transformers/flash-attention